Munich’s shift to practical open source, Meta and Apple’s AI partnership, and NVIDIA’s hardware-driven open AI models
October 21, 2026
Open Channels FM: Munich Bets on Open Source as Meta Apple and NVIDIA Drive Local AI and Hardware Choices
WordPress.org blog: Critical PHP Security Release
Due to the critical severity of the issues, site owners are encouraged to immediately update their installations of PHP. Your web host may already be working to update PHP and put web application firewall (WAF) rules in place to mitigate the vulnerabilities, but you should still check for updates from your web host and, if necessary, update PHP as soon as possible.
Within WordPress, you can see which version of PHP your site runs under Tools > Site Health > Info > Server. Many web hosts provide this information in your web hosting administration panel too.
These vulnerabilities are not specific to WordPress and affect any server that hosts a PHP application. No WordPress update is required or planned for these issues.
Versions of PHP prior to 8.2 no longer receive security updates from the PHP project.
If your site runs a version prior to this and you manage your own web hosting, you should consider taking your server offline while you prepare to update to a newer version of PHP. This advice is being published by several national cyber security agencies. To quote the UK National Cyber Security Centre:
Where immediate remediation is not feasible, organisations should consider taking the system offline until it can be fully mitigated.
Further information on wordpress.org:
WPTavern: #238 – Chris Huber on How Static Site Importer Makes Migrating Any Website to WordPress Easier Than Ever
Transcript
[00:00:19] Nathan Wrigley: Welcome to the Jukebox Podcast from WP Tavern. My name is Nathan Wrigley.
Jukebox is a podcast which is dedicated to all things WordPress. The people, the events, the plugins, the blocks, the themes, and in this case, how the Static Site Importer makes migrating any website to WordPress easier than ever.
If you’d like to subscribe to the podcast, you can do that by searching for WP Tavern in your podcast player of choice, or by going to wptavern.com/feed/podcast, and you can copy that URL into most podcast players.
If you have a topic that you’d like us to feature on the podcast, I’m keen to hear from you and hopefully get you, or your idea, featured on the show. Head to wptavern.com/contact/jukebox, and use the form there.
So on the podcast today we have Chris Huber. Chris’s journey with WordPress began in his college days, first as a writer and blogger, and eventually progressing to software engineering after moving his personal site, extrachill.com to WordPress in 2018, Chris went deeply into WordPress, developing custom plugins and exploring all the corners of the platform. His passion for experimentation and creative tech led him to Automattic where he now helps shape the WordPress experience as a software engineer.
Our discussion centres around two main topics, Data Liberation and the Static Site Importer tool.
We focus upon the evolving landscape of website migration and ownership. Chris explains how Data Liberation aims to make it easier for users to take control of their sites, whether they’re moving to WordPress from platforms like Wix, Squarespace, or Drupal, or just want portability for their data.
We also get into the Static Site Importer, which takes this a step further by converting any static HTML / CSS website into a fully editable WordPress block theme, headers, footers, and all.
Chris walks us through how these tools work in tandem, highlighting the mechanics behind website crawling, mapping HTML elements to Gutenberg blocks, and handling complex features like WooCommerce and calendars.
We talk about the continuous improvement of these tools, how each migration helps raise the bar for future imports, and how this project could fundamentally change the way people move websites between platforms.
If you’re curious about the future of website migration, and how WordPress is removing the hurdles for users who want to truly own and manage their content, this episode is for you.
If you’re interested in finding out more, you can find all of the links in the show notes by heading to wptavern.com/podcast, where you’ll find all the other episodes as well.
And so without further delay, I bring you Chris Huber.
I am joined on the podcast by Chris Huber. Hello, Chris.
[00:03:21] Chris Huber: Hey Nathan. Thanks for having me.
[00:03:22] Nathan Wrigley: Yeah, very welcome. Chris and I have never spoken before, but we’re going to be talking today about two things, data liberation, but also a tool that I’ve never used, but sounds really interesting. It’s called the Static Site Importer.
As is always the case, if you go to wptavern.com and search for the episode with Chris in it, you’ll be able to find all of the necessary links. In this case, it’ll be, GitHub pages and things like that.
But before we get stuck into it, Chris, would you mind just telling us a little bit about yourself, your background with WordPress, who you work for, that kind of thing?
[00:03:54] Chris Huber: So I’m Chris. I live in South Carolina. My background with WordPress is I started my own blog back when I was in college, that was 2011. But I wasn’t on WordPress at the time. I switched to WordPress around 2018, and I started getting more and more into it over the years. Now I work for Automattic as of about six months ago. And I’m a software engineer.
[00:04:14] Nathan Wrigley: Thank you. So before those six months, a lot of people in the WordPress space have this, I think, desire to end up at a place like Automattic where they can fully work just on WordPress. That’s my estimation anyway sometimes.
[00:04:26] Chris Huber: Definitely a dream job. I really love working on WordPress, and it’s super cool to be able to work at Automattic but I got into software engineering a little bit later in my WordPress career. I was more of a writer and a blogger at first, and over time my website started getting more advanced and I wanted to build more things on it.
And I got, I was an early adopter to AI, and I started learning a lot. Like as soon as I picked up AI, I started asking a lot of questions and turned my website, my personal WordPress site is called extrachill.com, and it’s kind of a WordPress multi-site like application with 60 custom plugins on it.
And I just, I just went crazy. That’s how I ended up at Automattic is because my website, some things I built on my website were like, attention on Twitter from some people who have been around WordPress for a good bit of time.
[00:05:15] Nathan Wrigley: Yeah, I’ve noticed this trend. I think there’s a trend in upper management. Let’s go for that phrase, for the more curious bits. The unusual, the interesting, the weird and the wonderful. I think there’s a bit of a movement right now to see that again.
Back in the day, I have grey hair, I am considerably older than you, I think Chris. And, when the internet began, I was old enough to be able to use a computer. The internet was a truly strange place. Nobody had the faintest idea what to do with it. And so everybody launched their crazy, unusual thing, and it was normal. And then everything became a bit of a homogenised version of the internet.
These social media platforms came along and normalised everything. And UIs settled down and UXs settled down, and got stuck in a rut. But now there does feel, especially in the WordPress space, as if there’s a desire create the unusual, and the weird and the wonderful, and that’s brilliant. That sounds like you’ve been hired to do just that.
What we’re going to talk about today is not that weird. It’s fairly useful though, I would say. And, there’s two parts to it. As I mentioned at the top of the show, there’s the data liberation part, and then there’s the static sighting importer.
I think we’ll go through them in turn, if that’s all right? Starting with the Data liberation. This was a phrase that I used to trot out a couple of years ago when the Data Liberation project began.
Do you want to just run and tell us what the Data Liberation Project is, what its goals are?
[00:06:42] Chris Huber: So the Daily Liberation Project has been ongoing since way before I started working on it. And it is basically, a lot of proprietary website building platforms make it really hard to get off of these platforms. Especially if you want to keep your website design. And that’s their business model is, they’re not open source.
So for a long time we have assumed that Data Liberation meant using WordPress. But recently we have changed that definition a little bit, and it just means turning any website into a portable copy that you can download, and do whatever you would like with.
So the data Liberation Agent that we have created actually can convert any URL into a portable copy. So you just give it a URL and it loads the site in a browser, and downloads every single page as a perfect copy with all the animations and everything. The only thing it doesn’t get is anything that’s inside the database, inside the site. Because it’s all happening on the outside of the site.
So that’s step one to our process.
[00:07:42] Nathan Wrigley: I think that’s great. I remember it being couched in terms of trying to onboard people from going to use the word rival, although that’s the wrong word, rival CMSs. So for example, Drupal and Joomla and things like that. The idea being that its really hard work.
It can be a lot of work getting a site from over there, Drupal, let’s say, and bringing it over to WordPress. And so there was an endeavour to make it point and clickable. And in, in the way that you’ve described it, all that you have to do really to get a fairly functional version of your website is to know the URL.
So you go to the original domain, you paste in the URL, some magical voodoo goes on in the background. And within a few moments, that site has been replicated, and hopefully it can then be migrated over to WordPress. But I suppose it goes a little bit further than that because it’s a two-way promise, isn’t it?
It’s not just that you can bring things into WordPress. The promise is that should you become fed up of WordPress, you could go in the other direction. You could go WordPress to Drupal. Or indeed you could go WordPress, WordPress. So you could use it as a migration tool or something like that.
So it isn’t just this importing mechanism, it really is liberation in the strictest sense of the word. It’s your data. Pick it up from wherever it is now. Take it to wherever the heck you want it to go, and we’ll enable you to do that.
[00:09:01] Chris Huber: Yeah, basically. Not even just Drupal, but places like Wix and Squarespace and Weebly and other website building platforms that might be proprietary and open source. Yeah, that’s step one to the process that we’re using.
[00:09:13] Nathan Wrigley: Okay, is there anything technical that we need to know about how that process works before we move on to the Static Site Importer? Or are the two things bound so that if we move on, it’ll all make sense in due course.
[00:09:24] Chris Huber: It will all make sense I think.
[00:09:25] Nathan Wrigley: Yeah. I’ll interrupt as I see fit.
So the next part of this jigsaw puzzle, now that we’ve got the data liberation piece under control is the Static Site Importer.
Now, this to me at least is new. I had not seen it. I caught a post by a colleague of yours, on maybe it was X or something like that. And I saw it and I thought, okay, that’s interesting. Static Site Importer, what does that mean? And I dug a little bit deeper, and that’s why you are on the podcast to explain it.
Okay, 10,000 mile view looking down, what’s the goal of the project? And then I suppose we can get into how it does it and all of that magical stuff.
[00:09:59] Chris Huber: So the goal of the project is to create WordPress Block Themes from a static HTML website. So any basic HTML, CSS, JavaScript website, converting it into a WordPress site, with the click of a button. So that’s the basic goal.
[00:10:15] Nathan Wrigley: Okay, so the idea here is that you see a website somewhere online, hopefully it’s yours. And then you take the URL, but rather than the sort of more generic approach that we just described with Data Liberation, this is then binding it into, you said theme. I’m going to go with blocks in my definition here.
For example, where there’s a paragraph. Inside the block editor, we would see a paragraph block. And if it was an image, we’d see an image block. And I guess if there was something on the left and something on the right, we’d see a, I don’t know, a group block or something like that. And the design would trickle down from there.
The tool itself would make assumptions based upon what it, I’m doing air quotes, sees. And then it would build it inside the block editor. But curiously, you said theme, so is it also building a theme in the background to take care of all the other, I don’t know, the headers and the footers and all of that kind of stuff as well?
[00:11:10] Chris Huber: Yeah, it is materialising an entire WordPress site from scratch. So the importer does take a URL, but how we’re using it in our tools is we are combining it with data liberation first.
So data liberation gives us that clean copy of the website. So the URL actually goes through data liberation, and then we take the portable copy created by data liberation, and import the whole entire website into WordPress. And it turns this static website into a WordPress site.
So it’s not just about URLs. It’s also about like AI generated websites that you might have on your computer that you might have generated with Claude or Codex. And you want to use it on WordPress. It’s traditionally been pretty hard to get a high quality block theme from an AI agent without a lot of iteration.
So this kind of sidesteps that need to iterate on the block theme, and pull your hair out with the AI who doesn’t understand so much about how to create a good block theme. And you just don’t bother with that, and you just convert it into a block theme on its own.
The point of it really is removing the responsibility from the AI to create the block theme.
[00:12:14] Nathan Wrigley: Okay. So the way that you described it, it sounded like, forgive forgive me if I’ve misunderstood this. It sounded like you use the tool, and we’ll get into how that works properly in a minute. You use the tool. You paste in a URL, that could be a locally hosted website, or it could be something out in the wild on the internet.
And then the data liberation part of it spins up. And then it sounds like there’s a blob of data somewhere, which the data liberation tool finally exports. So it does its bits. This blob of data is then consumed, and we can discuss what that is. Is that a plugin? How does that even work?
And then once it’s parsed that blob of data, then it can figure out, okay, this part belongs in the header, this part belongs in the footer.
This part is the main content area, this is the homepage. And so on. How does it do that? How does it shatter out particular URLs? Like this is the about us page. Or do you have to do it page by page? About, home, archive? How does it do all that? Is it literally one URL and it goes around and spiders the whole thing?
[00:13:13] Chris Huber: It crawls every page on the website, the data liberation part does. But I think of the importer almost like a giant funnel and like a sorting mechanism. And it’s very much mapped to Core, WordPress Core. So I built the whole thing’s built with AI and just basically like over time mapping different elements on the page to Gutenberg, while having the AI read Gutenberg Core directly, and read the source and make its own mappings.
And the whole thing is just a series of import, a website, see what breaks. I pull it up on my screen, side by side. And I’ll be like, all right, this looks wrong, like this and this. And then you just run it again. And I wrote a prompt basically, an AI orchestration prompt that teaches the AI how to run this loop, like for a long period of time.
So how I’ve built it is I’ve basically just given the AI a URL, and had multiple sessions going side by side, working on different types of URLs. And they just run, and open pull requests.
The assumption that a lot of people would make about something like this is you take the HTML site and you tell the AI how to build the block theme from it. We’re not using the AI to do that. We’re using the AI to improve on the importer. So that every time we run an import, it raises the floor just a little bit. So the more sites that you run through it and loop on it like this, the better quality overall you’re going to get for just a random, arbitrary website that you might feed it.
So it’s really just about data annotation, and taking as much as you can in finding ways to parse it without having to look at it.
[00:14:41] Nathan Wrigley: Does the tool phone home. So the way you described it there was, it sounds like there was an opportunity to improve the tool for yourself on your install. But I was wondering if it phoned home so it also at the same time, improved the tool for everybody else so that the next version of the tool is better for everybody?
But I’m going to guess that it is just working locally. It’s improving your version each time. But I could be wrong.
[00:15:05] Chris Huber: So the prompt I share with my coworkers, and we all use it to work on the tool, so it’s more of a development thing is how I’ve built the tool is just by importing a tonne of different websites, over and over again. But the way I have it set up on GitHub is every merge to main automatically releases a new version and updates all the pins.
So the latest release is always the latest work that I’ve done. So, I get to benefit from the changes right away. As soon as I merge the PR, it’s in a new release and I can just keep going. It’s just not on wordpress.org yet, or anything like that.
[00:15:37] Nathan Wrigley: So how do we actually get hold of the tool? I’m going to link to a, a GitHub page, but just reading it into the record, it’s actually a fairly straightforward url. It’s github.com/automattic. You know the one with the two T’s, and then static-site-importer. You can go over there.
How does it work? You download it. You run it locally on your machine? And then once that’s up and running, what do you see? Is there like a GUI that you have to run through? Is there a WordPress plugin component to it? Just describe the workflow.
[00:16:07] Chris Huber: Okay. Yeah, so the Static Site importer is a WordPress plugin. And anyone can instal it on a WordPress site to turn a website into a WordPress site for sure. Using the command line locally. It works in the browser too, but there’s no UI. It’s like API based, so you’d have to call the API to do it or the CLI.
Another place to use it and the easiest, probably the easiest place for anyone listening, to try it other than Riad’s website, is WordPress Studio. I added a tool to the CLI in WordPress Studio. That is, studiocreate-from. And then you can enter a URL. So it’s just one CLI command, and that orchestrates the whole thing in the background. Loads the Data Liberation agent, and then installs Static Site Importer on the site.
You run it once you wait 10 or 15 minutes, and it spits out a WordPress Studio site that’s built using this tool. And that is the same way we run it on wordpress.com. Riad’s tool, the liberate.sh is a, it uses the wordpress.com API, which works the exact same way as WordPress Studio, where it loads Data Liberation Agent.
And Riad’s website gives you a copy of the website that you can download and take with you, anywhere you want. A WordPress website, anywhere. You can host it anywhere. but it’s all using the same wordpress.com API on the backend. Except in WordPress Studio uses the actual tools, does that make sense?
[00:17:21] Nathan Wrigley: Thank you. That’s great. And so how successful is it? If you point it at google.com, it’s probably going to a fairly easy time with it because there’s not a lot going on. But, i’m imagining on a, let’s imagine that you went to some high-end sports website or something where they’ve got animations of people and videos, and all sorts of stuff going on.
How does it hold up? For paragraphs and images and all of that kind of stuff? I’m guessing it’s pretty good. Are there any areas where you’d need to be a little bit more mindful? Because, I don’t know, just experience shows it doesn’t work out so well.
[00:17:53] Chris Huber: Yeah, definitely. So if you’re watching it today, there might be some failures on things like stores. Things that have a lot of products and like really image heavy websites might have problems as well. And just like really large websites. But it gets better every single day. What I say right now might become outdated very fast on what we can and can’t handle, but it definitely is not like perfect yet, for sure.
A small website, like a one page brochure website, or five pages or so. Most of the time you’ll get a pretty good copy of it. If you start to scale up to a really big, large, for example, wix.com, like the actual Wix.
[00:18:30] Nathan Wrigley: Good luck.
[00:18:31] Chris Huber: I sometimes will run that through there as a way to see how far I can get. Yeah, I’m trying to reach for the stars. So eventually I would love to be able to import this 50,000 page heavy duty, old school website, but right now it fails miserably, and it would take. The timing that was given to me last night when I was working on this was like two weeks. You’ll have a copy of wix.com, if you just let it run. And then you’d get the copy and it would just be like 10,000 pages of nonsense. We have a lot of work to do.
[00:18:59] Nathan Wrigley: Okay, but for a normal, typical, run of the mill, let’s go with brochure site, 12 pages, fairly ordinary stuff. Imagery, maybe a video here and there, but mostly text, CSS, maybe a tiny smattering of JavaScript sprinkled around. Forms, that kind of thing. It would do a pretty good job with that out of the box?
[00:19:17] Chris Huber: I would say like more than half the time you would get a good editable WordPress website. Not always perfect. And sometimes you would get a perfect site. But a lot of times you might have a few things that are wrong, like maybe a couple form fields, or like buttons or like menus.
One thing that happens a lot is like the header and the footer are like duplicated across every page, instead of being properly extracted into a template part. If there’s like SVG images, WordPress has a kind of a hard time handling those. So we have dealt with it. But it’s not always perfect.
One of the coolest things about it that I like is that blocks, so it’s static site importer is the WordPress plugin that creates the WordPress site. And then there’s a PHP package inside of it called Block Engine. Which is what handles the actual, like, mechanics of converting and creating the blocks.
And inside of that tool I have added some like carried blocks that are in the holster ready to go, like for common elements that might appear on websites in the wild.
So like a marquee or something like that. Like a ticker that you see running across a page that Gutenberg cannot represent on its own, out of, the box. And so this tool, it knows how to build this block as if it was part of Gutenberg, so that you’ll see a real block in there. That’s my WordPress nerd favourite thing about the tool. It feels like I’m pushing on Gutenberg, finding places where Gutenberg is like maybe falling short, or just doesn’t supply the things that people need to build websites. With the right amount of attention, this might help be like, oh, we need to add some of this stuff.
[00:20:48] Nathan Wrigley: A curious question, because we all know how AI never gives you the same thing twice. I was wondering if you fed it the same URL, do you predictably get something similar out? Or do you suffer each time a different set of, and I’m doing air quotes again, failures. So for example, you described, the SVG images, or the form fields, or the footers being duplicated or whatever it was.
Is it sometimes better just to begin again, and cross your fingers and hope that the AI has a better go the second time around? Or is it always a case of go with the first version and iterate from there?
[00:21:22] Chris Huber: So it works the same exact way every time. The actual process does not use any AI at all. I used the AI to build it from the outside. But the actual, It’s literally like a machine. The process doesn’t use any AI to convert the website. We have some stuff in place, like when we’re using it on wordpress.com. We’re doing migrations from non WordPress to WordPress sites, we do it for assisted migrations currently.
But the people running these migrations will use the tool first and see how far it gets them. And then they take Claude Code or whatever and they work on the site that came out. And they hand it over to the customer. So it gets them closer to the finish line than they would have gotten if they just had to start building the site from scratch on their own.
And then over time we’re getting closer to the finish line, and hopefully get to the point where we can just hand people the website coming from another source and be like, here’s your exact copy of your website WordPress version. And eventually we will make that like a publicly available thing. But that’s how we’re working on it internally, so.
[00:22:21] Nathan Wrigley: So I think I’d misunderstood there, so the AI portion is in the creation of the tool, but the tool itself is deterministic. The tool will give predictably the exact same thing out. If you give it the URL, it’s going to parse it with a mechanised approach? It’s not relying on AI at that point. And so do it once.
And then it sounded to me from the way you described it, you were holding your hands up at this point. It sounded like your had two screens open. You’ve got the output and then maybe the original. And you’re trying to iterate and just spot the errors. Okay, let’s scroll them both and see. Ah look, that’s gone a bit astray there.
And then presumably at this point you’re logging into WordPress. If it can be done inside the block editor, you’re doing it there. But it also sounded like you are now at .com. You are removing that part even and just doing a second run with AI at that point. Rather than logging into WordPress and using the block editor, it’s more CLI. Let’s just see if the AI can spot those mistakes, because I spotted them, prompt it and fix it in that way. That’s interesting.
[00:23:21] Chris Huber: So I’m the one just building the tool. There’s other people working on delivering websites to customers and stuff internally. But, I started looking at the websites originally, but now I have a, I just have a prompt that I copy and paste to the AI every time and it walks through the process.
And what it does is it loads both sites in a headless browser called Playwright. Basically, I have the AI look at the site as if it was the site owner. I say you’re a non-technical site owner. Open this site and look at the Gutenberg editor and see how you would feel if you came over from Wix and this was what you got.
It’ll go through and click things around in the editor and be like, okay, here’s my feedback. And then I say, okay, fix everything all at once and open pull requests. And it will fan out subagents, 10 or so at a time sometimes, and open pull requests in three repos, and then I just merge them and run it again. Because the automated releases that I mentioned.
So it’s very much trusting the machine and letting them. The machine in this case is, more able to parse this than, than a human is because it’s so much at once. And just letting them do it is what I’ve found. Describing to them what I want them to do.
[00:24:26] Nathan Wrigley: I’m guessing the onboarding team over on .com, presumably, if you roll the clock back a couple of years, this was all a very manual process. Find a client, get them to sign on the dotted line. Okay, they’ve got a.com account, now they want to move over. And then it would’ve been a process of, okay, let’s inspect the site, let’s get a bunch of technical people on it, and figure out what we need to migrate and when, and try to map it. Get a designer in and recreate graphics, and colour palettes, and brands and all of this kind of stuff. But it sounds like these people no longer have a, place because you just use the tool and in most cases it’s going to work.
Has that in fact been the case? It sounded like over on the .com side of things, there’s like this, I don’t know, 90, 95, 99%, trust in the tool now. That must be incredible. Presumably you can onboard people much more rapidly.
[00:25:14] Chris Huber: Yeah, it’s not quite that much of trust in the tool yet. It’s more one in 10 sites are getting close enough to the finish line to just be handed off. So like the original process that you mentioned is a good process for like a big site, like manual migrations and stuff. But for small sites it’s not really a good business model. It’s not economically viable to spend a lot of resources rebuilding a small website because you’re putting a lot of manual effort into one website.
So what we would do mostly in the past would be, if the customer is willing to do the do it for me route, where they have our team build it for them, we would do that. But otherwise we would offer them a content import. So they can just import all their blog posts or whatever, and then rebuild the site their own.
This kind of gives us an option for people that were historically told no, that we can now start saying yes to them. And letting them migrate over. It’s not necessarily about reducing the labour that was going into it because it was a dead end before, and now it’s not.
[00:26:10] Nathan Wrigley: And how has it been received over on the .com side of things? I’m presuming that you are in touch with these people. And even if it’s a one in 10 at the moment, we have expectations that it’ll be two in 10, and then three in 10, and by the end of next year, maybe nine in 10 or what have you.
That gives them the opportunity to talk about other things with the clients that they’re onboarding, I suspect. Instead of just, okay, let’s figure out how to make the exact same website that we had over there, over here. That doesn’t feel like necessarily interesting work anyway.
[00:26:36] Chris Huber: Yeah, exactly. But it was always really hard to make the exact copy. And yeah, the tool has a lot of internal support and a lot of internal attention. People are rallying behind it. It’s basically what I’ve been working on full time since WordCamp US. Three months ago now.
So I’ve been putting full-time effort into this tool for three months now. And now it’s starting. We have a lot of momentum behind it internally now that it’s starting to get to a point where it’s actually good. It’s very cool to see this for myself. I’m very proud of the work that we’ve done. And it’s exciting. It’s just exciting.
[00:27:06] Nathan Wrigley: We mentioned that there were some things that it didn’t do particularly well. Presumably it would be nice to be able to hoover up some of that in the future. What would be the roadmap items that you’ve got for the next, I don’t know, short period of time, month, two months, six months, whatever it may be. What are the bits that it can’t currently do, or the bits that there’s wrinkles in, that you could tell us about that hopefully, given the passage of time, will go away?
[00:27:30] Chris Huber: The more complicated stuff is like, installing another plugin when you’re materialising the website. So the the most obvious example is WooCommerce. If we’re detecting products in the source, we actually pre-install WooCommerce, and convert to WooCommerce blocks, and import actual products into the catalogue, and like wire up everything that we possibly can.
[00:27:50] Nathan Wrigley: That’s amazing.
[00:27:51] Chris Huber: It’s crazy, but it doesn’t work very well yet, because it’s very complicated. But, another thing is like is like events. Like an events calendar on a website, the tool kind of chokes on that, but it’s the same process. You install The Events Calendar plugin. You find the most widely supported and used WordPress equivalent of whatever feature you need, and you find a way to deterministically wire it up on the back end.
There is a WordPress equivalent for like most things. It’s just a one at a time process to pick the one that, at least for .com. The tool itself is composable. So any developer. For forms, we use Jetpack Forms. But any developer can hook in and do whatever form provider they want, if they provide their own mappings to the tool. That’s the kind of stuff that doesn’t work quite as well right now.
And, of course JavaScript animations and other things. WordPress has the Interactivity, API, so we do use that. More and more core blocks are coming in. Like we have the tabs now in the accordions and things like that, that we can actually represent in Gutenberg more effectively now.
The real solution is just keep importing sites, you find that the tool used to choke on, it doesn’t choke on anymore, and you get further. And you just keep getting further and closer to success. The only thing it chokes on, this site is the products. Okay, so we’ll just work on improving the WooCommerce integration.
Yeah. So it’s like almost as far as you can get and then just keep. I like to think of it as raising the floor, like raising the bar is like. This is as bad as it could possibly be, and then the next time it’s a little bit better.
[00:29:18] Nathan Wrigley: And it sounds like it’s going through those iterations fairly rapidly in terms of time, what three or four years ago would’ve been years into the future now increasingly feels like months, and then weeks, and then finally in a few years time, maybe days. A lot of this stuff will be taken on in short measure, things like an events system, or a WooCommerce system or an LMS kind of system. Maybe that stuff will be in scope in the near future.
The project, obviously being on GitHub, and being a WordPressy thing is open source and I’m, just curious whether or not you are doing this hand in hand with any other people? Or is it just a project within Automattic? Or are you getting kind of intuitions from WordPress agencies out there who are obviously having to do this kind of work?
They’re bringing in clients from all over the place and trying to convert them over to WordPress. I just wondered if there was any collaboration going on, or do you wish there to be collaboration?
[00:30:12] Chris Huber: I think something like this should be part of WordPress Core. I don’t know that necessarily this exact tool or this approach. There’s a lot of work in the ecosystem around this area, like Human Made has a tool like this. And then Pascal from WordPress Core, is working on this in Gutenberg, not the exact same thing, but some way to convert HTML to blocks.
And I just think it’s a big challenge for the WordPress ecosystem that if it gets solved can help move the whole project forward and help make us more future proof. Just because AI is so good at generating HTML, and that’s what kind of becoming the native format of the internet now. Maybe always has been, but just making that translatable into WordPress is something important I think.
[00:30:53] Nathan Wrigley: Yeah, I think so. And obviously in an era where market share in the WordPress space is no longer seemingly guaranteed to just keep climbing. People face with that decision of, okay, I’ve got a website, it’s now starting to look a bit stale, but rather than throw the baby out with a bath water, we’ll, okay, we want an alternative CMS. We want to upgrade, see where we can go. It feels like a tool like this makes WordPress a bit of a forerunner, actually.
If you’re going to pick a CMS, have a CMS where there’s a pretty good chance that by clicking a button you can bring most of your existing stuff across. I don’t know what the other CMSs do in that regard. Maybe they do nothing, but this does feel like a tool in WordPress’s arsenal, which is pretty compelling. I would hope that it would bring a lot of people in our direction.
[00:31:42] Chris Huber: I hope so too, and I agree. I think the fact that it can exist. It takes one of the points of WordPress that has been difficult for people to embrace, which is the block editor. And it almost turns it into an advantage. Because then you get a WYSIWYG version of every website. Whereas if you were to generate a static site with AI and go and host it on a static host, you don’t have the CMS. If you want to add another blog post, you have to generate the page, upload it to the site. And of course there are solutions to this.
What if you just want to change one word? You just want to go into the block editor and change the one word. Then you can do that and like without having to build the whole page from scratch in the editor. You have to be good at it and know what you’re doing to build a custom website using the block editor, I think.
[00:32:26] Nathan Wrigley: This is going to be a discussion which will go on, I think in the days, weeks, and months to come. Obviously everybody at the minute is very beguiled by the interface of building a website through some kind of chat mechanism. It’s so fascinating that’s possible.
But then the reality of maintaining that, and understanding how that page even got there. And where do the assets, on that page even live? And how do I modify the title of the hero section over here? All of that has yet to land with ordinary people. Again, doing air quotes.
[00:33:04] Chris Huber: Yeah.
[00:33:05] Nathan Wrigley: If you’re very technical, you can probably figure all that stuff out, because you were probably the person that created that AI based site anyway. But if you’re not technical and your job is just to occasionally modify content, or inspect somebody else’s content, and click publish when it met the guidelines that you’d got as an organisation. You’re not going to care about some sort of CLI interface or getting an AI to do that for you.
You just want to be in, out, and then move on, because WordPress is not what makes up the majority of your day. I think all of that stuff is going to hit us in 2027, and it’ll be interesting to see where we land and where the landscape moves.
[00:33:41] Chris Huber: Yeah, I hope that we can continue to grow WordPress definitely.
[00:33:45] Nathan Wrigley: Okay, that’s really interesting. I’ll read into the record one more time the tool itself. So github.com/auttomatic, two ts, /static-site-importer. You can go over there and make comments. It’s a GitHub page so you can do all of that normal stuff.
If people wanted to find you, Chris, do you hang out online anywhere? If people wanted to contact you and had intuitions on where this should perhaps go in the future?
[00:34:11] Chris Huber: Yeah, they can reach out to me on x x.com/chubes4, C-H-U-B-E-S four. They can also find my GitHub, which is the same tag. I have my personal WordPress site at extrachill.com, is like my main site. Then I have my other one, chubes.net. Or, just leave a pull request or a GitHub issue, me or my AI agent will reply.
[00:34:33] Nathan Wrigley: This is how it is in the year 2026.
[00:34:35] Chris Huber: Yeah.
[00:34:37] Nathan Wrigley: Okay Chris, absolutely fascinating. Let’s hope that the tool manages to do a lot more than you’ve described. It sounds like you’ve got a very extensive, and interesting, roadmap going on, but thank you for bringing that to us and, thank for explaining it all to us today. Appreciate it.
[00:34:49] Chris Huber: Yeah. Thanks for your time. Thanks for having me.
On the podcast today we have Chris Huber.
Chris’s journey with WordPress began back in his college days, first as a writer and blogger and eventually progressing to software engineering. After moving his personal site, extrachill.com, to WordPress in 2018, Chris went deeply into WordPress, developing custom plugins and exploring all the corners of the platform. His passion for experimentation and creative tech led him to Automattic, where he now helps shape the WordPress experience as a software engineer.
Our discussion centers around two main topics: Data Liberation and the Static Site Importer tool. We focused upon the evolving landscape of website migration and ownership. Chris explains how Data Liberation aims to make it easier for users to take control of their site, whether they’re moving to WordPress from platforms like Wix, Squarespace, or Drupal, or just want portability for their data.
We also get into the Static Site Importer, which takes this a step further by converting any static HTML / CSS website into a fully editable WordPress block theme, headers, footers, and all.
Chris walks us through how these tools work in tandem, highlighting the mechanics behind website crawling, mapping HTML elements to Gutenberg blocks, and handling complex features like WooCommerce and calendars.
We talk about the continuous improvement of these tools, how each migration helps raise the bar for future imports, and how this project could fundamentally change the way people move websites between platforms.
If you’re curious about the future of website migration and how WordPress is removing the hurdles for users who want to truly own and manage their content, this episode is for you.
Useful links
Chris’ extrachill.com website
Chris’ chubes.net website
Static Site Importer on GitHub
liberate.sh website
Donncha: Switching off PHP until upgraded
There’s going to be an emergency PHP release made in just over 2 hours. It’s to address a critical security bug.
I’m not sure how long it’ll be before Ubuntu updates, but I will preload a bunch of posts here and on inphotos.org using WP Super Cache and turn off PHP until it’s updated. The files will be served by Apache’s mod_rewrite, so no PHP involved at all. Uncached pages won’t be so lucky, but at least some pages will still be live.
#PHP #WordPressOctober 20, 2026
WordPress.org blog: WordPress 7.2 Beta 1 is Ready for Download and Testing
This beta release is intended for testing and development only. Please do not install, run, or test this version of WordPress on production or mission-critical websites. Instead, use a test environment or local site to explore the new features.
How to Test WordPress 7.2 Beta 1
You can test WordPress 7.2 Beta 1 in any of the following ways:
| WordPress Beta Tester Plugin | Install and activate the WordPress Beta Tester plugin on a WordPress install. Select the “Bleeding edge” channel and “Beta/RC Only” stream. |
| Direct Download | Download the Beta 1 version (zip) and install it on a WordPress website. |
| Command Line (WP-CLI) | Use this WP-CLI command: wp core update --version=7.2-beta1 |
| WordPress Playground | Use a 7.2 Beta 1 WordPress Playground instance to test the software directly in your browser. No setup required-just click and go! |
The scheduled final release date for WordPress 7.2 is December 8, 2026. The full release schedule can be found here. Your help testing Beta and RC versions is vital to making this release as stable and powerful as possible. Thank you to everyone who contributes by testing!
Editing Experience
Responsive Design Controls
Building on the responsive design improvements introduced in WordPress 7.1, WordPress 7.2 expands viewport-specific styling to additional design tools and blocks. Creators gain more granular control over how layouts and visual settings adapt across screen sizes, including responsive Gallery settings for columns, image cropping, and aspect ratios.
Learn more: GitHub #80388, #82003
Improved Global Styles and Design Tools

WordPress 7.2 makes site-wide styling easier to manage with a new Customized filter for finding blocks with modified styles and inherited Global Styles values displayed directly in block inspector controls. Expanded design tools and support for styling form elements provide additional flexibility when creating a consistent visual identity across a site.
Learn more: GitHub #82520, #76525, #34198, #84657
Text Shadow Support
WordPress 7.2 introduces new text shadow controls, giving creators more ways to add depth and emphasis to their content. Text shadows can be customized through block settings and defined as presets in theme.json, making it easier to maintain consistent typography across a site.
Learn more: GitHub #73320, GitHub #79584, Trac #65869
Easier Navigation Management
Improvements to the Site Editor make managing navigation links more intuitive. Creators can add, organize, and edit navigation items directly from the editor sidebar, making it easier to maintain site menus without interrupting their editing workflow.
Learn more: GitHub #77069
Better Collaboration with Notes

WordPress 7.2 introduces Emoji reactions on notes and a new toolbar icon that makes Notes easier to access and manage. Notes move to the editor canvas, bringing conversations directly into the margin. Users can now keep Notes and the block settings sidebar open simultaneously, making it easier to review feedback while editing content.
A new minimized Notes mode reduces visual clutter, while improvements to positioning and display create a smoother, more consistent collaboration experience.
Learn more: GitHub #79970, GitHub #83786, GitHub #80015, Trac #64638
Faster, More Efficient Media Uploads
WordPress 7.2 expands client-side media processing to the Media Library, allowing images to be resized, compressed, and converted directly in the browser before being uploaded. This can improve upload performance, reduce server resource usage, and provide better support for modern image formats, particularly on hosting environments with limited image-processing capabilities.
Learn more: Trac #65661, GitHub #12585
New “On This Day” Dashboard Widget
WordPress 7.2 introduces a new On This Day dashboard widget that helps users rediscover content published on the same date in previous years. By highlighting posts from the site’s history, the widget makes it easier to revisit past content, celebrate milestones, and find opportunities to refresh or reshare older posts.
Learn more: Trac #65116
Block Editor Usability Improvements
WordPress 7.2 includes a collection of smaller improvements aimed at reducing friction in everyday editing. These changes include clearer error messages, more helpful feedback when something goes wrong, and refinements to common editor interactions, making the editing experience more predictable and approachable.

Learn more: GitHub #81453, #82496, #84656, #84649
A More Consistent WordPress Admin
WordPress 7.2 continues modernizing the administration experience by replacing legacy Dashicons in the admin bar and sidebar with icons from the WordPress icon library. The updated icons bring greater visual consistency between the traditional WordPress dashboard and newer editing interfaces.
Learn more: GitHub #12270
An Updated Block Settings Experience

A new DataForm-powered inspector introduces a refreshed approach to managing block settings in the editor. Built on the DataForm component system, this work aims to provide more consistent controls and a more extensible foundation for future block editing improvements.
Learn more: GitHub Gutenberg · Call for Testing
Faster WordPress Administration
WordPress 7.2 improves admin performance by modernizing how scripts and stylesheets are loaded. Instead of combining assets into large files, WordPress now loads them individually for better browser caching. A new prefetching mechanism also anticipates which admin screen users are likely to visit next, loading its resources in advance to make navigation between the dashboard, post lists, and editor faster.
Learn more: Trac #57548
For Developers
New Secrets API
WordPress 7.2 introduces a Secrets API, providing developers with a standardized, secure way to store sensitive credentials such as API keys and authentication tokens. The API supports encryption at rest, credential rotation, and customizable storage providers, helping plugins and integrations manage sensitive information more securely.
Random Content Redirects
WordPress 7.2 adds support for random content redirects, allowing visitors to discover a randomly selected post through a dedicated URL. This provides a simple way to encourage content exploration and help readers rediscover older posts.
Learn more: Trac #64498
More Powerful APIs for Developers
WordPress 7.2 expands the Abilities API with new capabilities for accessing and querying WordPress data, providing a more consistent foundation for integrations, automation, and AI-powered tools. (Trac #66268, #64605, #64657)
Enhancements to the Interactivity API introduce new ways to render trusted HTML and manage reactive navigation, giving developers more flexibility when building dynamic, interactive blocks. (Trac #66246, Gutenberg PR #83092)
Additional improvements to the HTML API, block supports, and responsive design tools provide more reliable markup processing and greater control over how custom blocks are styled and displayed across devices. (Trac #65824, #66150, #65869)
How important is your testing?
Testing for issues is a critical part of developing any software, and it’s a meaningful way for anyone to contribute – whether or not you have experience. Details on what to test in WordPress 7.2 are available here.
If you encounter an issue, please share it in the Alpha/Beta area of the support forums. If you are comfortable submitting a reproducible bug report, you can do so via WordPress Trac. You can also check your issue against this list of known bugs.
Curious about testing releases in general and how to get started? Follow along with the testing initiatives in Make Core and join the #core-test channel on Making WordPress Slack.
WordPress 7.2 will include new features that were previously only available in the Gutenberg plugin. Learn more about Gutenberg updates since WordPress 7.1 in the What’s New in Gutenberg posts for versions 23.7, 23.8, 23.9, 24.0, 24.1, 24.2, and 24.3.
What’s new in WordPress 7.2?
With so much in progress for WordPress 7.2 Beta 1, this is still only the beginning; expect continued refinement with each Beta and RC release ahead of the final release on December 8, 2026
Just for you: a Beta 1 haiku:
Ipsum takes the stage
Secrets bloom, designs take shape
New blocks come alive
Props to @audrasjb, @annezazu, @adamsilverstein, @westonruter, @markoserb, @im3dabasia1, @jorbin, and @noruzzaman for proofreading and review.
Open Channels FM: Community Without the Noise, Revisited
A commentary on building meaningful online communities that prioritize value and listening over constant activity.
OpenStation Blog: OpenStation: turn wp-admin into a desktop, and try it in 30 seconds
OpenStation is a free WordPress plugin that turns wp-admin into a desktop. Every admin screen opens in its own window that you can move, resize and keep open next to the others. You can try it in your browser right now, with nothing to install.
Can’t see the video? Watch it on YouTube.
Why we built it
Most of us spend the day jumping between screens in wp-admin. You open a post, go back to the list, check the media library, then go back again. With OpenStation, those screens stay open side by side, so you don’t lose your place.
What you get
- A window for every admin page: posts, media, settings, plugins
- A dock with your whole admin menu, including your other plugins
- Several desktops, for example one for writing and one for site settings
- Wallpapers, widgets and accent colors
- Cmd+K to jump anywhere fast
- Your windows are still open when you come back
Try it in your browser
Go to the OpenStation page on WordPress.org and click Live Preview. It runs a full WordPress site with OpenStation in your browser tab, so you can’t break anything.
Install it on your site
- In your admin, go to Plugins → Add New and search for “OpenStation”
- Click Install Now, then Activate
- Click the desktop icon in the top-right corner of the admin bar
It’s safe to try
OpenStation is opt-in for each user, so the rest of your team keeps the normal admin. Click the same icon to go back to the classic view. If you deactivate the plugin, wp-admin goes back to exactly how it was. It doesn’t change WordPress core.
Tell us what you think
Have a question? Ask in the support forum. Found a bug or have an idea? Open an issue on GitHub.
Open Channels FM: More Code, More Problems? What AI-Generated Software Means for Us
AI tools have simplified app creation, enabling rapid prototyping. However, the challenge now lies in discerning which ideas are genuinely valuable to users. As anyone can create apps quickly, the focus should shift from mere production to understanding user needs and ensuring the apps solve real problems to avoid mediocrity.
October 19, 2026
Donncha: Travel Steps is a travel journal
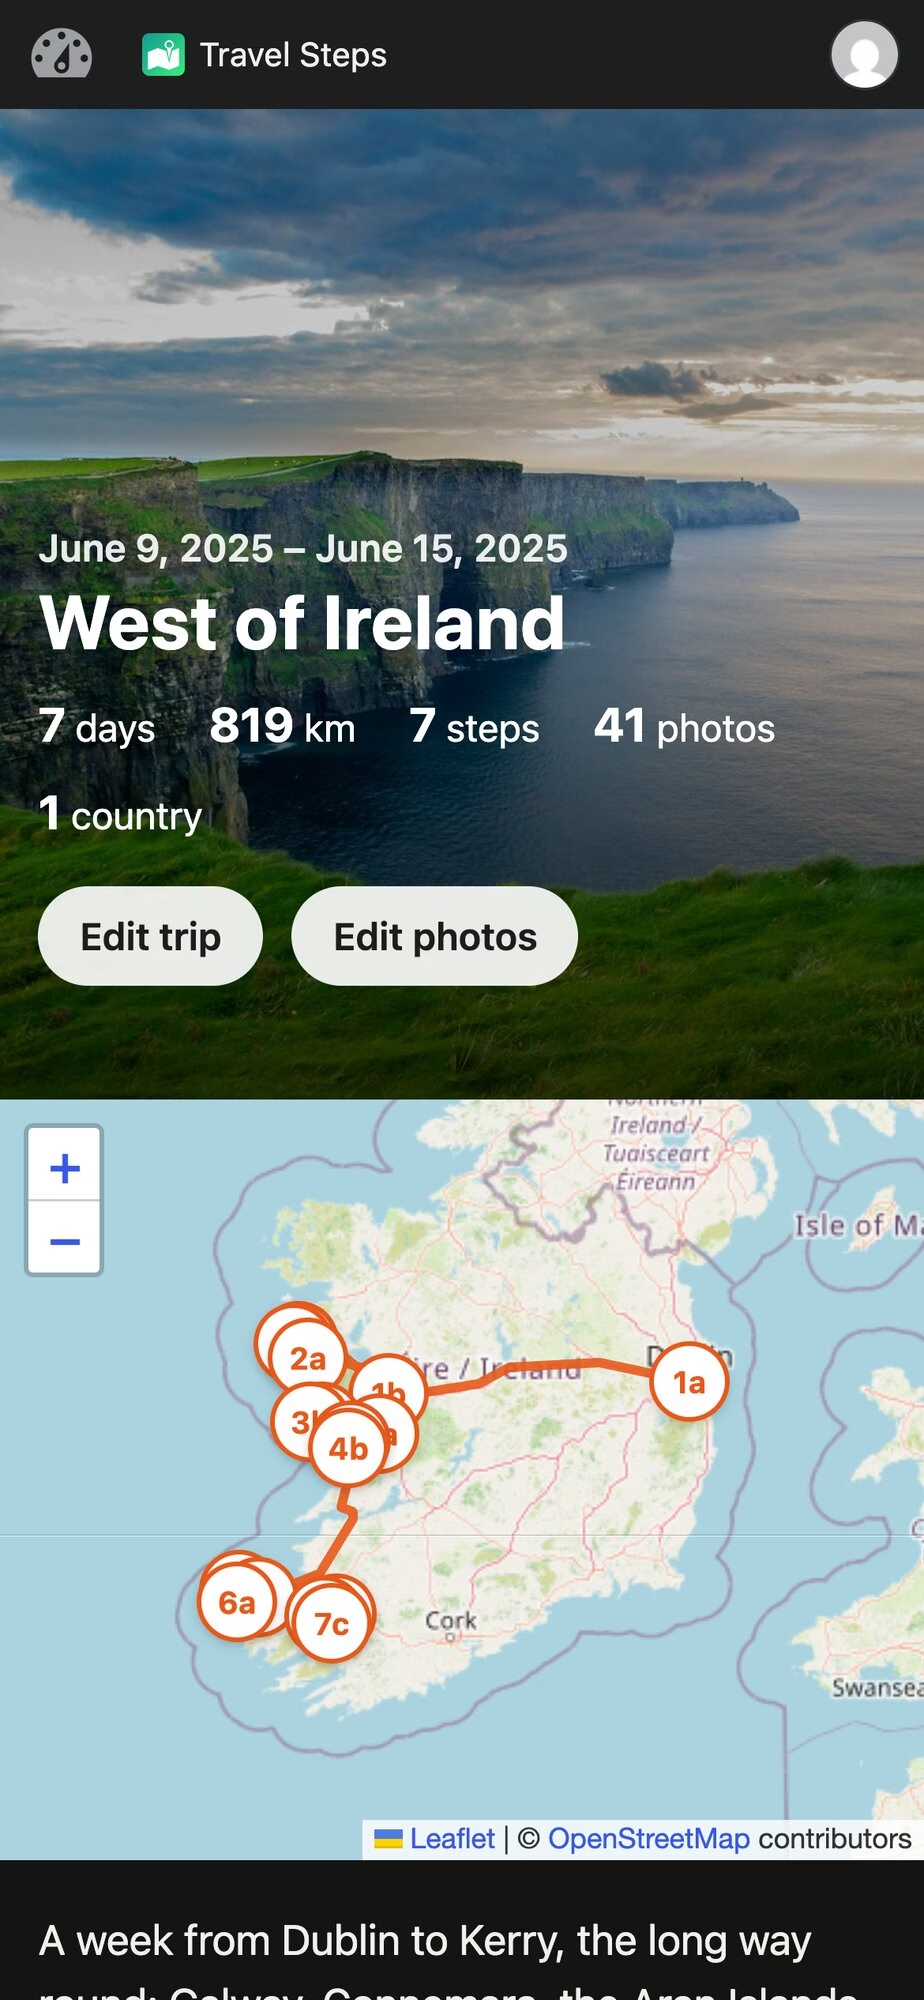
I made a WordPress plugin for my holidays. It’s called Travel Steps, and it turns a trip into a page with a map down one side and the story of each day down the other.
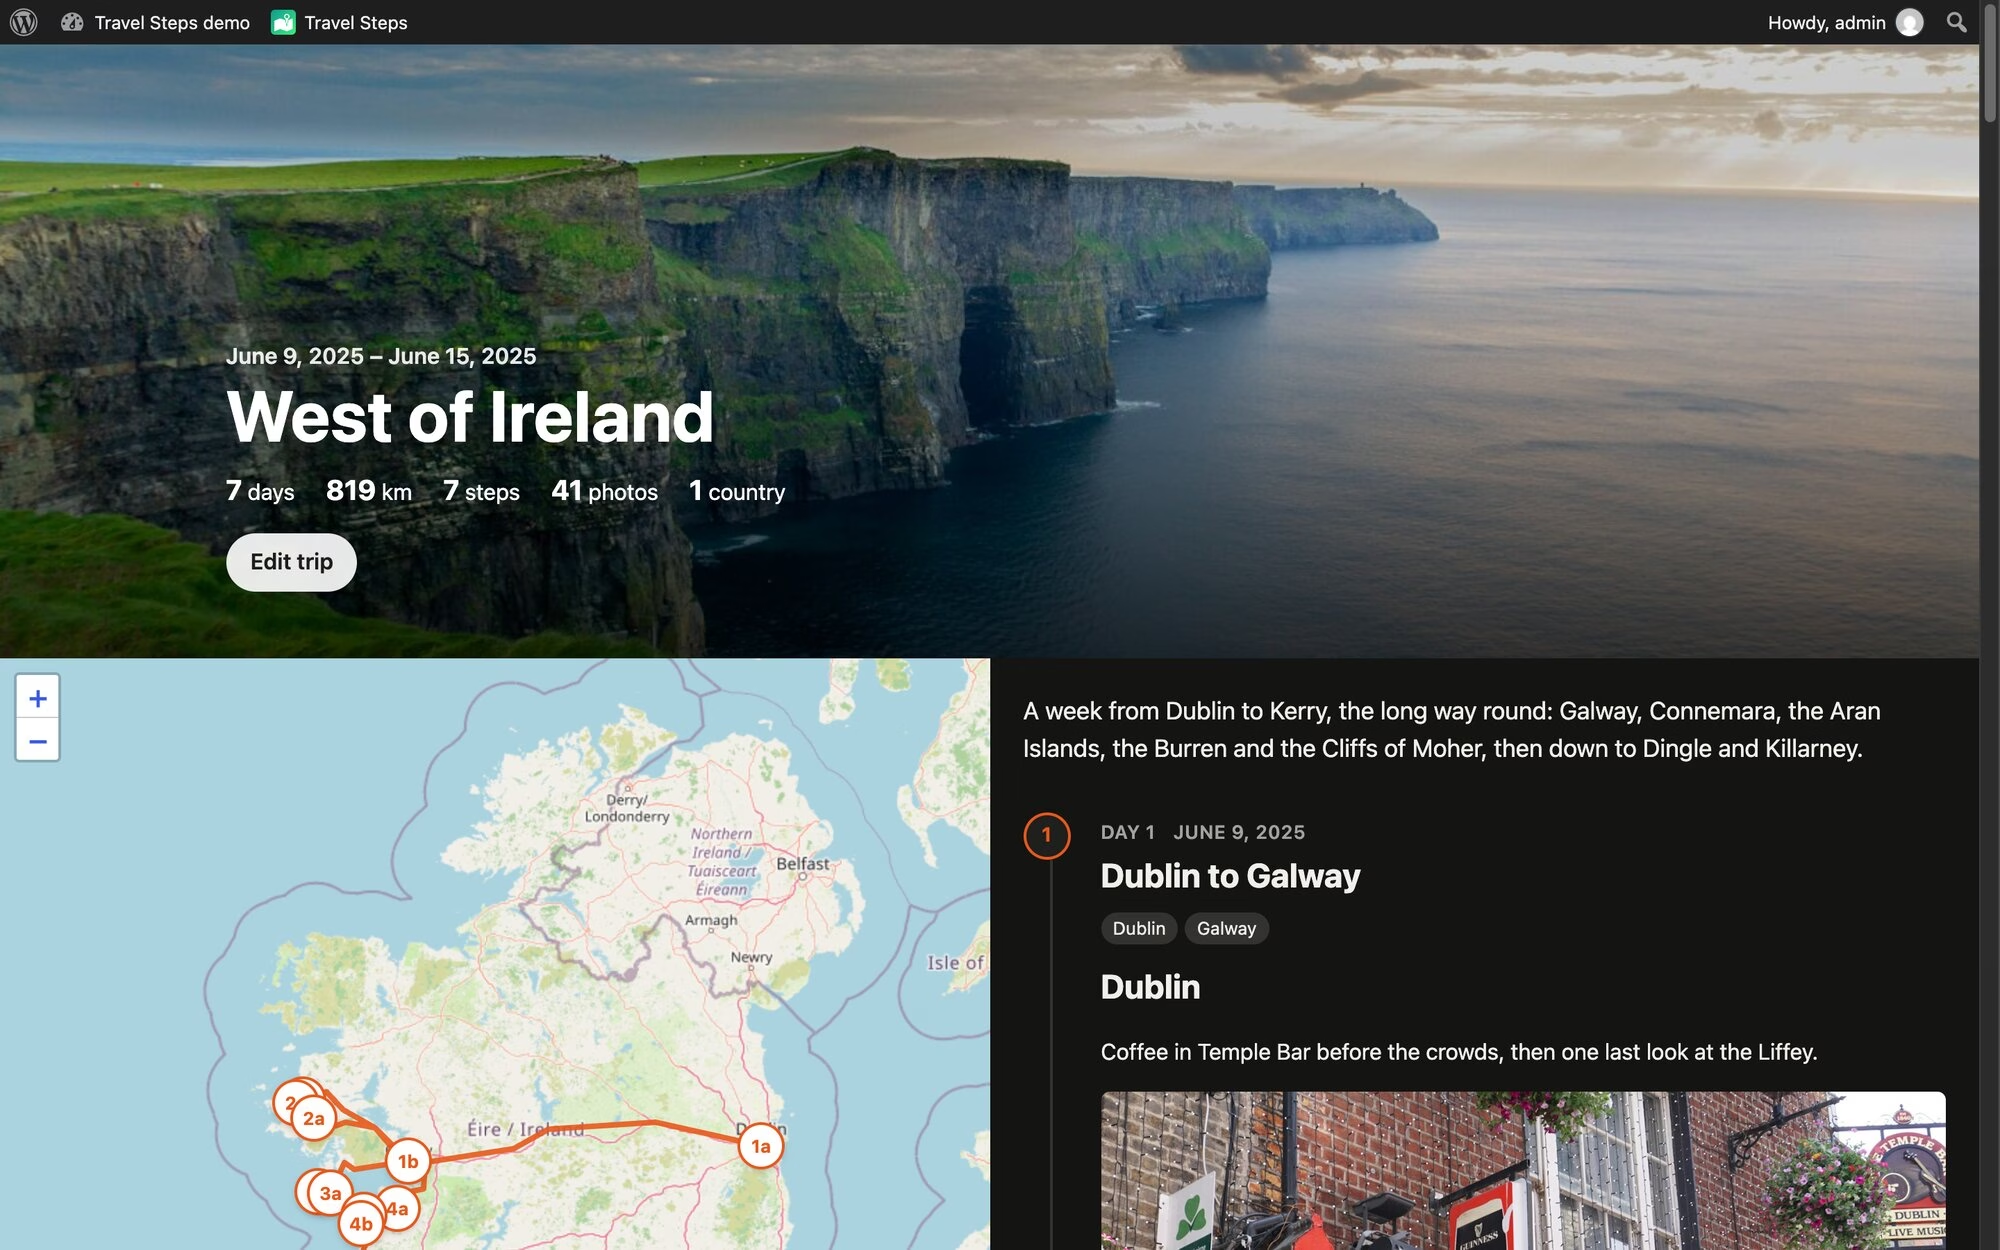
Every photo I take ends up in Immich, on my own server. My phone sends where I’ve been to Dawarich, on the same server. So after a trip I have all the photos and the whole route, sitting in two apps on my private server. The travel apps that make nice trip pages want your photos and your location on their servers. I’d rather keep them on mine.
How it works
You make a trip, give it a first and last day, and press Sync. Travel Steps asks Dawarich for your location over those days, and Immich for the photos you took. You can pick one Immich album instead. If you don’t use Immich at all, upload the photos to the trip. It will detect the start and end dates from the uploaded photos, or an Immich album too.
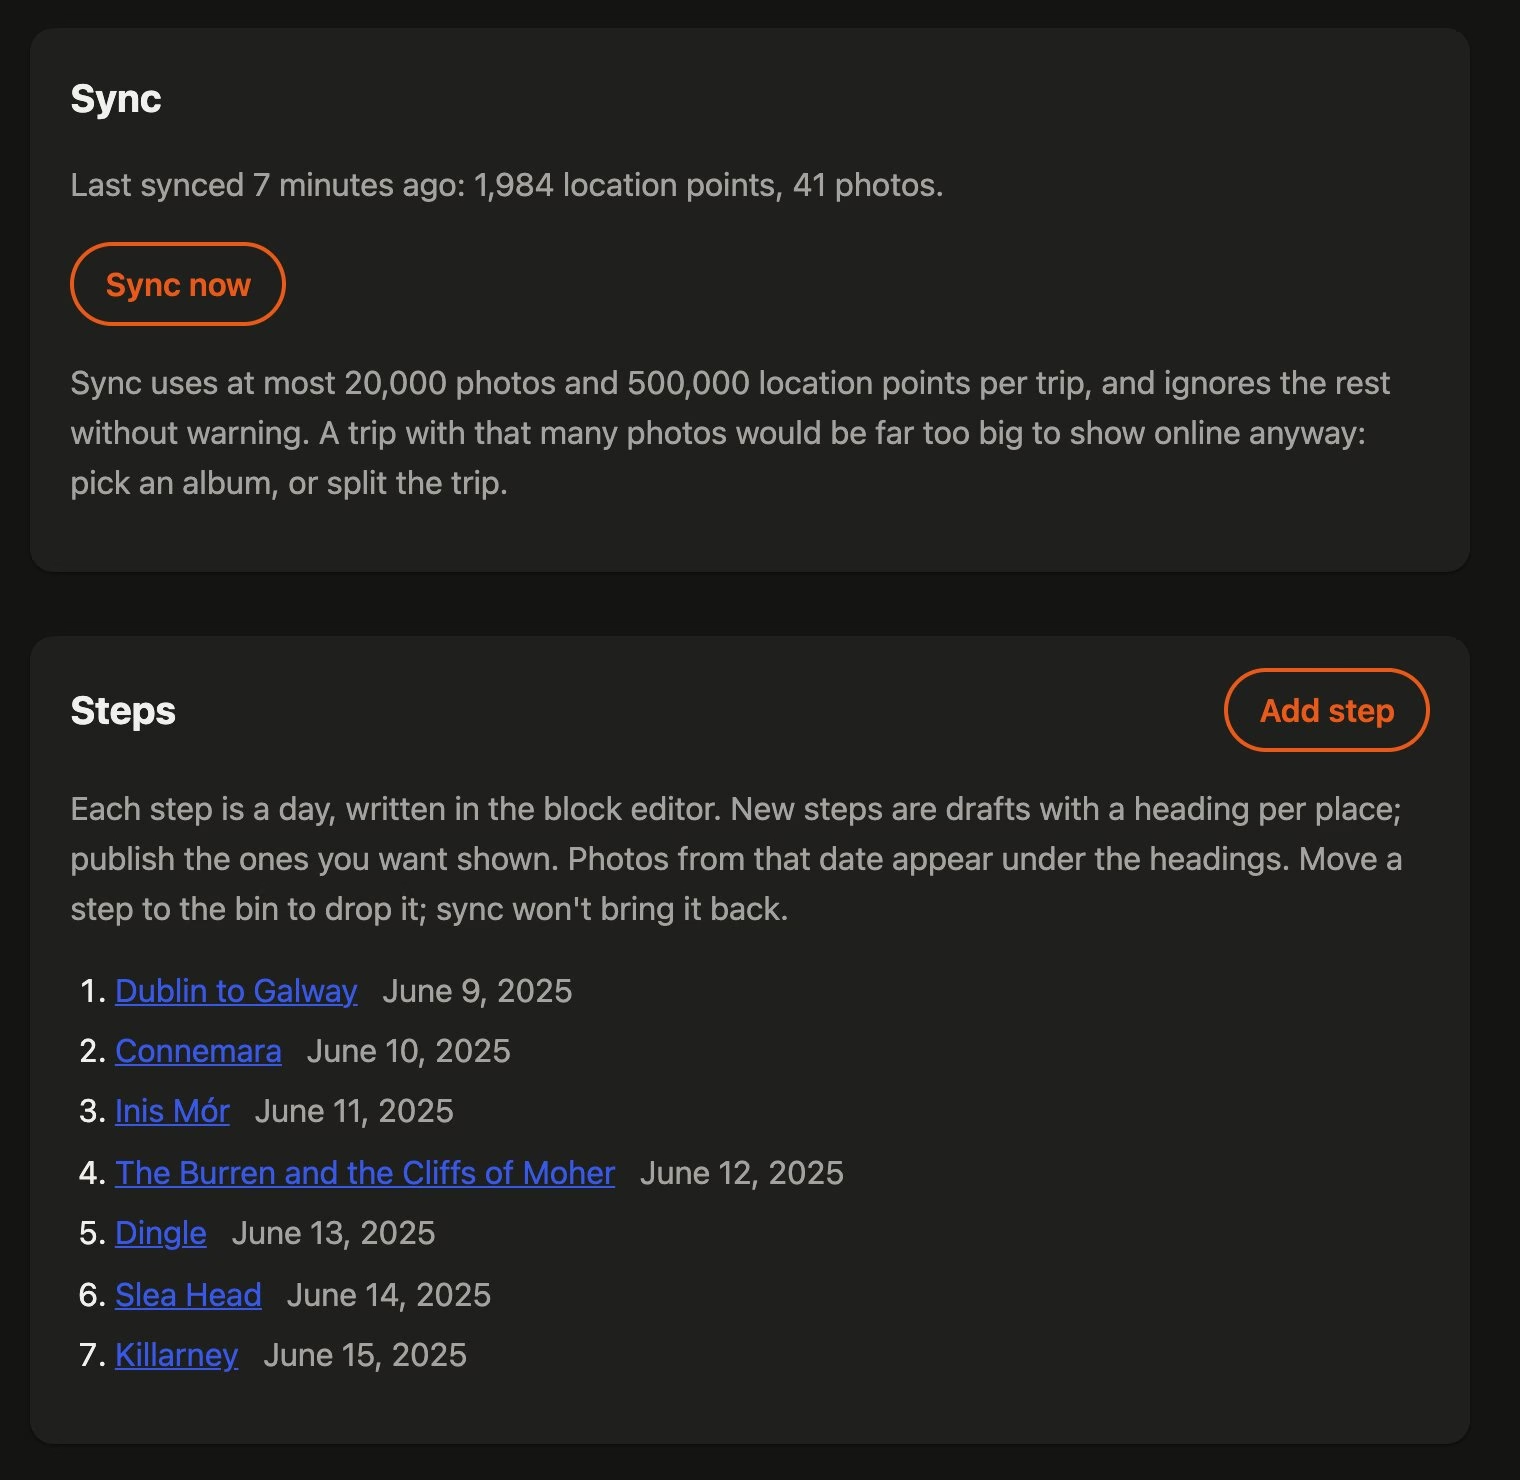
Sync makes a draft post for every day that has favourite photos. Each one is a “step”. It splits the day into places too. A new place starts when a favourite is more than 2 km from the last one and in a different town. Each place gets a heading and a block of photos, so all that’s left is the writing.
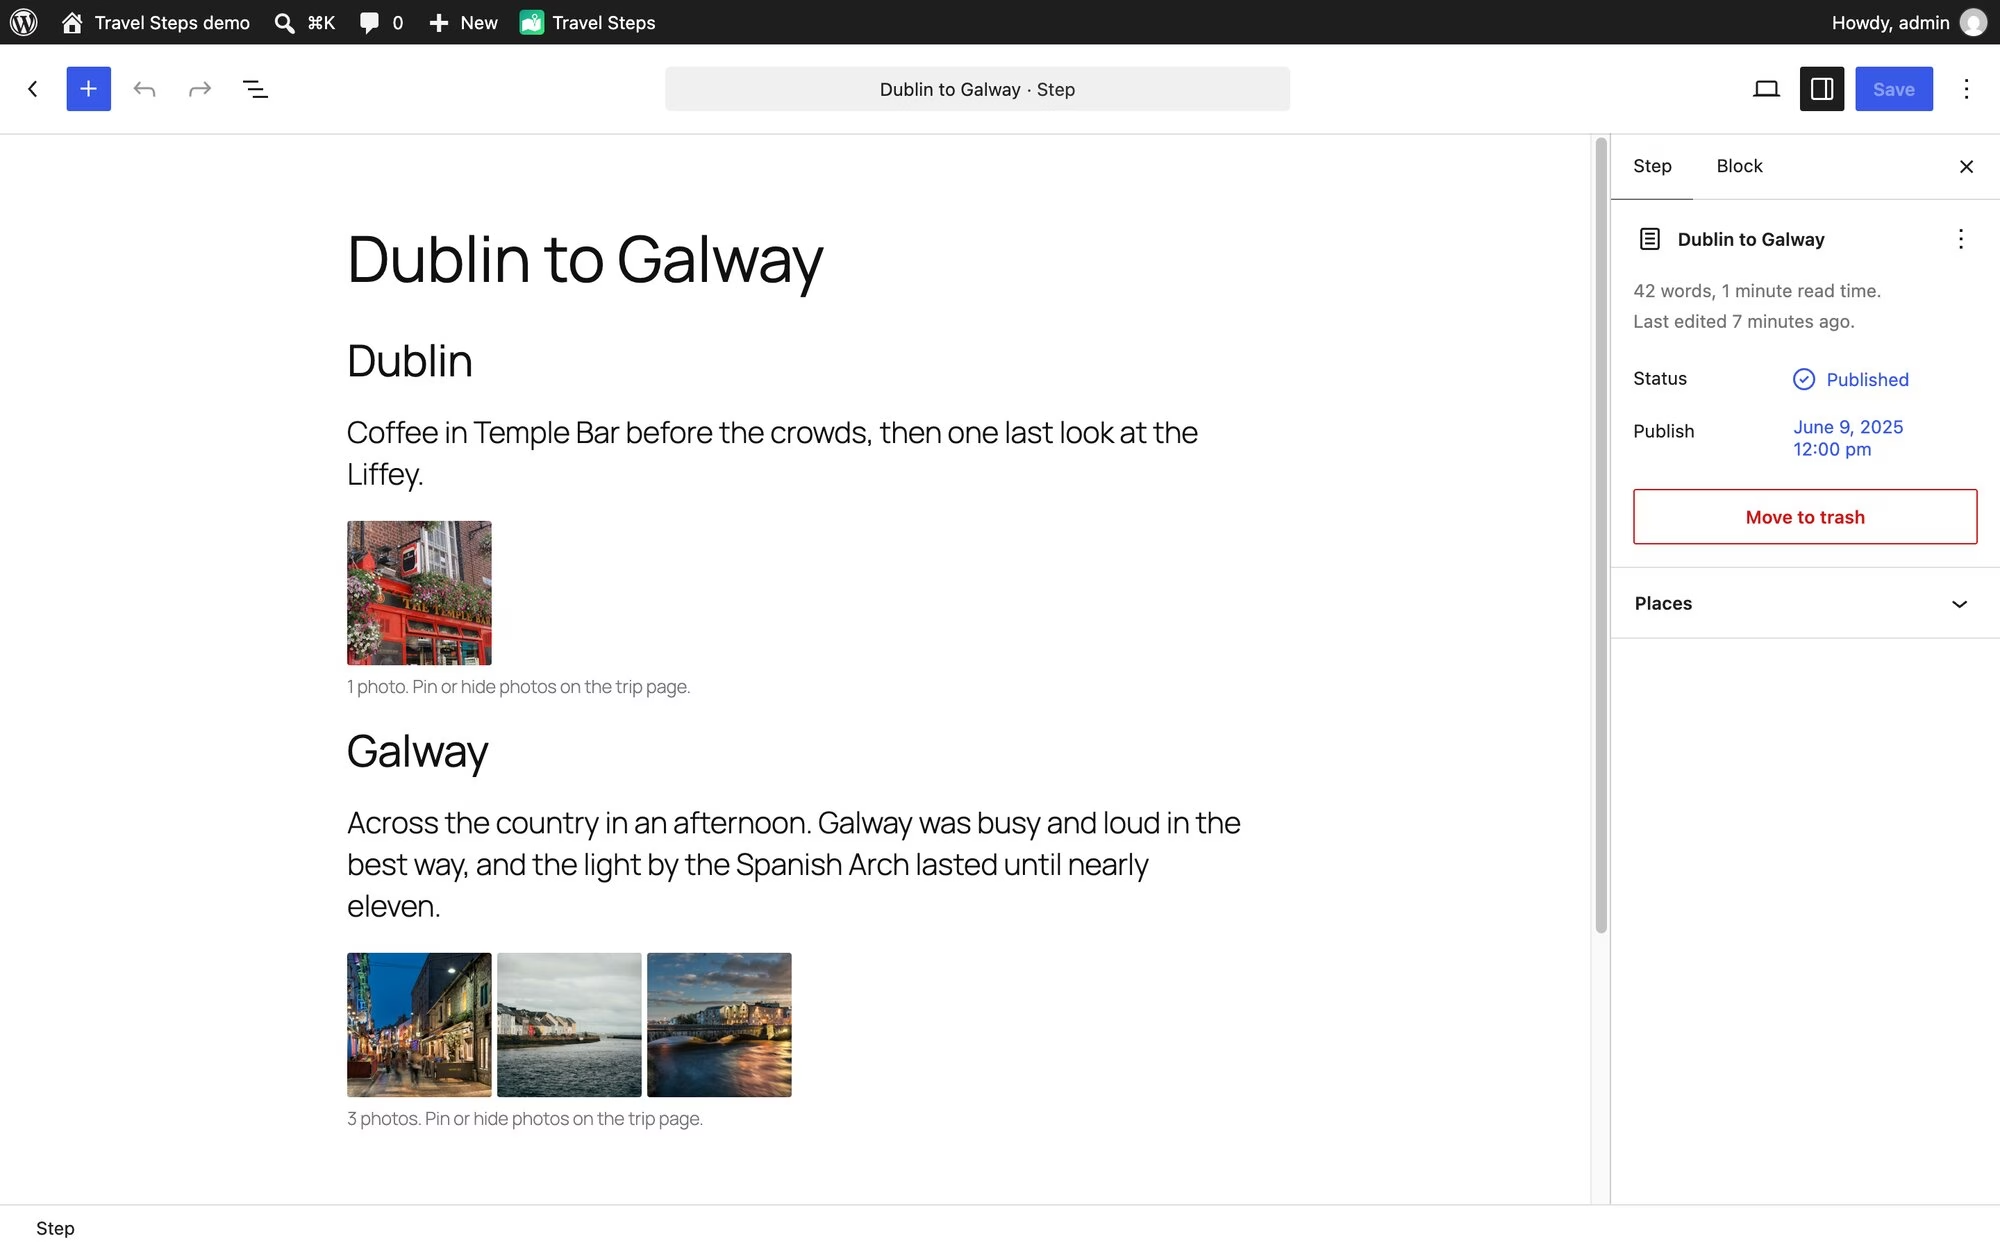
Place names come from GeoNames data that ships with the plugin, so naming a town doesn’t send your location anywhere. Immich only names a place from a photo’s own GPS. A photo from a camera without GPS gets placed from your Dawarich history instead, and named the same way.
Publish the days you want people to see. Drafts stay private, and so do their photos.
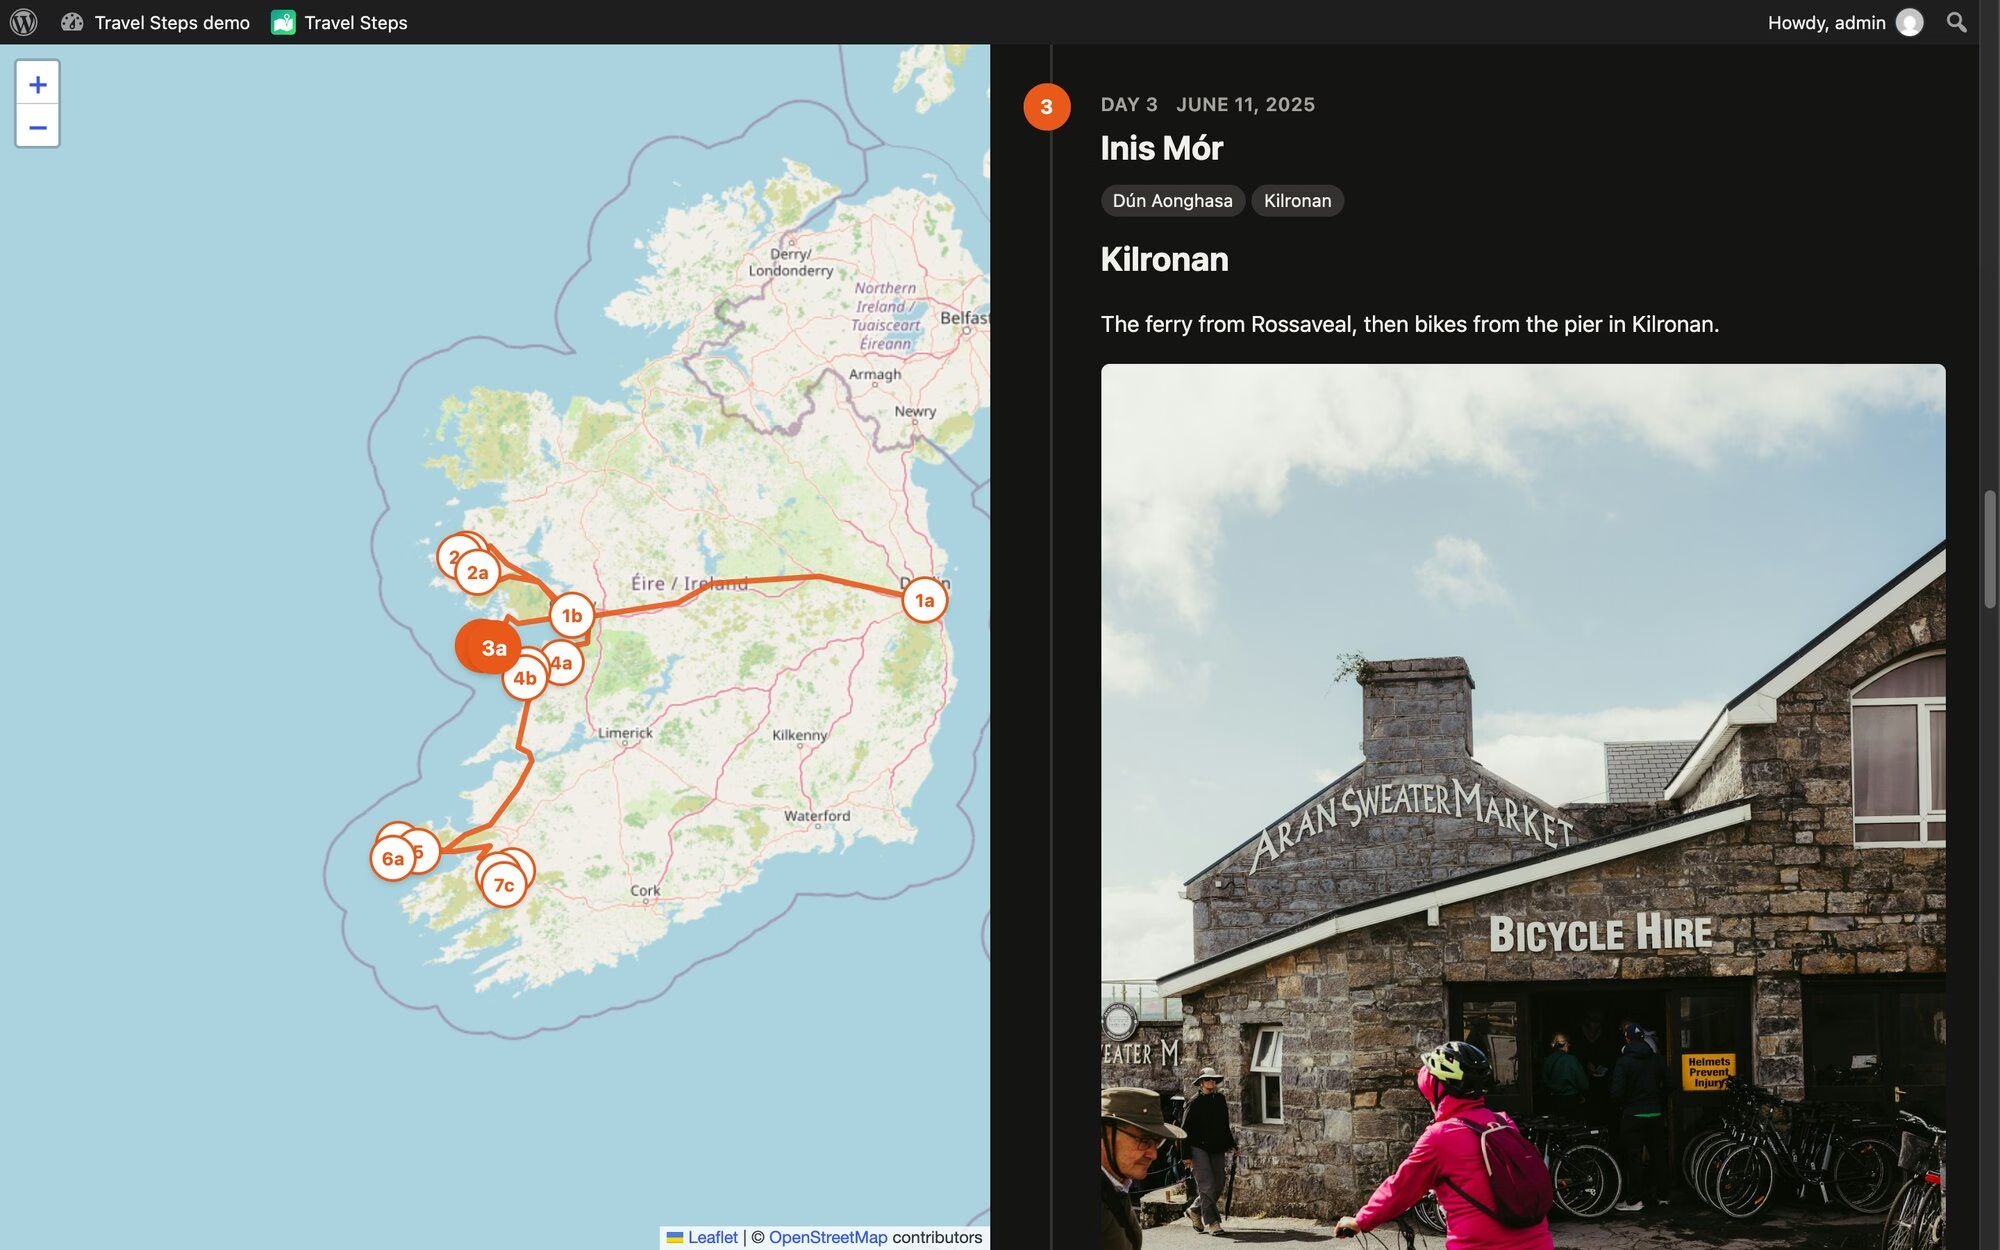
The distance at the top follows the whole route, flights included. GPS glitches that put you in the Atlantic for a second are dropped. Anything you’d have needed to travel faster than 1,080 km/h to reach counts as a glitch. Sorry, Concorde.
Your photos stay at home
Visitors never talk to Immich. WordPress fetches each photo, caches it and serves it itself, so Immich and the original files stay private. It caches a trip’s photos in the background after a sync. The trip keeps working when Immich is down. A daily sweep deletes cached photos older than a number of days you choose, whether a trip still uses them or not, and they’re fetched again the next time someone looks.
Photos you upload to a trip keep their GPS in the original, but it’s stripped from every copy WordPress makes, and only those copies are ever sent. A trip can have a password, and you can let some logged-in people skip it.
Pin, hide, cover
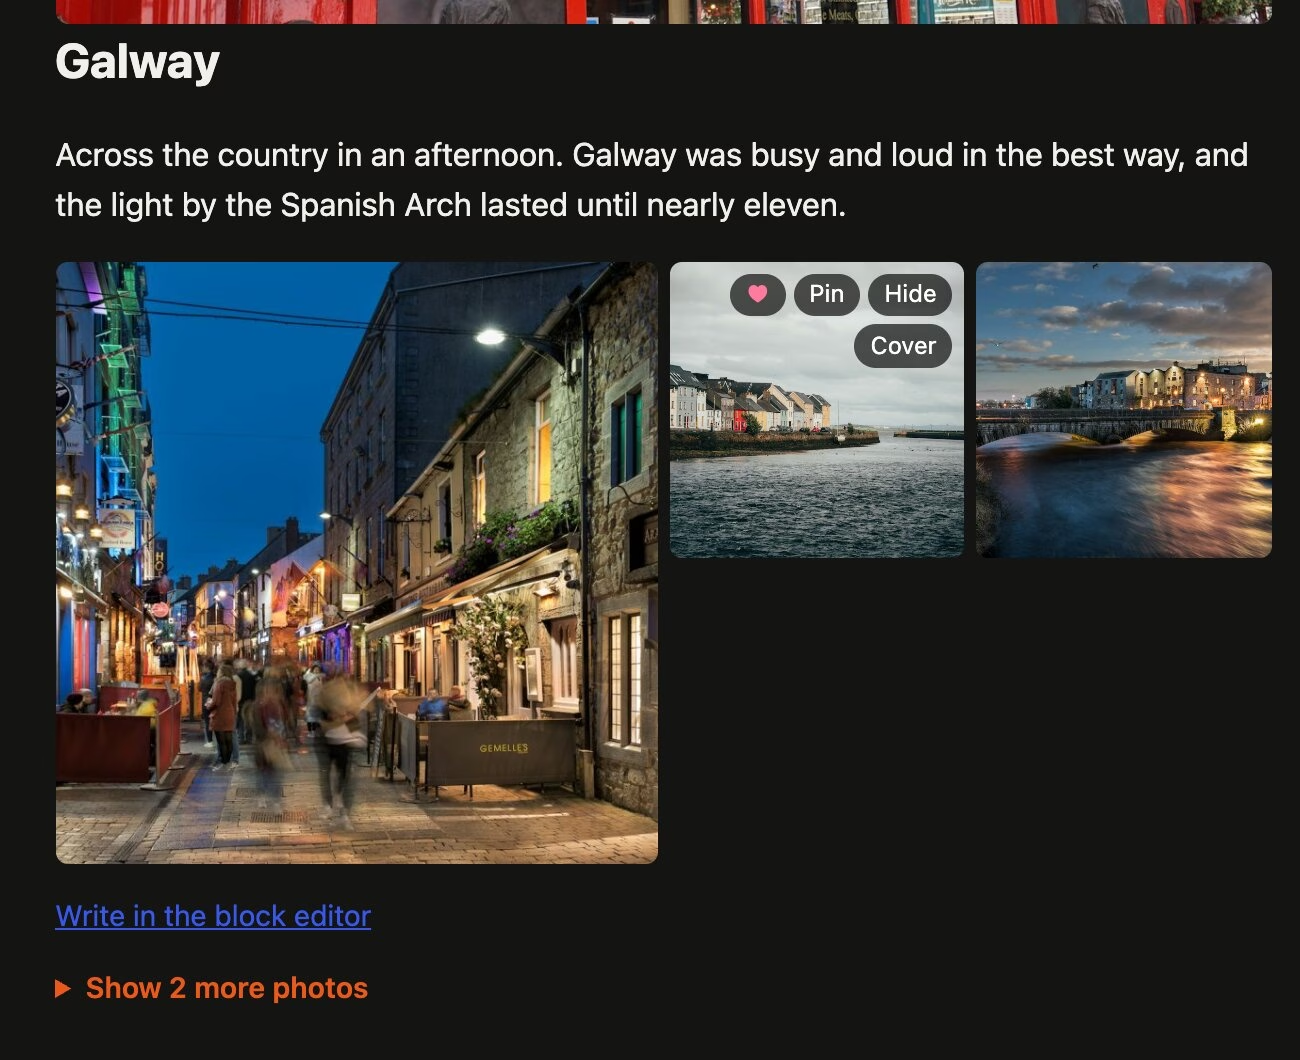
Hover over a photo to pin it (always show it), hide it, or make it the trip’s cover. The rest of the day’s photos sit behind a “Show more photos” link.
On phones, those buttons show up after you press Edit photos as illustrated by the images below.
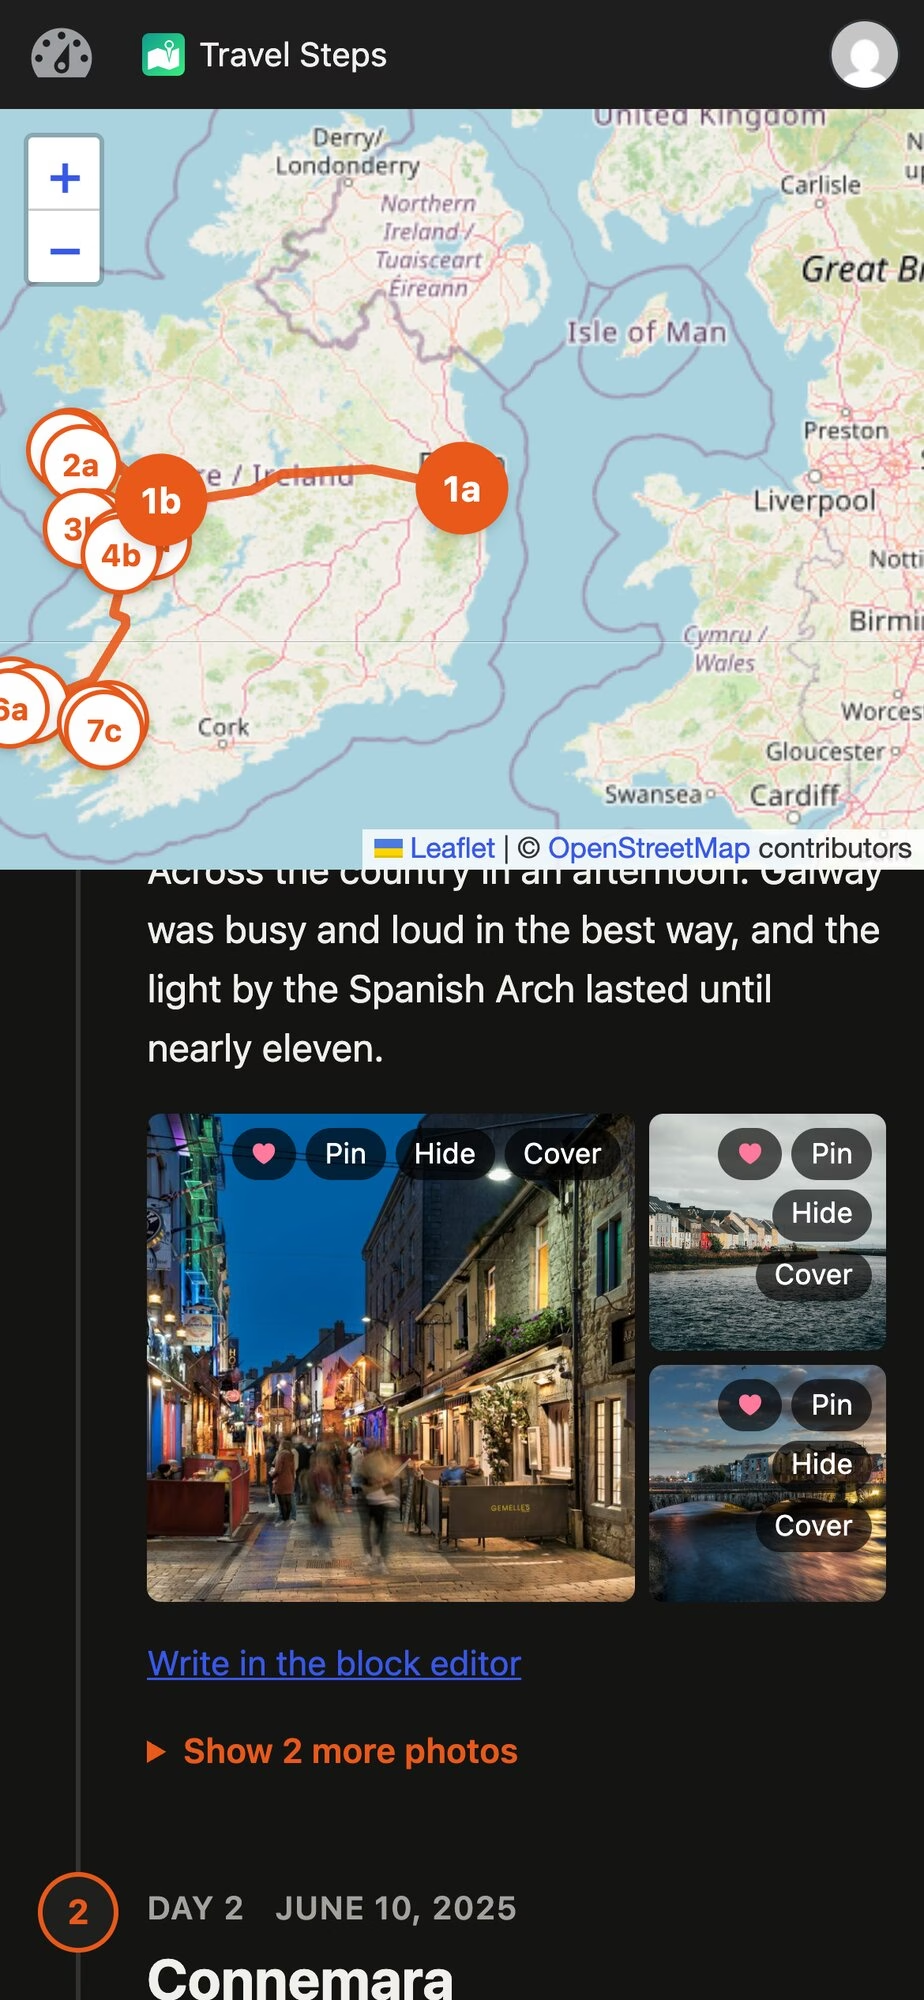
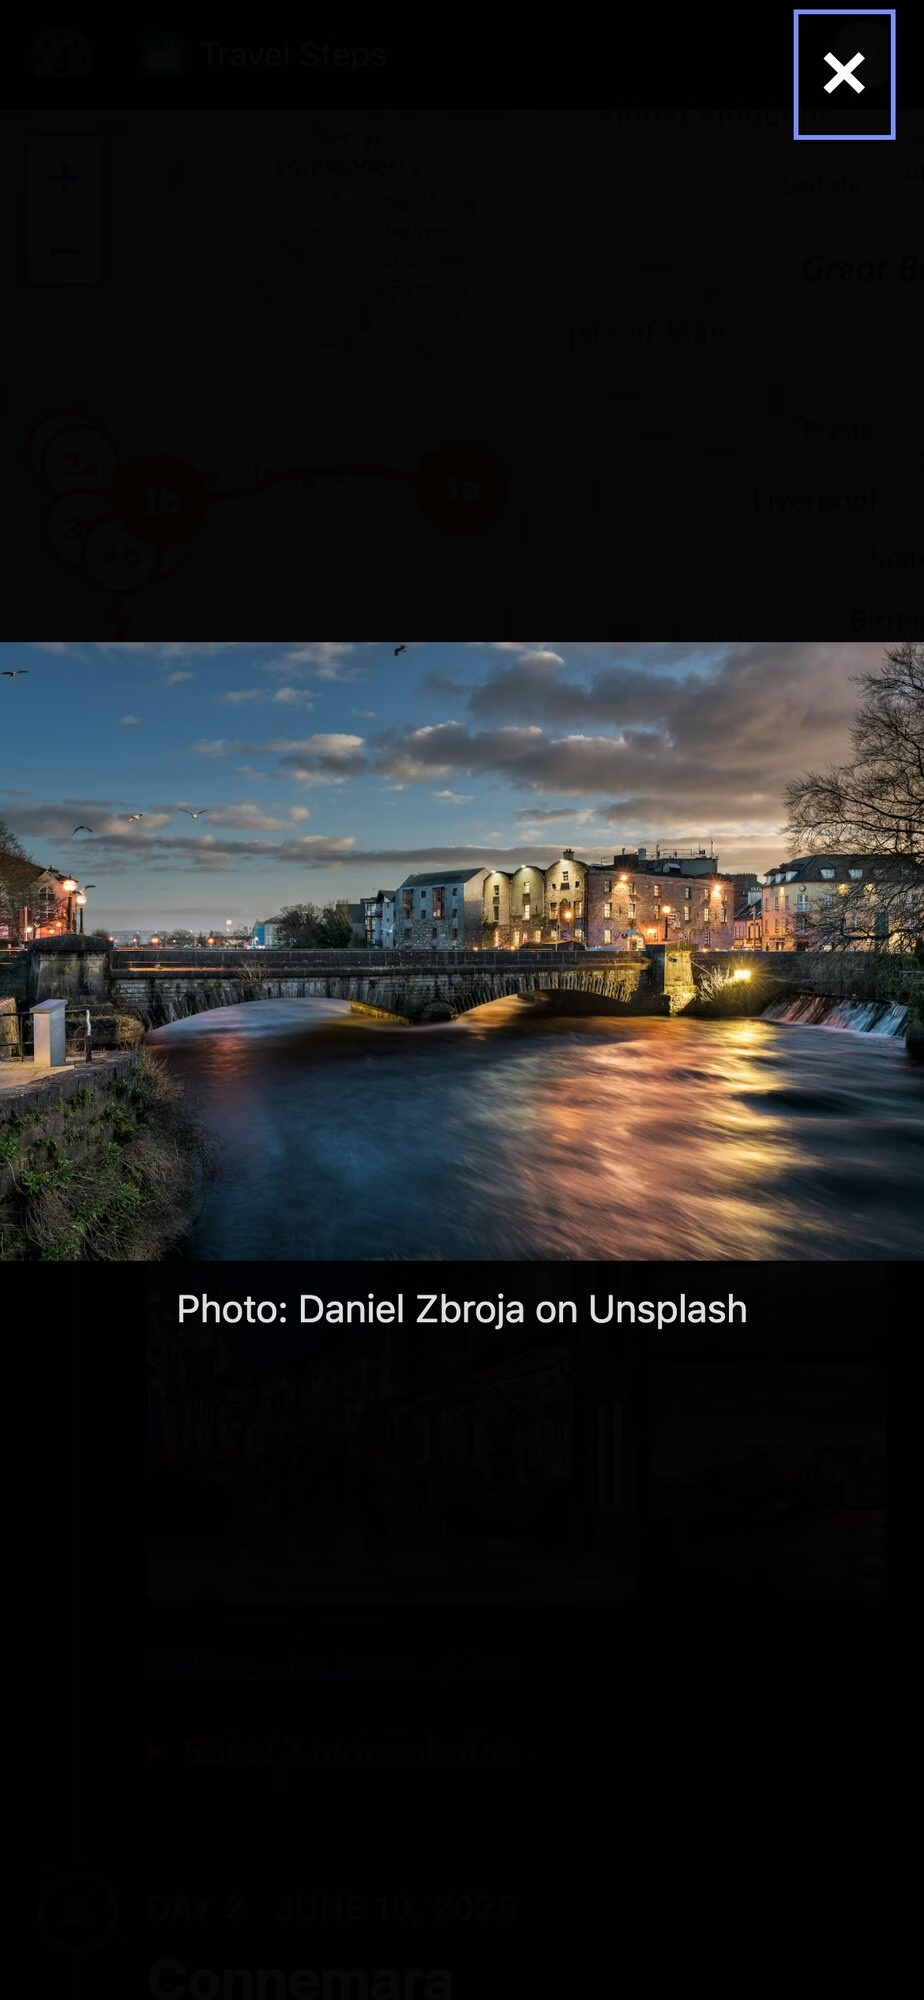
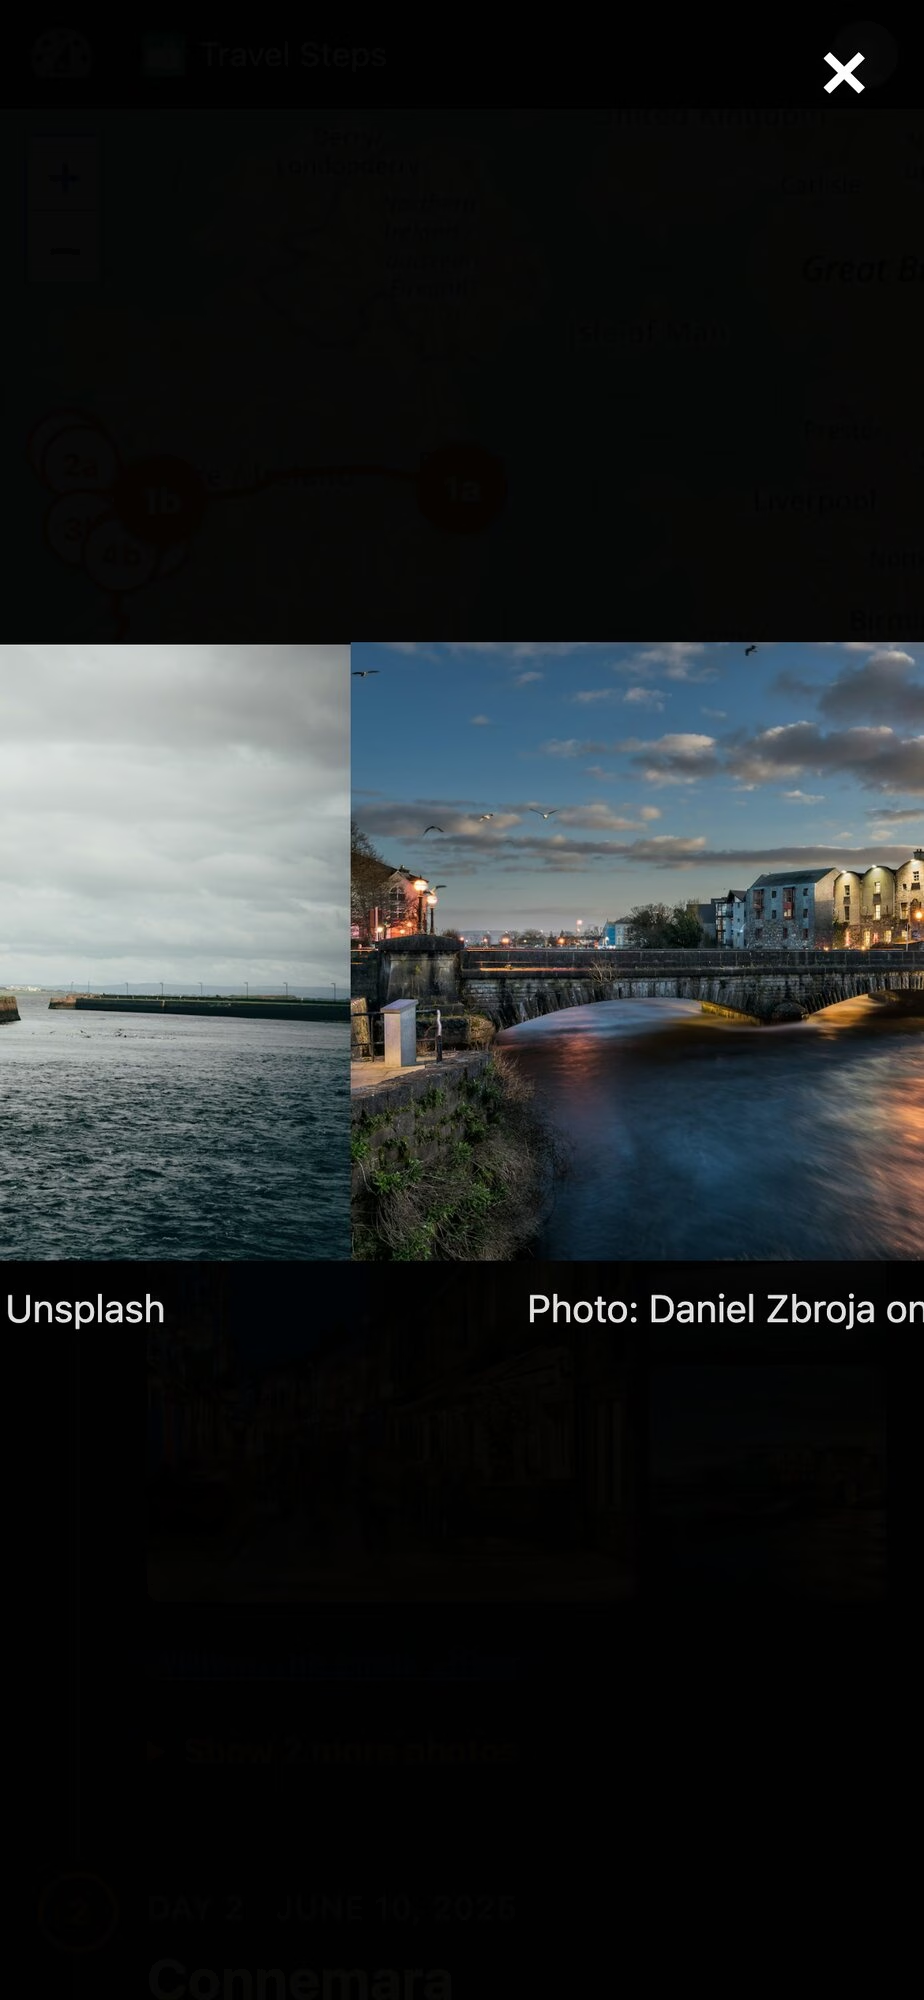
Tap a photo and it opens full screen. On a phone you swipe from one photo to the next, edge to edge. On a desktop there are arrows, and the arrow keys work too.
Try it
Here’s a demo in WordPress Playground. It’s a week in the west of Ireland, running in your browser that installs nothing. Stand-in Immich and Dawarich servers feed the real sync code with photos from Unsplash. You’re logged in as an admin, so press Sync, pin and hide photos, and edit the days in the block editor. It all disappears when you close the tab.
The code is on GitHub. To install it, download travel-steps.zip from the latest release and upload it under Plugins → Add New. It needs WordPress 6.7 and PHP 8.0. Immich and Dawarich are both optional. It has been submitted to WordPress.org but if you read this blog, you’ll know how to install a plugin from a zip file!
WpApp
Travel Steps is built on WpApp, Alex Kirk’s framework for building apps on top of WordPress.
A plugin usually adds screens to wp-admin, or puts its pages inside your theme and hopes the CSS gets along. A WpApp app gets its own URLs instead (/travel-steps/ here), and its pages are plain HTML with no theme in the way. WordPress still does the boring work: users and logins, roles, the block editor, the REST API, cron and the database. WpApp adds the bits in between:
- URL routing, using WordPress rewrite rules,
- pages that don’t load your theme,
- the admin bar on every page, with the app’s own icon (the green map at the top of my screenshots),
- access control using WordPress capabilities.
You can start one with composer create-project akirk/create-wp-app my-app. Alex has a showcase of apps built with it, including a cookbook and a family wiki.
Built with Claude Code
I wrote Travel Steps with Claude Code. The first commit was on 11 October, and there are many more now. Most of the work went round the same loop. I file an issue, Claude fixes it test-first on a branch and opens a pull request, and other agents review it. I deploy it to my own server and try it. The tests run in WordPress Playground too, the same as the demo.
If you run Immich, give it a whirl. Bug reports welcome on GitHub 
Demo photos from Unsplash: Cliffs of Moher by Jarek Skowron, Temple Bar by Sarah, Galway by Daniel Zbroja and Anna Hunko, Kilronan by Jonathan Borba. Map © OpenStreetMap contributors.
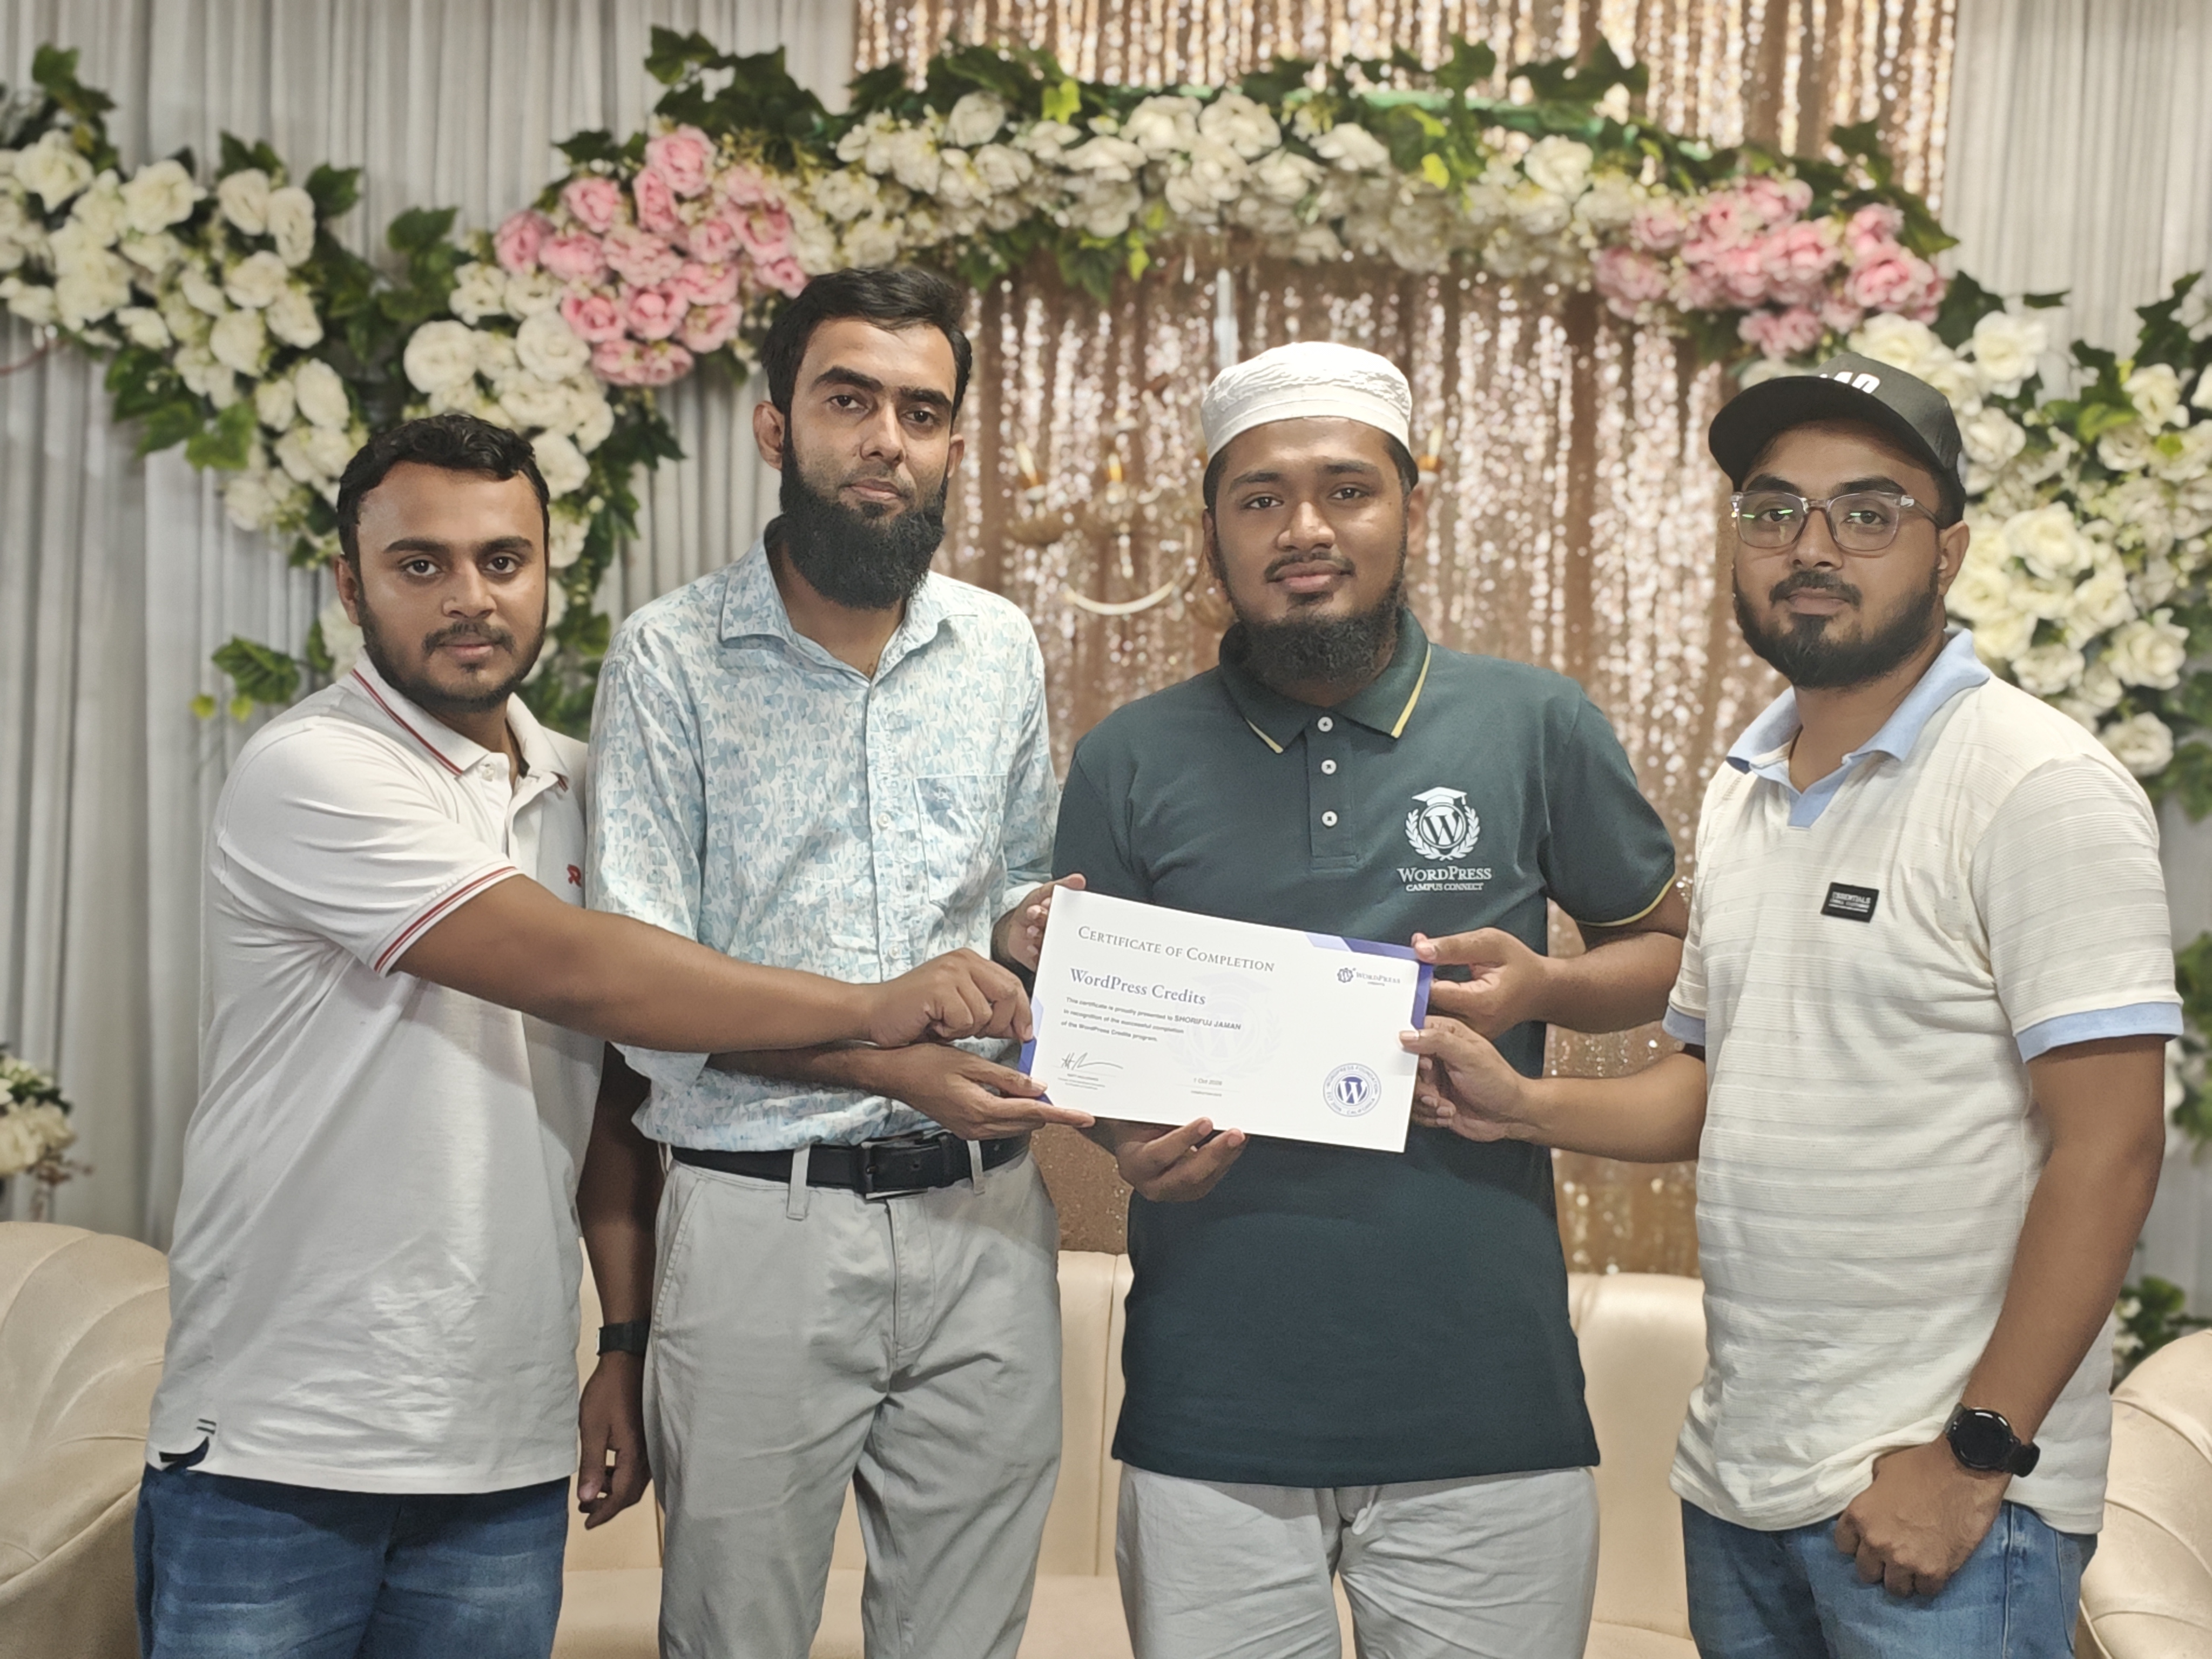
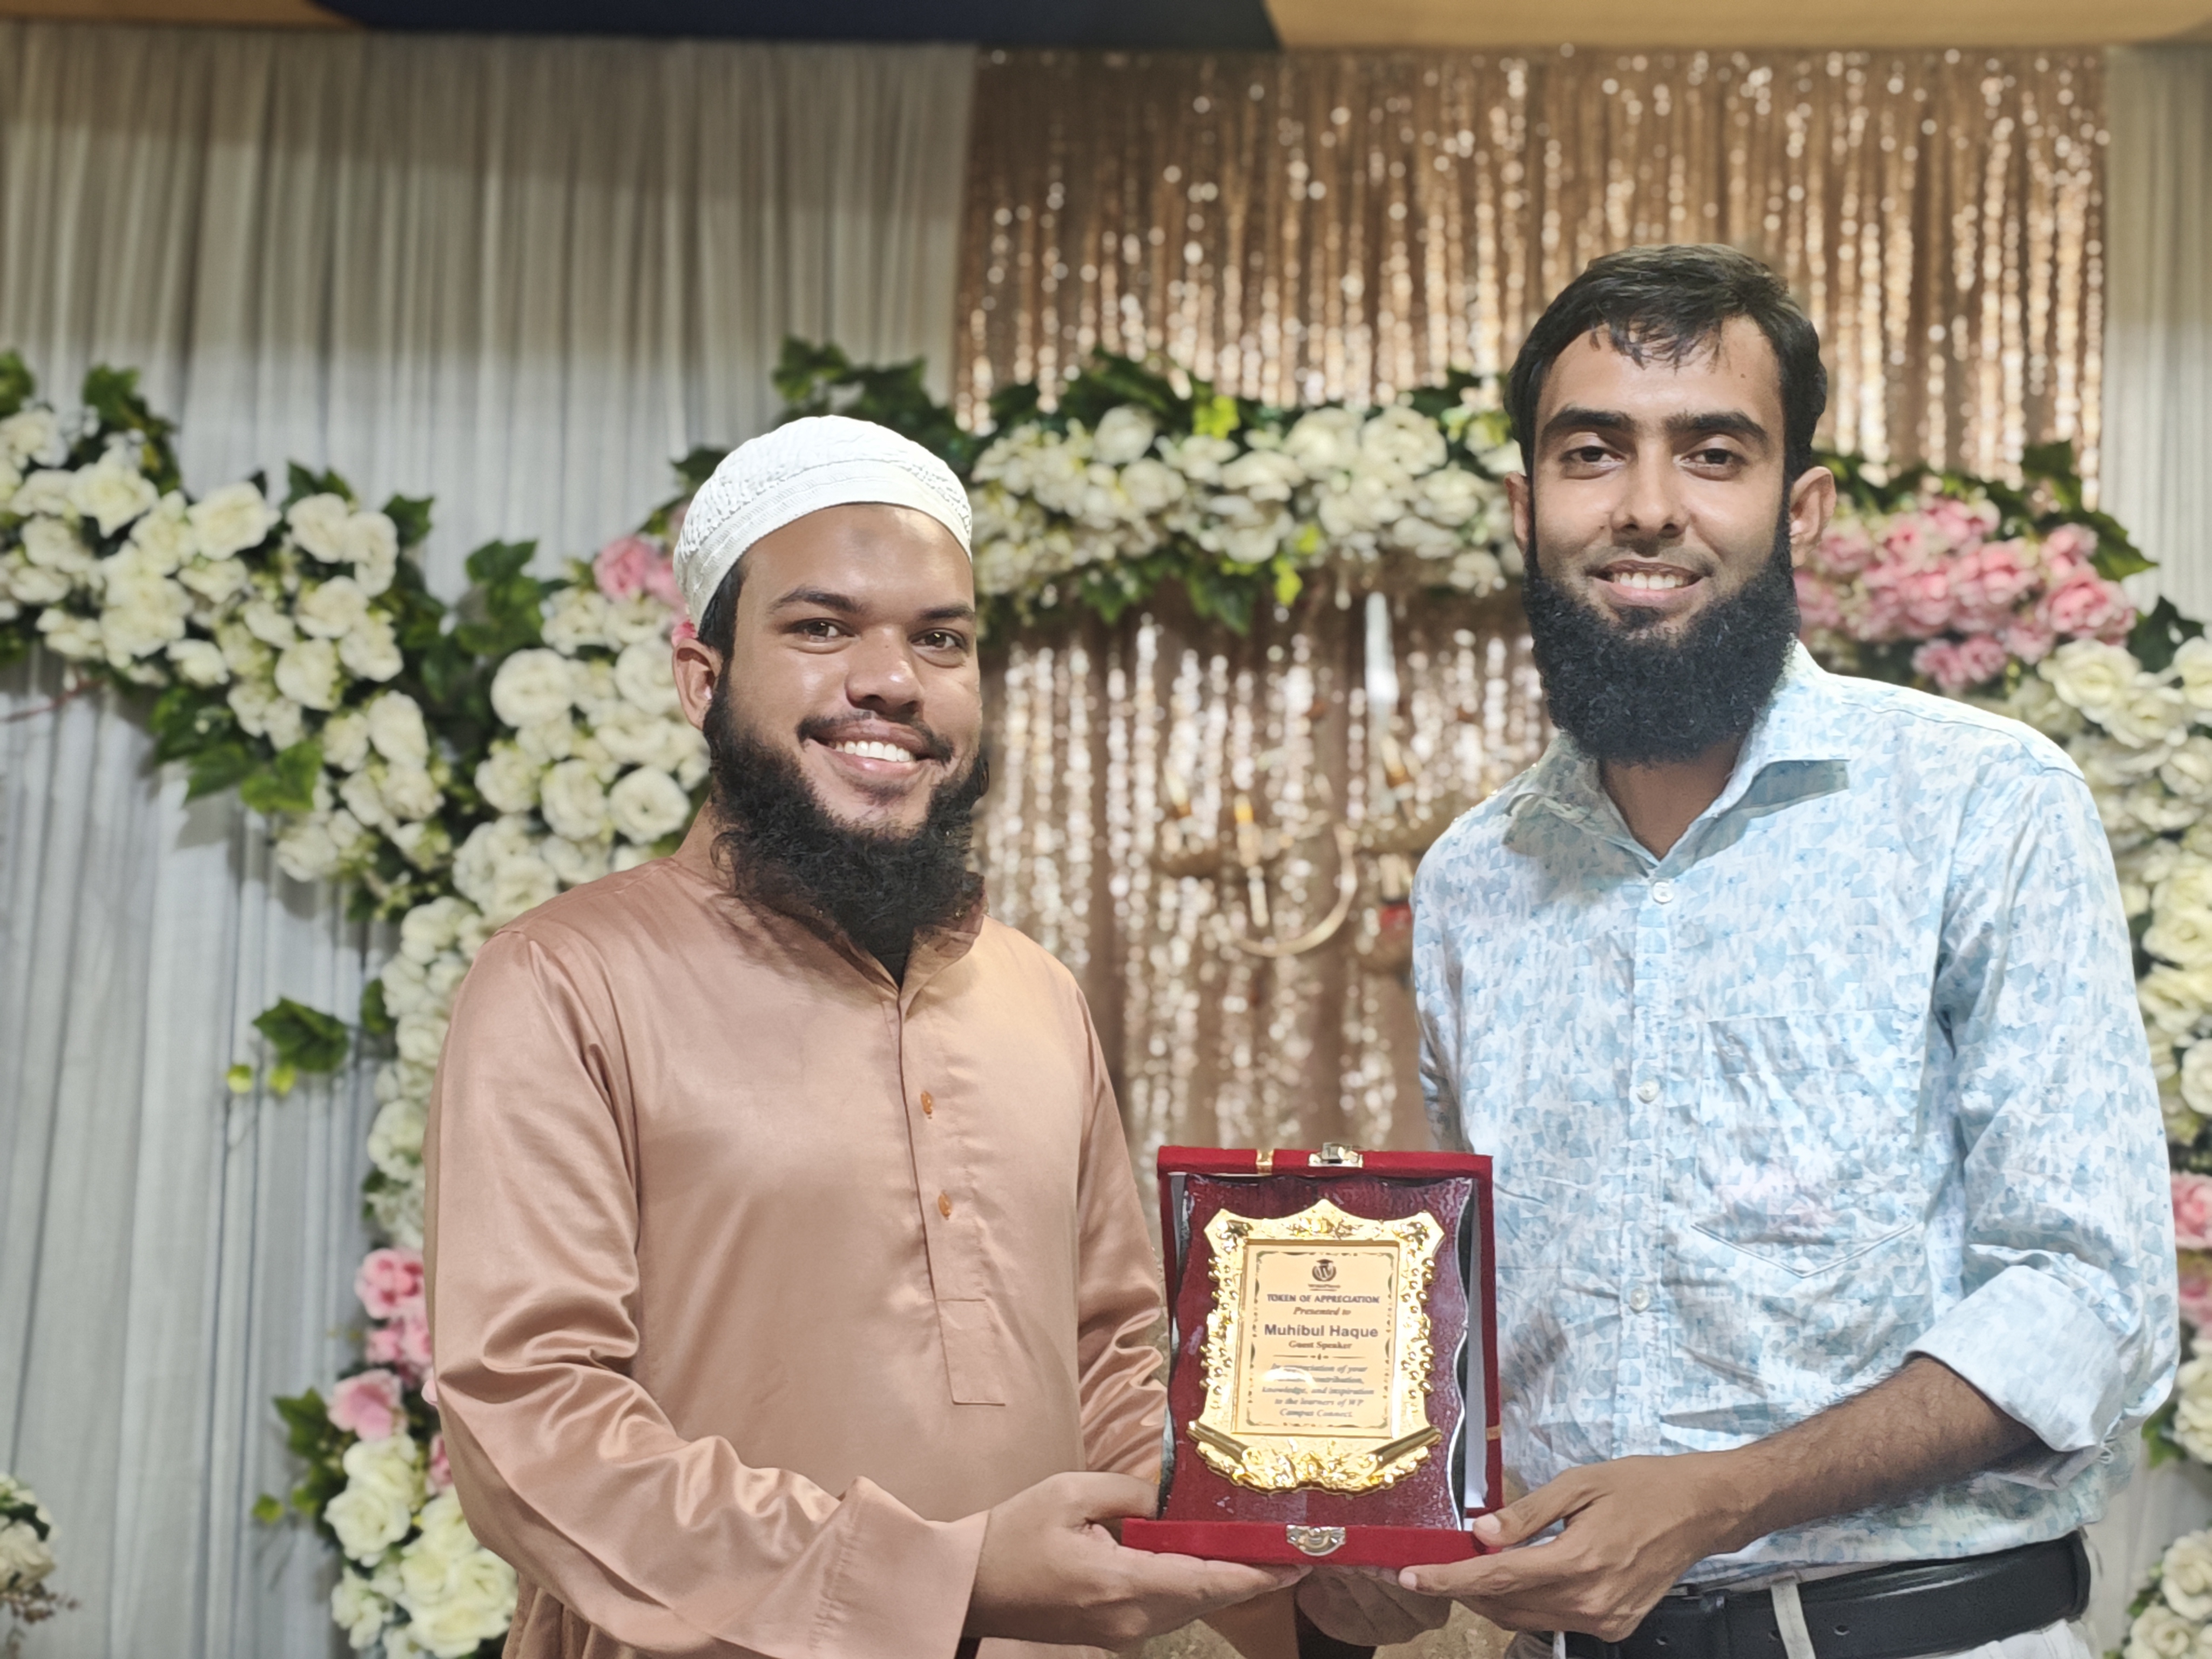
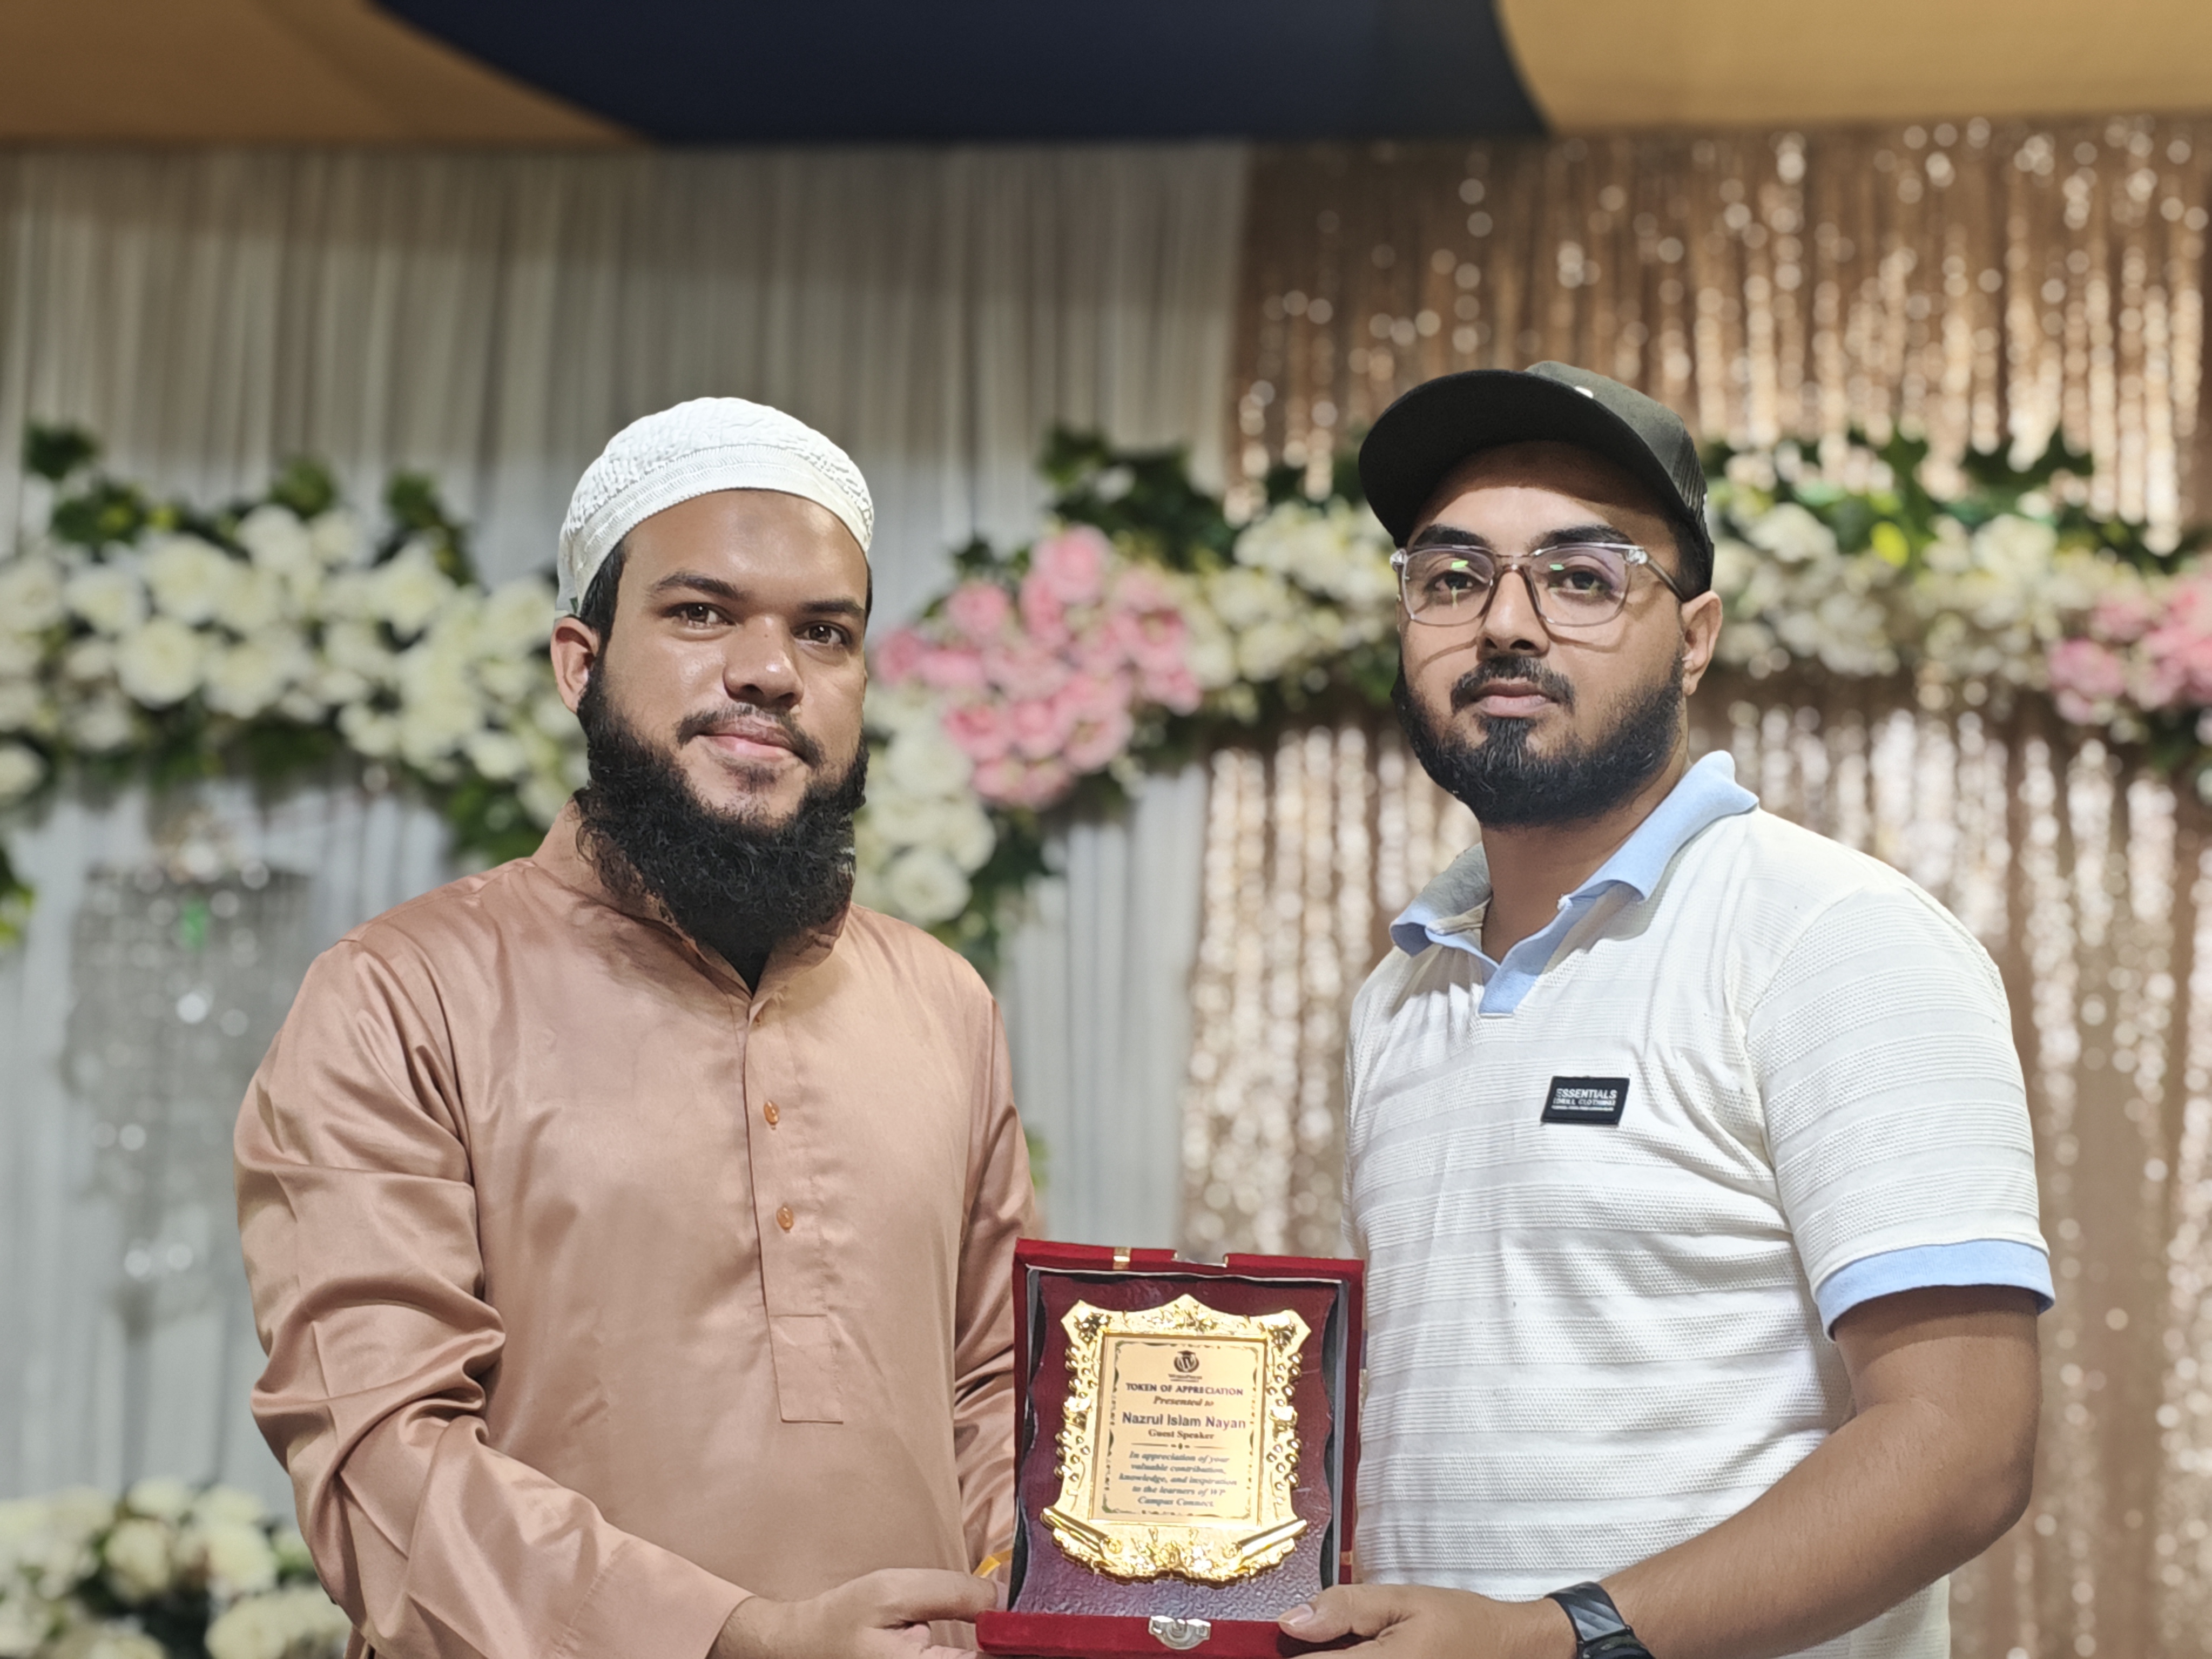
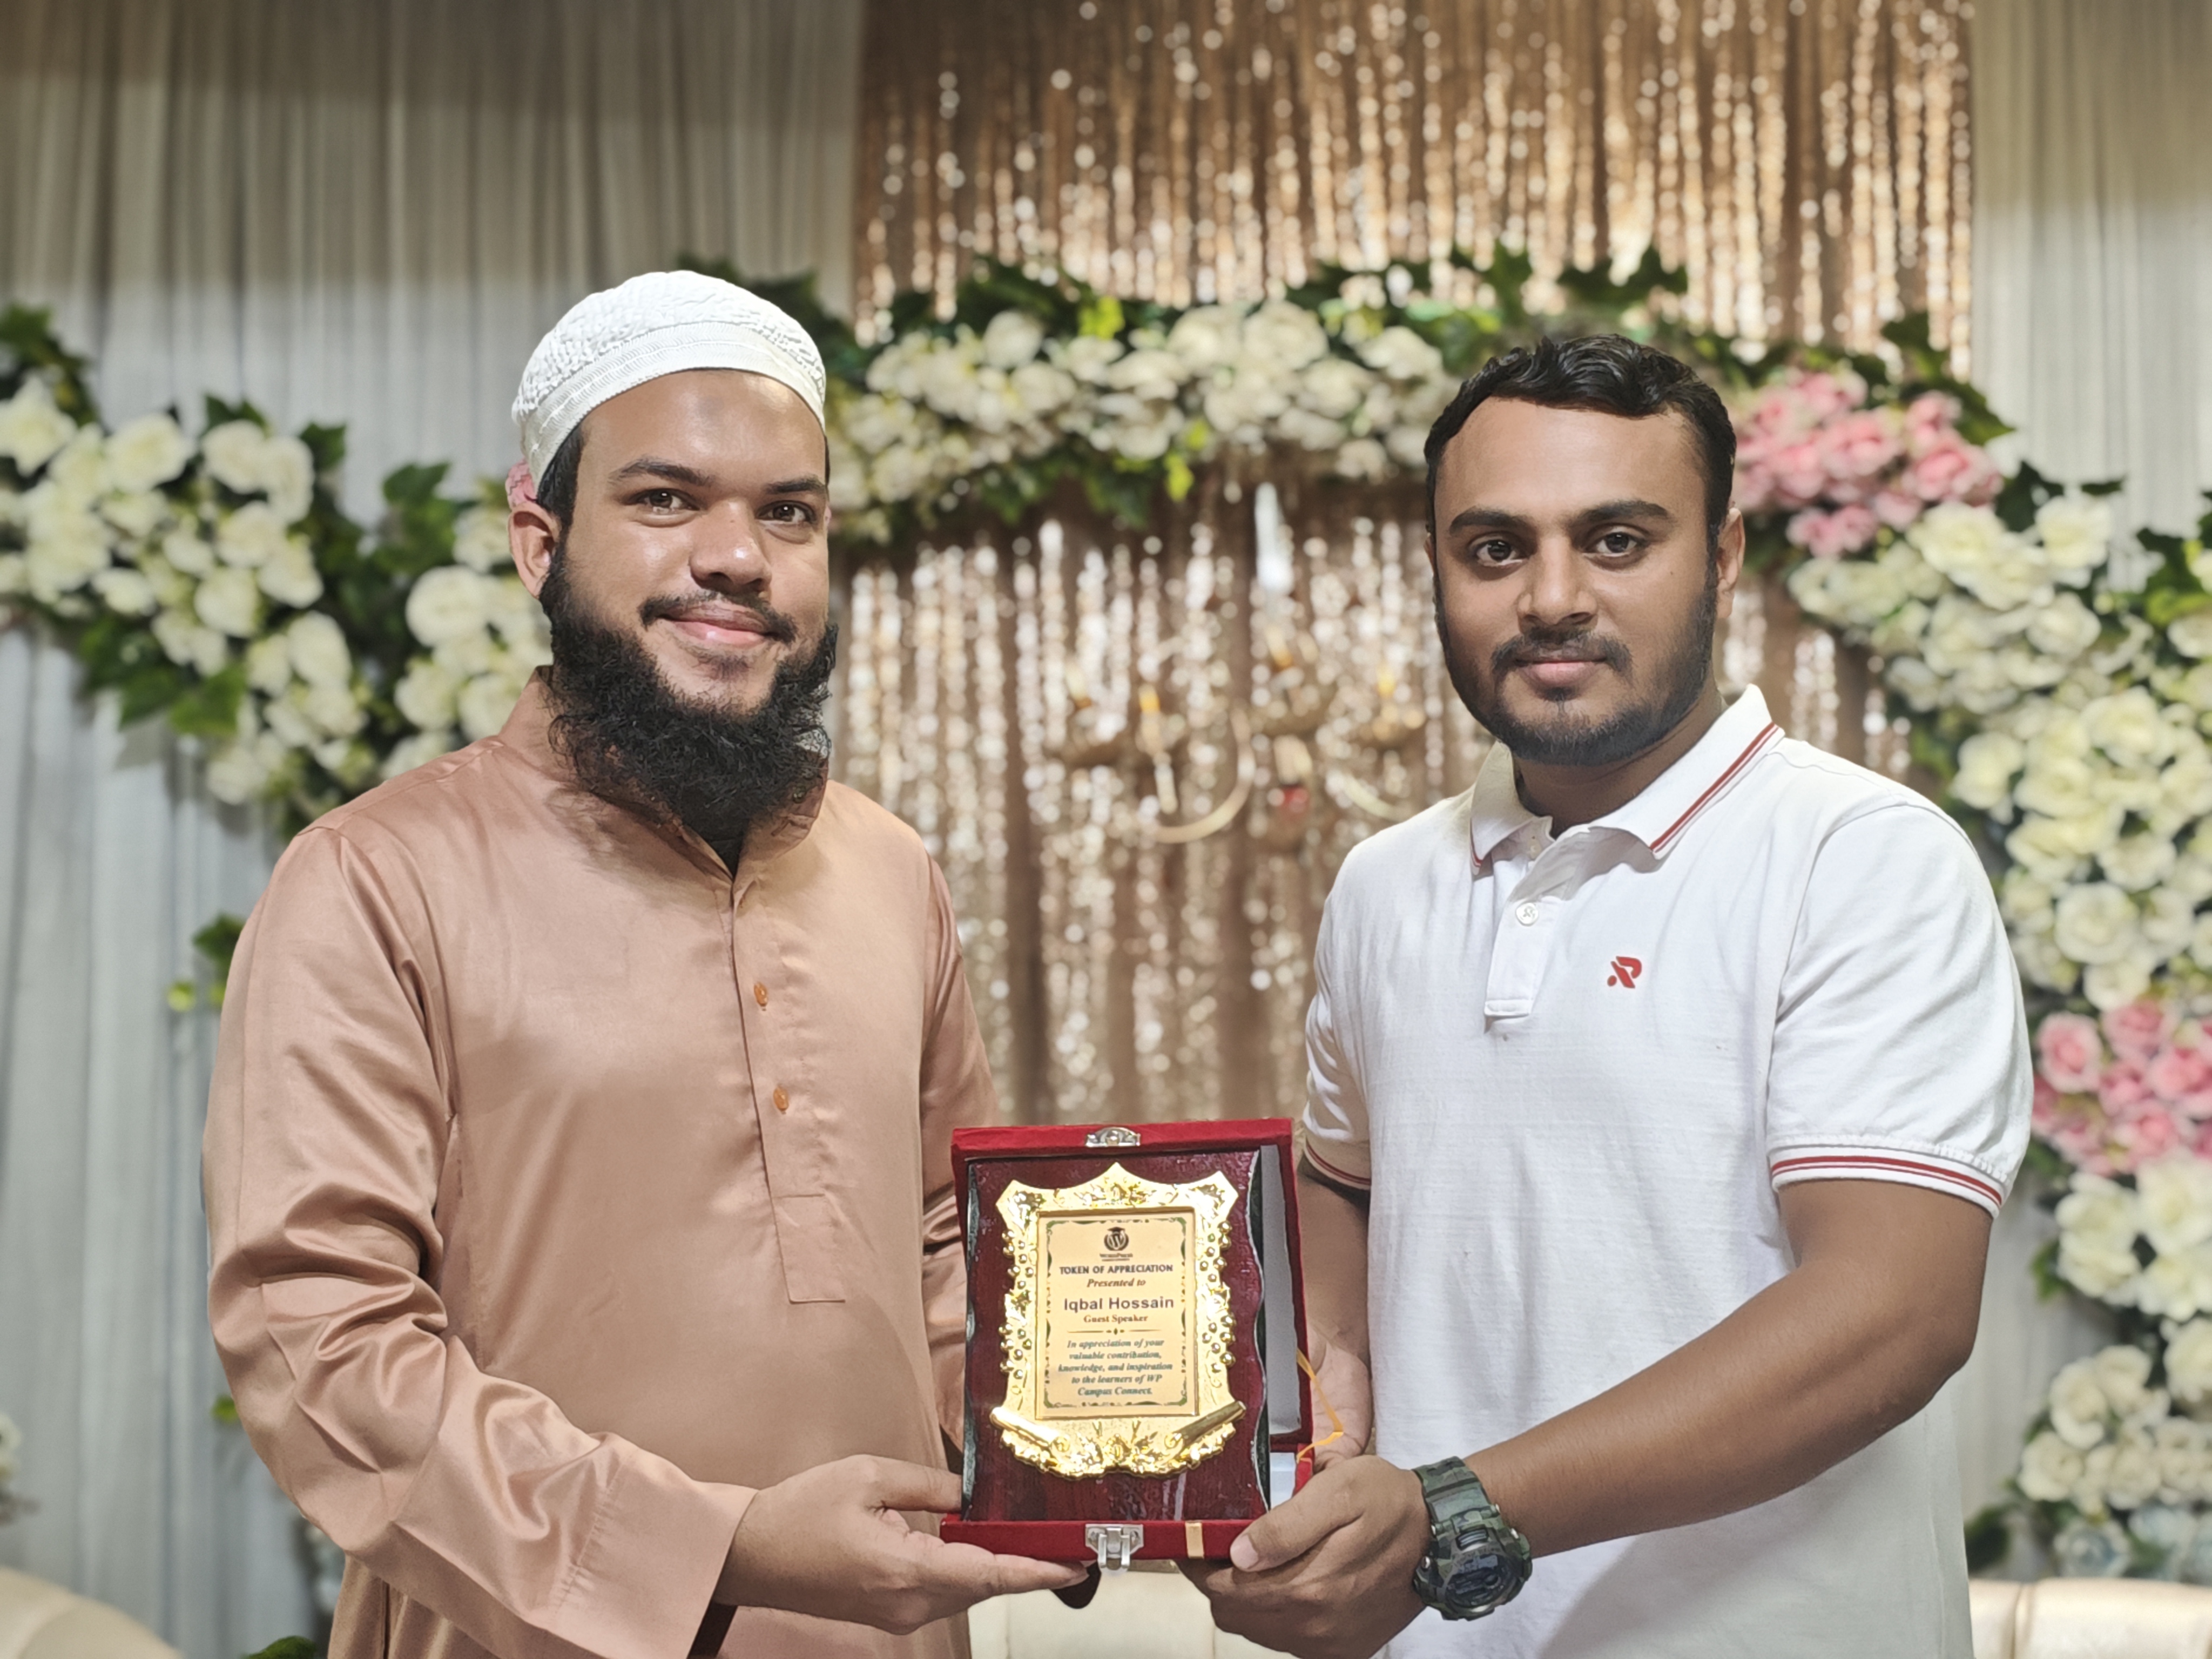
#TravelSteps #WordPress #WordPresspluginWordCamp Central: WordPress Campus Connect Ahmad Education, Dhaka 2026
The Truly Meaning moment in this event
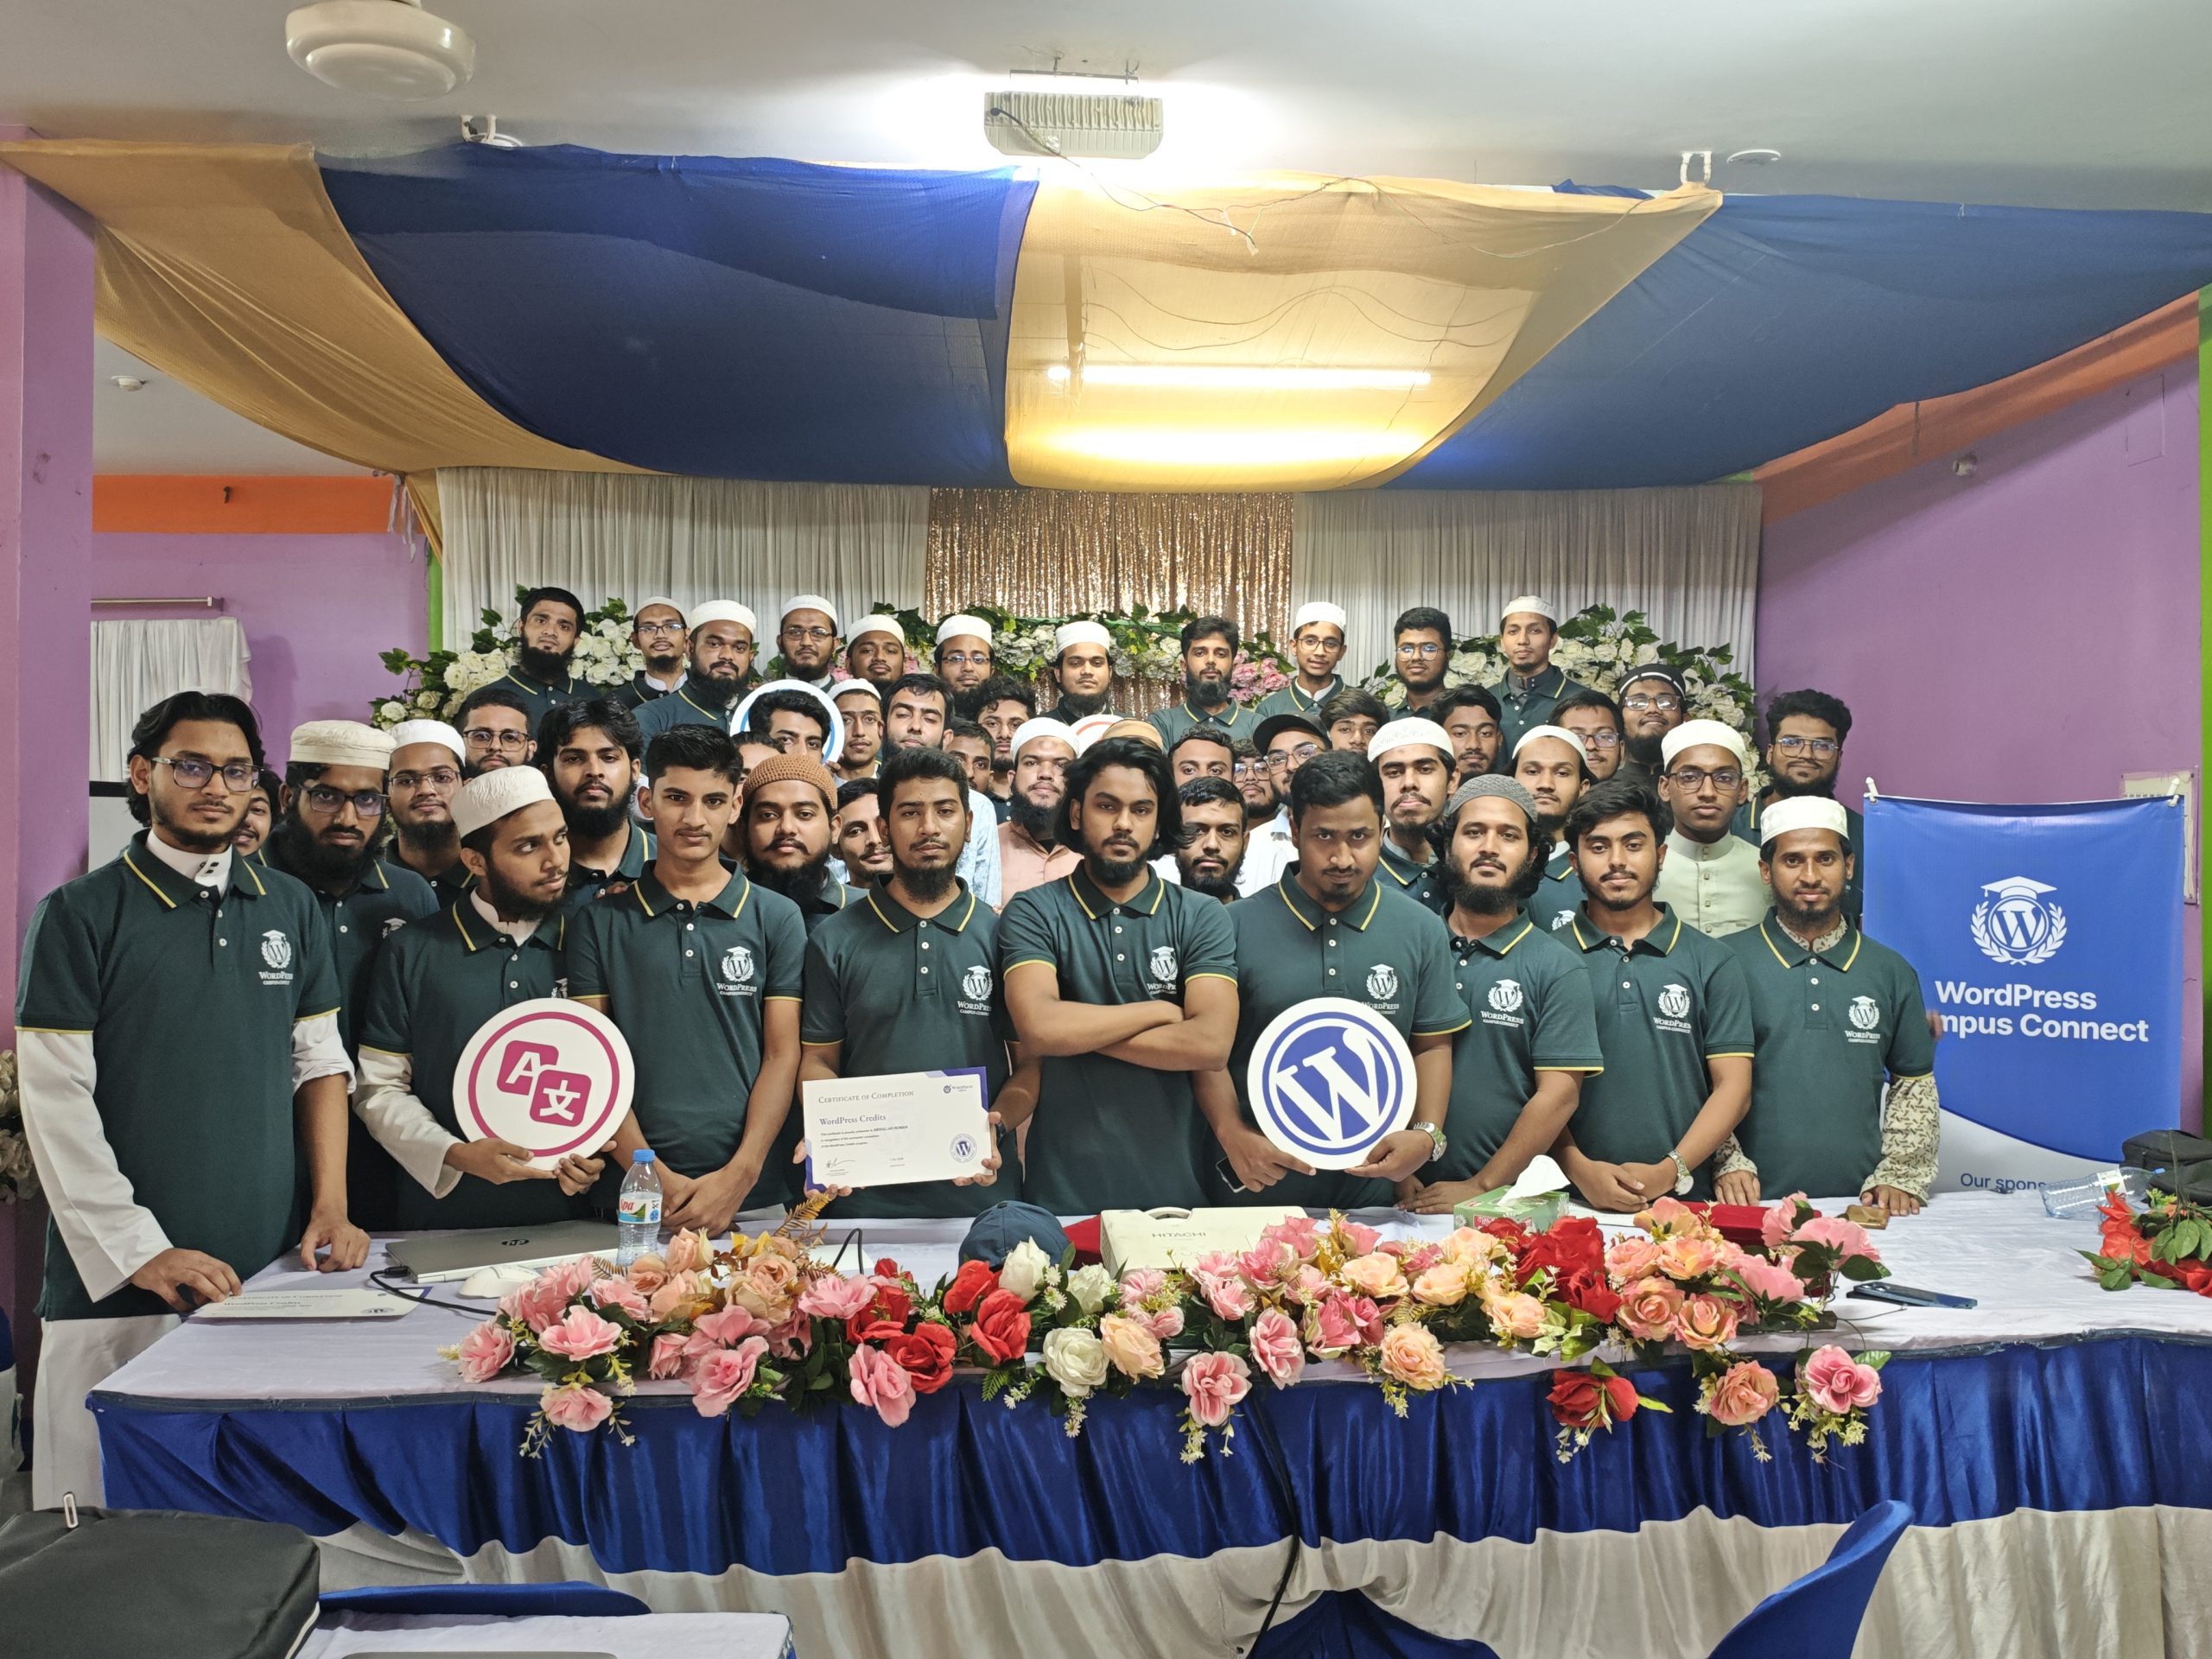
Campus Connect Event Successfully Completed!
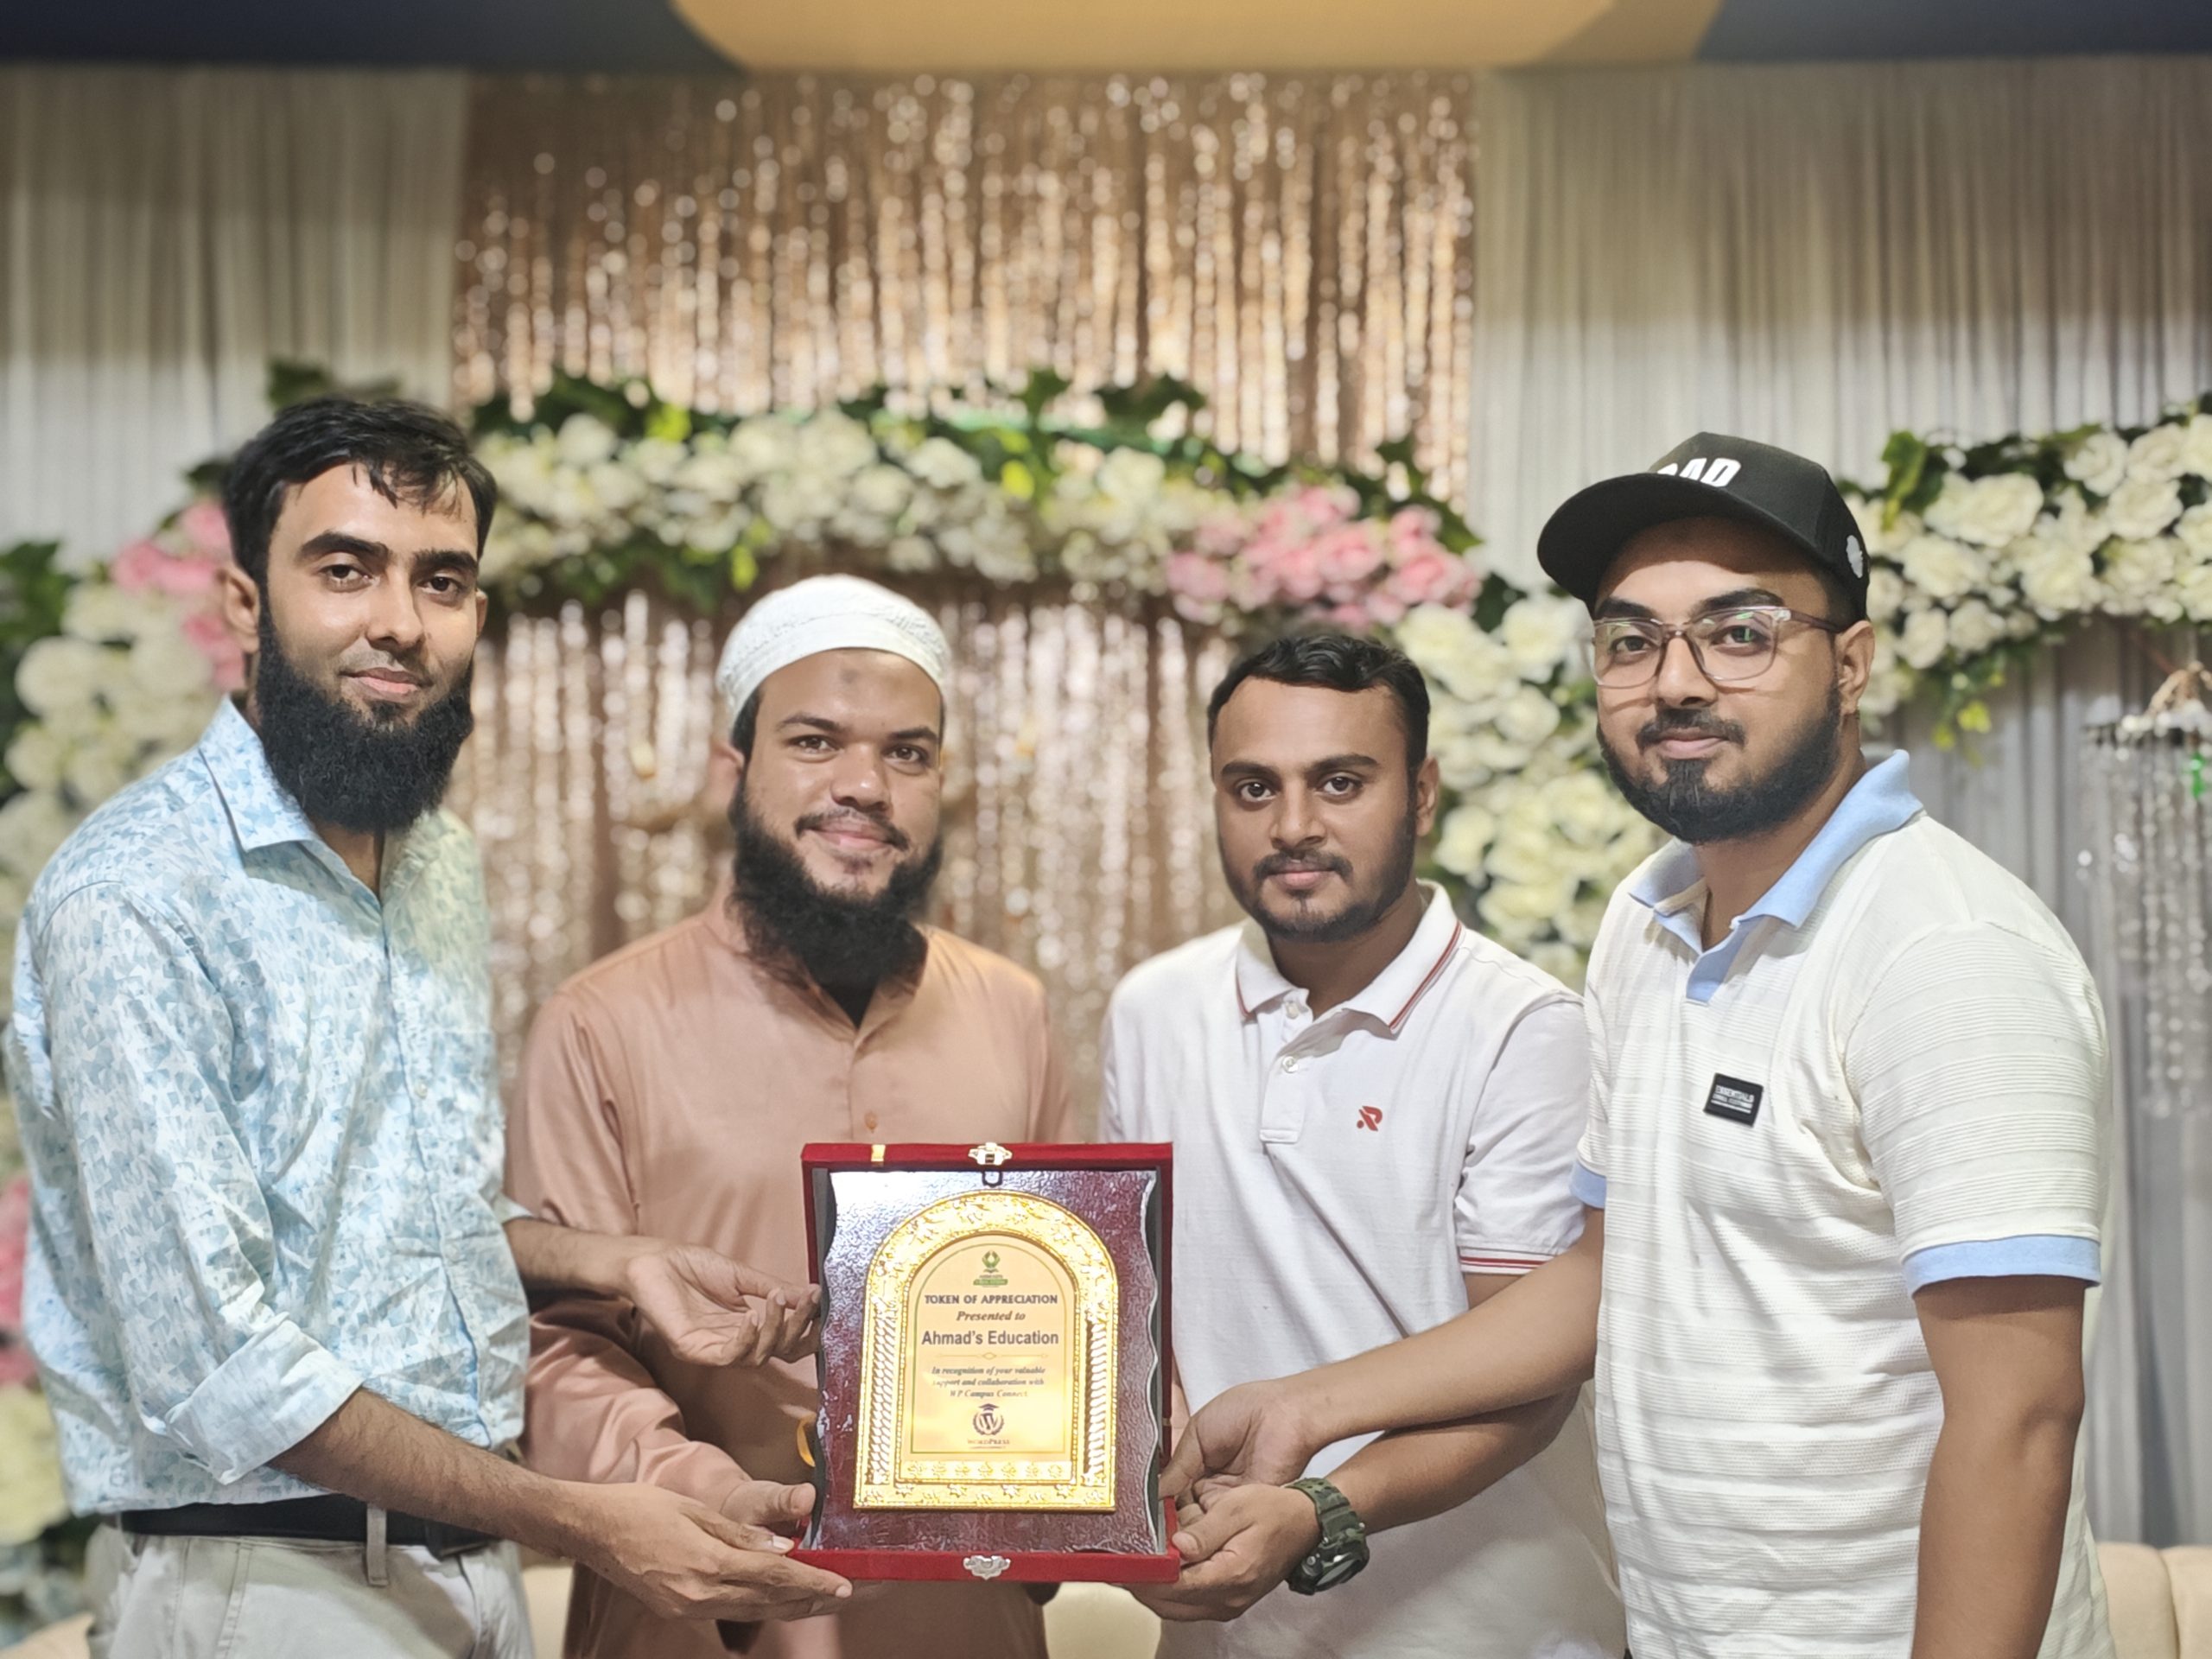
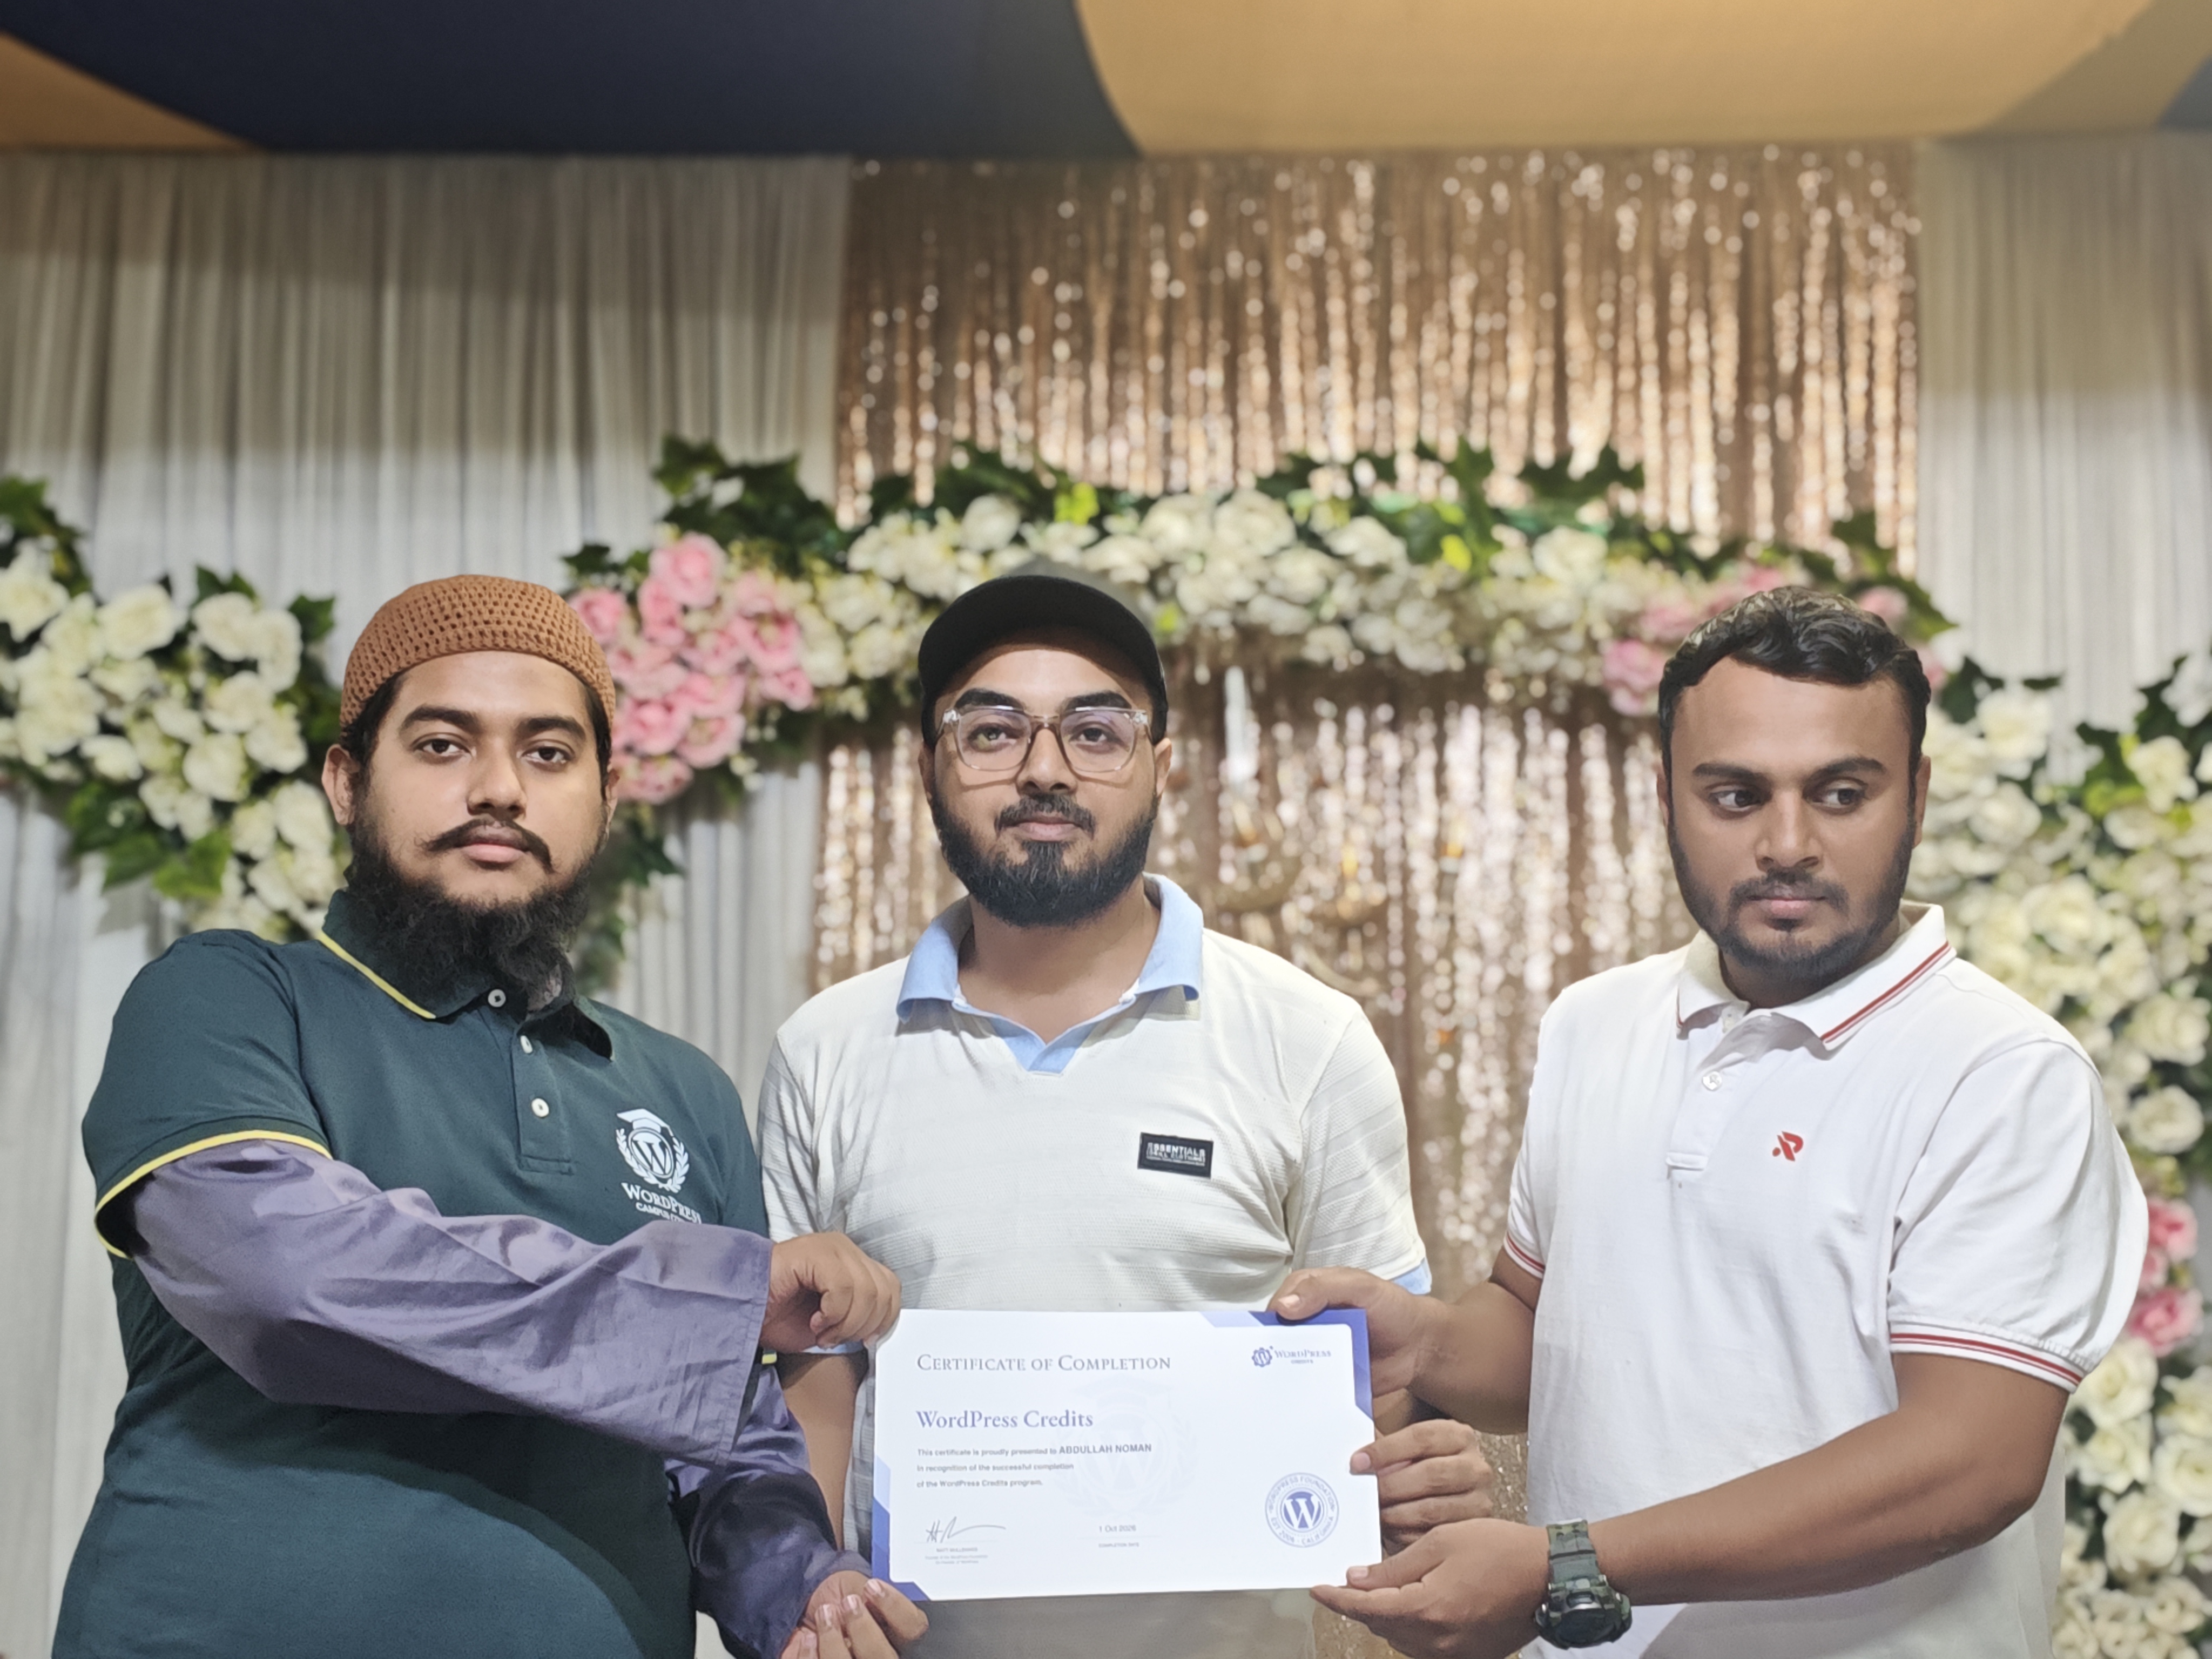
We are pleased to share that the Campus Connect event, held on Thursday, October 1st, was successfully completed with the participation of students from Ahmad’s Education.
Ahmad’s Education has already collaborated with WordPress and successfully completed two batches. This event was another valuable opportunity to strengthen our collaboration, share knowledge, and inspire students to explore new learning opportunities.
A heartfelt thanks to the WordPress team, the organizers, and all the students who contributed to making this event successful.
Looking forward to more collaborations and learning opportunities together!

Open Channels FM: Why Fast AI Inference Is a Game Changer for Developers
In tech, speed can make all the difference. One topic that doesn’t get enough attention is just how much faster AI inference is changing the way developers work. Training AI models still grabs the headlines with all the talk about big clusters and huge data sets, but the real impact for most developers happens when […]
Dennis Snell: Radical explorations in agentic development
In mid-April 2026 my employer started a project called “Radical Speed Month” to step away from our existing structures and processes, make space for people to dive more deeply into AI tooling, and try to build new or sleeping ideas. My participation in this experiment ran until late September and I stacked up a lot of explorations without having written about them or about the process. In this post I’d like to highlight some of the results of this time and share some learnings.
Selected lessons
- Massive agentic deployment demands heavy storage and generic compute capacity — inference is not the only bottleneck. This is necessary to support massively parallel checkouts of code, benchmarking, analysis of other software and data, running hierarchies of thousands of test workers and headless browsers, generating and analyzing image and video artifacts, creating indexes, and more.
- Instructing an agent to “find the five hidden defects” is more effective at finding real issues than asking if there are any hidden defects. They may return false claims, but they try to answer the questions they are prompted — it’s not that different than the comparison between asking someone what in their day brought them a smile, or what was difficult for them, rather than asking “how was your day?”
- Agents with web searching capabilities are powerful knowledge-retrieval and aggregation tools. Reports they generate to aid in developing code can be more effective than asking the agents to generate the code directly.
- Models today are incredibly powerful, but guiding human insight is also powerful. Autonomous agentic activity demonstrated a tendency to produce more evidence of accomplished work than actual accomplished work. In a strange way this might reflect the training dataset: corporations must also guard against the dangers of overly-burdensome paperwork.
Projects
All of the projects here were almost entirely built by AI agents, but with my guidance and supervision. Therefore, credit for each of them does not rest entirely with me. However, for the sake of brevity I will omit mentioning in each one that AI tooling was the actual producer.
Each project below is assigned a truly unscientific evaluation:
 The project succeeded with clear value.
 The project completed its goals, but the value is unclear.
 The hard work has completed, but I need to close the loop and deploy it.
 The idea is sound but not ready; it needs more development.
 The project failed to bear fruit for any reason.
My personal favorites:
- Fix bugs in proprietary hardware drivers
- Gather empirical evidence to guide development decisions
- Stream real-world HTML from Common Crawl
- Provide deep insight into PHP script execution
- Rapidly prototype a comprehensive collaborative editing environment for WordPress
Tools
Because I expected a short availability for the enhanced AI access, I prioritized building, early on, tools whose value would outlast the project. Generally I prefer working in offline or local environments, so I built archivers for several services which are only available when connected to the Internet.
While MCP servers were very popular at this time, I have always been unhappy with the load centralization and amplification they create. The same is true for any online resource against which agents perform searches. My intuition is that it’s more considerate to those services to make one batched update, to download all new data since the last sync, than it is to make repeated queries which might overwhelm their servers and fetch the same resources over and over.
Being offline and local, the archivers are extremely fast and operate in the terminal where I prefer to interact.
GitHub archive
Finding GitHub’s search functionality lacking, and wishing for a chronological stream of my activity, I built github-archiver so I could have the tools and performance I wanted. This initially supported searching through PRs, issues, and comments, as well as rendering my own activity in a reverse-chronological view. I eventually added two additional views for replies: people I replied to, and people who had replied to me. This gives me great awareness of my recent conversations and has helped me to avoid losing conversations. Sometimes I struggle to find a PR that I meant to follow-up on, but it disappears from my GitHub notifications and I can’t remember the exact wording that will turn it up in a search result. I even tend to forget in which code repository it was left, so my tool aggregates activity across all archived repositories.
The basic design is a compressed HTTP cache of the GitHub API. When fetching or updating, it respects rate limits and leans on HTTP headers to avoid wasted transfers. After some work with banking APIs several years ago, I found that storing raw HTTP responses proved more flexible than parsing into a custom internal data type, as it lets me rewrite logic in the app later without having to re-download the entire archive. This came in handy several times as I expanded the search index and added more functionality.
The tool renders GitHub content as richly-formatted and highlighted text in a console unless running outside of an interactive TTY. It renders Markdown and HTML content into this rich text format and lays out meta elements in a meaningful way. Its speed, zero-network dependence, and minimized output make it a good fit for agents that would otherwise be hammering GitHub’s API, waiting, and wasting tokens on irrelevant content.

Trac archive
Just like the github-archiver, I built a trac-archive for WordPress’ Trac system. It is feature-similar to the GitHub archiver, but provides an additional perk: because bots relay messages from GitHub back into Trac, issues often have two markup formats in use simultaneously. My trac-archive first parses its content according to Trac’s own system, but then it additionally parses Markdown where it finds it. It shares much of the rendering logic with the github-archiver and provides a clearer experience than the web view due to the additional parsing, syntax highlighting, and ability to exclude bot traffic from the results.

Review the evolution of a series of commits over time
git-sequence-patch was used to help me understand the full scope of the WordPress collaborative editor project. Since many large features or projects span many commits and possibly even months or years of work, this tool reads a number of git commit SHAs and will build a fictitious patch that more or less represents how the entire project would be proposed were it to be proposed against the latest branch head. Another way to look at this is to generate one massive revert commit for the original feature and all descendant changes to it since its inception.
This is a project I had been wanting to build for a long time; for each of the given commits, it tracks which lines were changed by the commits, and then steps forward through the branch history, noting when other commits also modify or remove those lines. Once it completes at the branch head, it prepares a patch to replace all of those lines with the code that was there before the original patch, and reverse the patch. This means that it doesn’t produce a patch that would actually merge, but it produces a patch that’s useful for understanding the full scope of how a change evolves over time.
It’s line-oriented and so would miss some obvious scope. For example, if tracing the sequence for a new function, it will miss a later change which calls into that function. This would actually be possible to add to the tool as an enhancement, but it wasn’t necessary for my purposes at the time and I think it would remain ideally an option rather than a default behavior.
I spend a lot of time trying to quickly understand entire systems that I didn’t write or have any experience with, and this tool is a delight for answering the question: “how has this change evolved through time?”
Analyze real-world HTML from Common Crawl
To better test the HTML API against real HTML documents, I built cc-analyzer, which feeds data from the Common Crawl index into a user-supplied PHP script. This operates in two modes: streaming and batched. In streaming mode it continuously sends HTML documents from the archive into the analysis script. In batched mode, it saves documents from the archive into a subdirectory and then may be invoked again to re-run those documents through specific analysis scripts.
This project has greatly benefited the testing and verification of the HTML API, and informed decisions about what actual HTML syntax patterns exist on the web and what concerns are practical and which are esoteric. Throughout this grand experiment I have examined hundreds of thousands of HTML documents to test the HTML API code, to understand reported and actual text encodings of websites at large, to benchmark changes and optimizations for the HTML API, and to understand parsing needs of real HTML documents.
Instantly search code from the WordPress ecosystem
Veloria.dev (formerly WPDirectory.net) provides fast code search across all of the plugins and themes listed on the WordPress directory. It was experiencing elevated outage rates and I decided at the start of September to recreate it locally as a single binary with a simple compressed offline archive. Previous efforts to slurp the directory left efficiency gains on the table and output around 120 GB of data on the filesystem. By taking advantage of available concurrency, streaming computation as resources are downloaded, pruning the stored files to those which were being indexed, and saving into a custom compressed binary object, my wp-code-search tool was able to archive the directory in five hours storing only 5 GB among three data files: a compressed archive of the source files, a search index, and a metadata archive.
This idea originally came from Dan Luu, who commented that “if we’re repeatedly searching for text on a computer, the obvious thing to do to speed that up isn’t to write a native code compiler for regex matching, it’s to create an index.” Code searches across the entire directory typically return within 10 ms, output syntax-highlighted snippets from the files in which they are found, and the tool can extract those files or entire plugins from the compressed archive. The index is sorted by active installs so the most-deployed results appear first.

This tool has become an invaluable daily driver for me as I refactor Core WordPress internals and want to avoid needlessly breaking existing code.
Towards the end of September I had another long-shot idea: could the ideas making the text search so fast be mixed with structural queries so that I could perform data-flow and control-flow analysis on the code? Turns out that yes, with another 5 GB sidecar index, and a custom WordPress-specific query syntax this was not only possible, but practical with many complicated queries executing in anywhere from a few seconds to a few tens of seconds.
There’s a lot of power in this query syntax to identify complicated code structures and I still have to learn how to generate the kinds of queries I want to. I built the structural code search to aid in discovery of risky code patterns to harden as part of my work improving WordPress’ security stance.


Text-mode access to the modern web
My zs tool performs web searches and downloads rendered HTML pages in the terminal. Fascinatingly enough, when I attempted to start this project I tried explaining very clearly that I wanted to adhere to the terms of use for all services, that I wanted to respect the remote servers providing the content, and that this was a user-agent acting on my behalf to perform queries in the terminal instead of a browser. Unfortunately, it seems like the instructions to follow the rules were misinterpreted as attempted bypasses and overly-refused.
Regardless, I was able to create this non-GUI browser and build up enough of the Web Platform to render the pages I wanted to view. When Captchas and other verification interstitials appear, they render inline into the terminal via terminal raster commands. I’m able to indicate which boxes contain the bus, or motorcycle, or a bridge, which Google seems really intent on learning, and continue with text flows and shell pipelines.
My motivation for building this was to perform web searches from the CLI, but once I had the mechanisms in place to interact with the search engines, I realized I could also use this to grab dynamically-rendered pages. For any given URL, a page loads, executes scripts, and renders until the JavaScript event queue empties or a timeout trips, and then the final DOM serializes into the HTML output.
This makes the tool more valuable than my typical curl flow, which too-often downloads an empty HTML page reminding me that I should be using JavaScript. Because it implemented so much of a browser’s internals, I added a feature to extract the visible text content of the rendered page, something which is surprisingly difficult to download without a full browser and CSS engine, and something which is really valuable when trying to pipe documentation pages into coding agents.
All in all it’s a bit buggy and I would like to start over based on what I learned along the way. It still works sometimes and it’s valuable to me when web pages return otherwise-empty mountains of script contents.


WordPress.com
Clarify wording in notification messages
WordPress.com sends notifications about comments, likes, follows, etc., and sometimes the wording is awkward or inconsistent. I generated a report classifying emotional content of the wording and suggested improvements to better inform the reader of what they could or needed to do. It was effective at joining snippets of strings that are concatenated together throughout the code and provided useful insights. It also provided good suggestions for updates that focused on removing anxiety and clarifying possible actions to take in response to the alerts (e.g. replace “Renewal Failed” with “Payment did not go through; update by May 18 to keep your plan active”). Unfortunately those updates are still on my backlog to deploy.
Migrate confused legacy data to simplify runtime code
There are old notification records in the database with conflated and truncated values, and these require complicated code when rendering them to make sense of the confused properties. I was hoping that it would be possible to have the AI examine these broken records and the generating code and provide clear guidance on how to update them. Among 3,000 old records in the database, it proposed seventeen cases for recovery and fixing. Unfortunately this also sits in my backlog to assess and apply.
Fix translation issues and typos
Developers frequently concatenate separately-translated strings which lead to confusing translations. I ran an analysis for this kind of translation issue inside the notifications source code and also for typos and other mistakes. This produced a list of around fifty bug-fixes, including for a missing namespace specifier that was broken for more than a decade and which hadn’t been noticed in error logs, malformed HTML tags which had been hard-coded in string literals, plenty of concatenated translated strings, broken interpolation placeholders, missing calls to the translation function, and missing null checks. This was deployed in May to the production system.
WordPress, the open-source project
Generate automatic previews for dev-docs changes
WordPress Playground runs a copy of PHP and WordPress entirely in the browser via compilation into a WASM environment. It provides testable previews for WordPress and Gutenberg PRs. Missing has been a way to preview changes to the generated developer documentation, which is notoriously difficult to get running at all, let alone dynamically in a browser. I proposed a demonstrator in #29 that does just that through a GitHub Actions workflow on PRs. It has inspired follow-up, but due to the need to ensure a maintainable solution, is still pending deployment.
Harmonize the ignore ruleset across git and Subversion
The official WordPress source code lives in Subversion with a git mirror. The .gitignore and Subversion ignore rulesets are fundamentally distinct from each other, notably in that git ignore patterns apply recursively through a file tree. I attempted to use AI to harmonize the rulesets. Some adjustments were made, but the entire set still needs careful review.
Visualize per-package activity within Gutenberg
To better understand per-package activity within the Gutenberg editor project, I produced a visualization showing commit activity.
Provide deep insight into PHP script execution
Inspired by my childhood Gameshark, I built a PHP extension to improve my ability to debug and analyze PHP script runs. This started as a way to compare two runs of a given script, but expanded into a set of related but distinct modes.
Differential mode compares which functions were called and how many times across two different script runs; this could be useful for performance optimizations or comparing what runs for two different code paths and was built initially while working on page renders vs API call responses.
Trace value records every function or method call whose arguments contain a requested value. It tracks user space as well as builtin functions and was built to help identify code paths which send untransformed data where it shouldn’t reach. A follow transformations option tracks not only the given value, but also common escaped, encoded, serialized, quoted, slashed, and other variations of it. This is a clever security tool for finding out where and how unwanted data is passed around.
Invariant mode takes a PHP file with “hooks” that attach to functions and methods, either during entry into those contexts or when returning from them. They are supplied the values to the arguments, the $this value if a method, and the return value if a post hook. This enables a novel approach to applying software contracts on code with neither the production runtime overhead nor the noise from the contract-enforcement. This was loosely inspired by Clojure’s core.spec. Because the hooks file is user-space PHP code with access to global state, this provides mechanisms for enhanced testing and analysis code, and when registering a shutdown handler in PHP, can print reports at the end of script execution. Hooks may also raise exceptions to halt execution when any desired invariant is violated, such as when preg_match() receives a pattern that might be attempting to parse HTML.
Unused runtime coverage mode generates a report of all loaded identifiers which were never read or executed during a script execution. A sampling option can be used in production to assemble such a report, probabilistically, over time. This mode was designed to find effectively dead-code that might be lurking behind runtime conditions which can never actually run due to real data distributions. For example, a function which is only ever called before a given date, when the given date is several years in the past. Static analysis will miss this while a month of production sampling with no calls will provide evidence that it’s safe to remove the function, that no other strange or unexpected call-paths are still calling it.
Trace allocations mode traces heap allocations made by PHP during a script execution. It immediately surfaced unnecessary allocation in wp_is_numeric_array(), which was promptly eliminated in [#12100].
This extension has provided incredible insight into how WordPress and other PHP scripts run, and I’ve only scratched the surface of how I can take advantage of it.
Introduce dynamic security policies into PHP with eBPF to isolate plugin code and extensions
Like the php-gameshark extension, I built a modified php binary which coordinates with eBPF in the Linux kernel to apply dynamic security policies and create isolated security domains within executing PHP code. There is no logical separation between executing the Core WordPress code and the code from plugins running on a site. This is a security challenge because the two kinds of code warrant different trust, and a site operator may want to assign unique trust and capabilities to different plugins.
This extension provides a wp_runtime_security_apply_policies() function which registers sandboxing rules against files whose source code matches the provided glob. It allows disabling network access, shell execution, sending of emails, reading uploaded files, and writing uploaded files demonstrating a path towards securing WordPress sites from errant or malicious plugins, as well as an explicit opt-in capability model for plugins as they have need. It doesn’t just protect user-space PHP code either; thanks to the fact that policy enforcement occurs within eBPF, it can also apply the same policies against compiled PHP extensions running on the host, assuming that the extensions are not actively attempting to exploit the guards (the protection is aimed at security vulnerabilities within the commonly-deployed PHP extensions, not against potentially-malicious extensions).
I built this extension after a discussion with Lynn Griffith at WordCamp US in late August. It seems promising but is under-developed and needs production testing. As it relies on eBPF, it only supports Linux environments, ruling out Windows, BSD, and macOS-based hosts.

Benchmark HTML parsing optimizations against realistic data from the Internet
With the aid of cc-analyzer, I automated the benchmarking of numerous optimizations that we have explored over the years with the HTML API, mostly changes to the internal data structures and how attributes are represented during the parse. The AI tooling provided the run-scripts for cc-analyzer, invoked it, and gathered the results. It also collected PRs that I had proposed (using the github-archiver) since May 2023 so that I didn’t have to find them.
Fuzz-test the HTML API
I fuzz-tested the HTML API, finding several unreported bugs, including easy-to-overlook defects in the code. Fuzzing in this way also prevented a number of defects with the rewrite of wp_kses(). This complements the existing spec-compliance tests against the html5lib test suite, practical tests against real HTML from the web, and a unit-test suite covering intentional behaviors.
Scaffold fuzz-testing in Gutenberg
I attempted to build a generalizable fuzz-testing infrastructure for the Gutenberg editor. This was an extended autonomy agentic session that ultimately produced a good-looking dashboard with nothing but false-alarms. I tried to establish a framework in which other developers could easily add new generative categories and the system would run new fuzzers for them, compare outputs, and triage failures. AI parallelism made for impressive work, but in this early project I was unable to accomplish my goal and gave up on the idea.
Port data sync libraries into PHP
As an experiment in goal-oriented design, ten distributed data structure libraries were ported into PHP userspace code to aid in building a demonstrator for the DE-RTC prototype [#12334, #79602]. With minor caveats, this built working copies of yjs, automerge, loro, diamond-types, diff-match-patch, json-patch, json-joy, sharedb-json0, prosemirror-collab, and collabs which passed their upstream test suites when they were converted to call the PHP code. Eight of the libraries were completed within a few days, but loro (the library I was primarily interested in) and json-joy held out the longest, taking weeks to complete. They appeared stagnant for the bulk of that time and rapidly finished passing the remaining tests in a burst at the end. While I had originally built a prototype collaborative editor with yjs (which is what the existing project team had chosen to use in JavaScript), once automerge completed I was able to swap out the synchronization primitive and later do that again with loro, adding the capability to make more semantically granular changes and merges. This work was almost entirely hands-off and ran in the background until it was completed; every ten minutes it updated an HTML dashboard showing status and operating notes.
Fuzz-test the proposed collaborative editor for WordPress
From the end of April until October, I paired with Dan Luu to fuzz-test the collaborative editor proposal, and we uncovered an array of issues which ultimately led to changes in the timeline for the project, as a number of the defects were nontrivial to solve. Most of the fuzz infrastructure was built by Dan, while I attempted to coordinate the reproducible bug reports with the rest of the team and to propose fixes. The fuzzing machinery produced effectively no false positives due to the triage and reproduction steps built in. It also provided the visuals for theoretical bugs which are hard to diagnose manually with a keyboard and mouse, but which actually occur frequently in concurrent systems.
This was a high-reward project for the investment because, while AI was dominant in the early code generation, once the testing suite was established, it was able to continue to operate without much additional AI input, and it’s possible to run without any AI inputs.
It highlighted two aspects of fuzz-testing: the more robust the code being tested already is, the more valuable the fuzz-testing will be; and the more frequently a bug is likely to materialize, the more quickly fuzz-testing will find it. There is a good match here between the needs and the operating characteristics.
Actually, Dan and I were originally looking at working on other projects for this Radical experiment. I had suggested that we use the nascent collaborative editing project to organize our notes and work within a WordPress site — to “dogfood” the editor. We pivoted to this testing and design support role only because of problems which immediately appeared as we tried to use it.
Prototype a comprehensive collaborative editing environment for WordPress
To demonstrate another approach to collaborative editing, I instructed an agent to follow my core principles and requirements for the task and build a prototype. At first I wanted the agent to mimic forming its own company, planning, dividing labor, and harmonizing productivity, but as this ran for weeks it kept descending into a cycle of producing more and more meaningless paperwork with less and less actual work. Around the end of May I rebooted the project with far more direction and guidance, replacing the goal-oriented and hands-off approach with a human-driving-the-loop method. This proved more effective and in two weeks I had a working prototype that demonstrated every aspect that I considered important and lacking in some of the other public proposals. At some point I will share a version of an internal post I wrote summarizing this work. It proved influential on the project and I believe that the continued development of collaborative editing is heading in a stronger direction as a result.
For years I have struggled to adequately convey why specific principles and requirements are important, but having a visual prototype made it feel real in a way that persuasion had failed me. The amount of up-front work to produce this prototype had been obstructive for years, and without the agent I would not have been able to communicate the tradeoffs involved in its approach.
Restore developer documentation generation by updating deprecated legacy code
At the end of February I had restored WordPress developer documentation which had been stale for two years due to failing build scripts and deploy scripts. While this work resolved most issues and unlocked updated docs for WordPress 6.9, there remained a few unresolved issues which led to specific submodules being excluded from those docs. In mid-May, fixes for the remaining issues were applied to the dependent projects which removed all remaining barriers. All documentation was updatable again and the scripts could run in the latest PHP versions without crashing.
Prevent mistakes in commit messages and automate the repetitive parts of writing them
After seeing my colleague Jon Surrell’s neovim linter for writing WordPress commit messages, I ported his linter into a single-binary/stdout LSP usable in any LSP-supporting editor. This expanded the work Jon did and built upon work from my other tools to show inline previews of Trac tickets and GitHub PRs. It included new auto-fixers for formatting and line ordering and I use this today to prepare my commit messages, avoiding mistakes I have overlooked in the past.
Gather empirical evidence to guide parsing decisions in the HTML API
I used an instrumented custom build of PHP and lexbor in September to answer a perplexing question: “how many tokens of lookahead would be required for the HTML Processor to fully-parse a given percentage of all HTML documents?” This stems from the tricky re-parenting issues in HTML tree building, where a syntax form at the end of the document could appear towards the start of parsed tree structure. The instrumented code examined when lexbor ran its “adoption-agency algorithm” and tracked how much further into the document the current token appeared after the token associated with its actual parent node.
An hour-long run of cc-analyzer showed that among 70,000 documents, approximately 1,000 require at least 1-token lookahead, only about 250 could parse with 5-token lookahead, and 13 would have required more than 10,000-token lookahead! In one case, a document contained an un-closed <b> tag near the start of the document, and then 400 kB and 35,000 syntax tokens later, triggered re-parenting — no default behavior will offer 35,000-token lookahead.
The outcome of this run was disappointing, but the data was invaluable and prevented wasting time implementing a lookahead mechanism that wouldn’t meaningfully benefit consumers of the API.


Review and scrutinize code change proposals
Throughout the entire experiment AI was providing valuable code review and patch preparation. WordPress security fixes are typically backported to WordPress 4.7, which covers 25 released versions and trunk. Many of these support older versions of PHP missing standard-library features that newer code depends on, and lack WordPress functionality that newer code depends on. When preparing a backported patch, I created reports detailing which features and functions had to change at each WordPress release, and what was driving that need. I found these to be more useful than having agents automate the backporting as fewer mistakes were overlooked when I was performing the changes with the assistance of the reports.


AI code review was invaluable though during the refactor of wp_kses() within WordPress. For weeks I instructed it to find the remaining overlooked defects that need resolving before merge, and it kept finding places to harden or fix the code. I never asked an agent to perform “code review” or indicate if a patch was ready to go. Instead, I instructed them to find hidden defects that I wasn’t sure existed, but when told to return three items, they would do it! I consider these kinds of situations among LLMs’ greatest strengths, when false negatives are more costly than false positives, and when validating claims is trivial. Every issue the agent claimed became a test that proved or disproved it and now guards against regression.
Simplenote and Simperium
Implement well-defined feature requests in unfamiliar code
To explore autonomous feature development, I had an agent resolve a concrete bug report describing difficulty copying content from historic revisions of a note [#3358]. This kind of enhancement/fix was frustrating previously because it touches numerous parts of the codebase I was unfamiliar with. The models picked up a number of places I would have overlooked when working on the problem.
Document confusing data flows in unfamiliar projects
The data service powering Simplenote was written with untyped Python code, and partial duck-typed data structures are passed around which can make code comprehension dizzying. While I wanted to avoid AI-generated code changes, given how critical the backend is, in late May I produced comment-only changes annotating data types and providing explanatory comments where certain code constructs were unclear. This was a low-effort way to pass along some insight about the code in hopes that it makes someone else’s job clearer in the future, as I have not maintained this codebase for years.
Random
Monitor Codex usage
codex-usage-report.py scans the ~/.codex directory and summarizes token counts, the models which were used with them, and approximates the dollar cost of that usage based on current API pricing.
Export Codex usage into a searchable format
As the radical experiment was drawing to a close, I created a Codex exporter which dumps the session data into a giant single-file HTML archive where I can search interactively through the sessions and view the chat history, including tool calls, in a rendered view. I’ve referenced this several times as it’s quick and easy compared to logging into a server, finding the right session, and searching through its history.
Run inference on unsupported legacy hardware
My old MacBook Pro came with a dedicated Radeon GPU and sits idle or off most of the time. llama.cpp doesn’t support the older GPU and so I wanted to see if I could get it running. It did produce a working copy that runs local inference on the Radeon GPU, but in practice it underperformed the CPU-based inference for the same models. With only 4 GB of VRAM, it couldn’t load enough weights at one time to operate without constantly transferring data, and the transfer overhead was too high. I explored different means of sharing work between the CPU and GPU, but they were fighting for memory bandwidth.
While this didn’t provide me with a low-and-slow inference engine, it demonstrated the ideas and ran the experiments which is something I had little patience for, given that I expected poor usefulness in the best of cases.
Fix bugs in proprietary hardware drivers
At home I use my Fujifilm X-T3 as a webcam. It makes for a great quality video feed, but when Fujifilm updated the camera driver to integrate with one of the previous macOS updates, they introduced a memory leak which would end up using 90 GB+ of RAM plus swap by the end of a call and sometimes take down my system before I realized it. Knowing I had little hope of motivating Fujifilm to fix this, I made a binary patch to the driver and fixed the bug directly. This was directly inspired by stories of Microsoft fixing bugs in components whose source code they had lost.
To my delight this fixed the memory leak and provided a plausible explanation. By decompiling the driver, the AI found a missing call to release JPEG data from each frame after passing it to CMIOSampleBufferCreate — a classic memory bug. It predicted the impact of this defect and confirmed the rate of memory bloat with successive system dumps of the process. To add the missing release call it shuffled around some existing instructions to a region of padding bytes in the driver and then called into those; this freed up the bytes necessary for the instructions to call the release function. 44 bytes are written across three spans to make the fix, and this is a verifiable fix that I was able to apply without disabling the system integrity protection — an even better delight.
This has been quite possibly my favorite AI-assisted project. There is no way I could have imagined doing this work myself or having traction with Fujifilm to debug and fix this issue, and yet now I can have video calls run on for hours (were I to want such a thing) and memory use by the driver is fixed; it doesn’t fill up and then purge all of my RAM.
A special thanks belongs to Automattic for providing this space in which to learn and explore, to OpenAI who provided elevated access to their frontier models and made it possible to preview what a future of abundant AI might look like, and to the Jetstream2 project funded by US taxpayers who donated high-capacity compute resources to help improve the reliability and security of the WordPress project. I would also like to thank Dan Luu, who worked with me on this project and who taught me so much about practical generative/fuzz testing, and with whom I could never keep pace, in the best of ways.
Over the course of this time period I worked with GPT-5.4 all the way up to GPT-6-Astra, at ultra thinking levels on fast priority, and with Claude Sonnet 4.6–5.4. The earliest use came from Qwen3.5-397B-A17B, but I had also been running Qwen3.5-27B-4bit locally before the experiment started, and by the end was relying on Qwen3.6-27B-4bit.
I’m thankful for the chance to reach into the past and demonstrate ideas I’ve had sitting on the back-burner, as well as to look towards the future and prototype designs I want to see turn into usable products.
October 17, 2026
Matt: Anthropic Employment
How employment is changing at Anthropic is a fascinating read.
October 16, 2026
Open Channels FM: Open Web vs Walled Gardens, Simplifying the Difference
A straightforward look at what the open web is, how it started, and why it matters for digital communities.
Matt: Pushing Standards
We get a lot of flak at WordPress.org for supporting older PHP versions, but an area we’ve always pushed the frontier is in Web Standards, getting websites and browsers evolving together to make the web richer. Ever since I caught the religion from Zeldman, promoting more functionality in the browser has been a life mission.
It’s a little nerdy, but we wanted to do client-side media processing (use all that amazing Apple and Google silicon instead of burdening the poor servers) so we used something amazing Google created called Document Isolation Policy. When WordPress 7.1 “Mary Lou” shipped these features only worked in Chromium-based browsers and Mozilla and Webkit/Apple weren’t keen to support it, but since then Mozilla has expressed support and WebKit has withdrawn their initial concerns. WordPresser Adam Silverstein has been driving much of this work and opened a WICG issue to help move the standard forward and formally requested that WebKit add support.
Hat tip: Anne McCarthy for helping with this post.
(If you want to see other crazy stuff we’re doing in browsers, check out WordPress Playground, I think it’s actually the perfect web development environment for agents, which can then publish to Spacefast.)
October 15, 2026
WordCamp Central: WordCamp Jinja 2026 Recap: Three Tracks, Two Days and Creative Currents on the Nile
On 19th and 20th September 2026, the WordPress community gathered at Civil Service College Uganda, a venue close to River Nile, for the fifth edition of WordCamp Jinja. The event brought together more than 300 diverse participants across 2 days and 3 parallel tracks of sessions full of learning, collaboration and connection. In a city known for its flowing waters, creativity and ideas flowed too, as participants shared their experiences, explored new possibilities with WordPress and built relationships that would carry beyond the weekend.
Our theme, “Embrace Creative Currents on the Nile: Where Inclusivity Fuels Creativity,” reflected the mix of people and ideas in the room. Students sat alongside developers, designers, writers, educators, entrepreneurs and experienced WordPress contributors. Across three parallel tracks, everyone could find a way to learn, share or build.

Students and Creatives at the heart of WordCamp Jinja
Nearly half of this year’s participants were students. Their presence was felt throughout the event, from the speaker sessions to the labs and hackathon tables. We had students from primary schools, secondary schools and universities joining us for this year’s WordCamp.
Some came to explore WordPress for the first time. Others arrived with projects, questions and skills they wanted to develop. Sharing the same spaces with people already working in technology and creative fields gave them an opportunity to learn directly from practitioners and see where their own interests might lead.
One student in attendance found a creative way to remember his experience. Fascinated by the WordPress ecosystem, its generosity and inclusivity, he drew all the sponsor logos by hand so he could remember them after the event. His drawings became a personal record of the community he had encountered at WordCamp Jinja, a small but memorable expression of the curiosity WordCamp Jinja inspired.
Bringing young people into the community has been a continuing part of WordCamp Jinja’s work. Last year’s edition at Jinja Senior Secondary School brought the event closer to students; this year, their participation remained central even at a different venue. We hope the relationships formed over these two days continue at Jinja WordPress Meetups and in the projects students choose to pursue next.
Event highlights
Diverse Speaker Sessions
Our speakers brought different backgrounds and experiences to the stage. Sessions opened up conversations about WordPress and the wider web, including how people use technology to create, teach, solve problems and build livelihoods.
The value of these talks was in the experiences behind them. Speakers shared what they had learned through their own work, answered questions and gave attendees ideas to take back to their studies, organisations and businesses. Thank you to everyone who prepared a session and made the journey to Jinja to share it with us.


Charity Website Hackathon and Contributor Sessions
The Charity Website Hackathon returned as one of WordCamp Jinja’s most practical activities. Participants and facilitators worked together on WordPress projects for organisations seeking to establish or improve their online presence. The teams had to think about real needs: what information a visitor should find, how to organise it and how the organisation could keep its site useful after the event.
For newer participants, this was a chance to learn by working through a real project with support close at hand. For experienced developers and designers, it was a chance to mentor others and put their skills to work for the wider community. The work begun at the hackathon can continue beyond the conference as teams and organisations develop their websites further.

Contributor activities connected that local work to the wider WordPress project. Attendees explored the idea that contributing to open source goes beyond writing code: people can help through photography, translation, testing, documentation, training and community work. There were a lot of new contributors who were taken through the contribution journey by table leads. We hope that for those that took their first steps, WordCamp Jinja will be the beginning of a longer contribution journey.

Hands-on Labs
The Hands-on Labs offered a different pace from the speaker sessions. Instead of only listening, participants could practically follow a facilitator on state of the art computers, try something themselves and ask for help when they needed it.
That kind of guided practice matters, especially for people who are new to a tool or trying to turn an idea into something they can build. Thank you to the facilitators who prepared the activities and worked directly with participants, and to the volunteers who helped make the sessions run.

Memorable moments, connections and networking
Some of the weekend’s most useful moments happened away from the front of a room. Over lunch, in the corridors and between activities, attendees met people from other communities, exchanged ideas and caught up with friends they had met at earlier WordPress events.


For a student attending for the first time, a conversation with a developer or designer can make a possible career feel closer. For returning community members, it was a chance to meet new collaborators and hear perspectives they might otherwise miss. Those connections are part of what keeps WordCamp Jinja going after the closing session.
Celebrating at the Source of the Nile
The celebration continued at Source of the Nile for our after-party, where attendees, volunteers, speakers, facilitators, sponsors and organisers were welcomed to the Source of the Nile. Unbeknownst to them, there was a surprise awaiting: an after party aboard a double-decker boat. The boat ride took them on a tour of Lake Victoria and finally landed at the actual source of the Nile itself, where they learned about its history before taking time for photos together.
The Nile has been part of WordCamp Jinja’s identity across previous editions. This year, gathering there brought our theme back into focus: people with different skills and experiences had come together, learned from one another and added something to the community.


The people who made it possible
WordCamp Jinja is built by volunteers. Long before the doors opened, the organising team was working on the venue, programme, speakers, communications, sponsorships, registration and practical activities. During the event, volunteers welcomed attendees, supported speakers, guided participants and helped the different spaces run smoothly.
To our attendees, thank you for showing up ready to learn and share. To our speakers and facilitators, thank you for the time and care you put into your sessions. To the hackathon teams and contributors, thank you for building and giving back. And to every organiser and volunteer, thank you for the work people saw and the work they did not.
We are also grateful to our sponsors Jetpack, Hostinger, WordPress.com, Woo, Hosting.com, SEOPress and Infinity Computers and Communications Company (i3c) and to our continued local community partners for supporting an accessible gathering for people at different stages of their WordPress journey. Their support helped bring this fifth edition to life.

Relive the weekend and keep in touch
You can explore photographs from the event in our WordCamp Jinja 2026 photo album:
https://photos.app.goo.gl/Fd61HxxyNT8xK4Ni7
WordCamp may be over, but the learning continues. The Jinja WordPress Meetup will keep bringing people together to share skills, contribute to WordPress and build on the projects and relationships started here.
Thank you for embracing the creative currents with us. See you at the next WordPress Jinja event!
bbPress: bbPress 2.6.20 is out!
bbPress 2.6.20 is a security and maintenance release. Everyone running bbPress should update. 
This release strengthens topic and reply password validation and keeps bbPress post shortcodes literal in ordinary WordPress content loops. It also adds a site-wide Forum Status setting with Open, Closed, and Frozen modes. Existing sites remain Open unless that setting is changed.
The maintenance work improves BuddyPress profile actions, group topic routes, activity visibility, and group-forum access. It also restores compatibility for subscription links in third-party theme packages, preserves moderation forms after validation errors, and includes fixes for notifications, converters, widgets, profiles, topic and reply administration, and restricted-content visibility.
bbPress 2.6.20 still requires WordPress 6.0 or newer and PHP 7.2 or newer, and is tested through WordPress 7.1. The database version remains 264, so no database upgrade is required. The 2.6.20 upgrade notes cover compatibility details.
These changes are also in the 2.7 development branch, which remains 2.7.0-alpha-4. Thank you to ahillmortons, alejandroescobar89, bor0, bradleyt, chefranov, dd32, deborah86, Dermes, diegootgs, dilip2615, fraph24, hardel, imath, immeet94, iworks, jgasba, josephscott, konnektiv, lmstearn, mehrazmorshed, michael8888, mike80222, obenland, Palagrin, peopleinside, r-a-y, robin-w, SirLouen, tobifjellner, wpturk, and zaerl for reports, patches, testing, and review.
Download bbPress 2.6.20 from WordPress.org, or update from your WordPress dashboard.
Open Channels FM: The Hidden Dependency Problem in Open Source Infrastructure
When we think about what keeps the Internet humming, most of us imagine massive data centers and super-fast connections. Fewer people realize that our everyday digital experiences often depend on the efforts of a very small group of individuals. Recent analysis revealed that in many essential open source projects, just one or two people are […]
October 14, 2026
Open Channels FM: Rethinking Access and Dependence in Tech From AI Outages to Open Source Lifelines
Who maintains education AI, the backbone of software infrastructure, and a new open source document tool.
WPTavern: #237 – Robert Abela on WordPress Security and the Battle Against AI Threats
Transcript
[00:00:19] Nathan Wrigley: Welcome to the Jukebox Podcast from WP Tavern. My name is Nathan Wrigley.
Jukebox is a podcast which is dedicated to all things WordPress. The people, the events, the plugins, the blocks, the themes, and in this case, the state of WordPress security in 2026, and the battle against AI threats.
If you’d like to subscribe to the podcast, you can do that by searching for WP Tavern in your podcast player of choice, or by going to wptavern.com/feed/podcast, and you can copy that URL into most podcast players.
If you have a topic that you’d like us to feature on the podcast, I’m keen to hear from you, and hopefully get you, or your idea, featured on the show. Head to wptavern.com/contact/jukebox and use the form there.
So on the podcast today we have Robert Abela.
Robert has been working in IT security for 25 years, ranging from antivirus software to web security scanners, and for the past decade has been running Melapress. A company focused on WordPress security plugins, particularly around user visibility, authentication, activity logs, and 2FA.
Robert is here to talk about the 2026 WordPress security survey. This is an annual project now in its fourth, or fifth, year gathering data from a wide range of WordPress professionals across agencies, enterprise teams, freelancers, and product owners. The conversation today is focused on the biggest security challenges and trends facing WordPress users in 2026.
We start off with some sobering stats. Over 67% of survey respondents reported experiencing at least one security incident in the past year, and concerns about WordPress security remain high, especially among less technical users.
We chat about the disconnect between awareness of security threats and actually taking steps to mitigate them, such as breach recovery plans and team training.
The discussion also explored the different types of risks that worry site owners. Site downtime, defacement, reputational damage, data loss, and even legal compliance issues. How the shakeout depends on the type of site, whether it’s e-commerce membership, a news outlet, or a simple brochure site.
We also talk about the tendency for even experienced WordPress users to take a reactive approach, only addressing vulnerabilities after something has gone wrong.
Towards the end of the episode, we discuss the rising impact of a AI on security, the explosion of AI facilitated vulnerabilities, and the shifting landscape of risk and response. There’s a healthy dose of reality, some optimism about the tools and best practises available, and plenty of good advice, especially for smaller teams and freelancers who may not have access to enterprise level resources.
If you care about keeping your WordPress sites secure, or want to understand where the community’s biggest concerns and opportunities are in 2026, this episode is for you.
If you’re interested in finding out more, you can find all of the links in the show notes by heading to wptavern.com/podcast where you’ll find all the other episodes as well.
And so without further delay, I bring you Robert Abela.
I am joined on the podcast by Robert Abela. Hello, Robert.
[00:03:48] Robert Abela: Hello Nathan. Thanks for having me.
[00:03:50] Nathan Wrigley: You’re very welcome. Nice to have you with us.
We’re going to chat today about internet security, but we’re going to be looking back over the past year, so the year 2026. Robert, can tell us a little bit about the company he founded, works for, and so on. It’s called Melapress, you can find out about that in just a moment.
But I would like to draw your attention to something which is going to really be the fulcrum of what we talk about. It is their 2026 WordPress Security Survey. Now, the easiest way to get that is probably to go to wptavern.com, search for the episode with Robert in it, and I will make sure it is linked in the show notes there.
But it might be a good idea to read it, because in about 10 minutes, you’re going to be able to capture absolutely everything that we’re talking about today, and you’ll get all of the data and, what have you. But that’s going to be the point of this episode, summarizing what happened in the security space in WordPress in 2026.
Robert, I guess there are a few areas in the WordPress space where it’s pretty important to know that we know, that you know, what you’re talking about when it comes to security, because we don’t want to have a lot of hot air from somebody who’s not experienced. So it’s an opportunity for you really to give us your bio and tell us a little bit about what you’ve been doing in the WordPress space, particularly around security, the companies you’ve worked for, the things that you’ve founded and so on. So over to you, Robert.
[00:05:07] Robert Abela: Thanks. I’ve been working in IT security for twenty-five years. I’ve always worked for software companies, software startups which worked in security industry. We used to do antivirus software, web security scanners, et cetera. I’ve had different positions. I started as systems engineer, QA, product management, project management, almost any field.
Anyway, and the last ten years I founded Melapress, and it’s a WordPress plugin business, and basically we develop a number of security plugins for WordPress. The security we do, we don’t do the typical firewall malware, et cetera, like the other, brands. We mostly focus on user visibility and authentication. So basically we have an activity logs plugin, and we also have a plugin for 2FA, passkeys et cetera. So we are focusing much more, on what happens post login once someone logs into WordPress, rather than the whole hardening and protection.
[00:05:56] Nathan Wrigley: Thank you for that. So anybody that’s interested, anything that we mention today, including the URLs of the companies that Robert has just mentioned, so Melapress, you’ll be able to find those in the show notes as well.
So the 2026 WordPress Security Survey, how many times have you actually run this? So obviously we’re looking at the 2026 version. Have you done this a couple of times and refined the way that you’ve done it and the way that you’ve surveyed over many years?
[00:06:21] Robert Abela: Yes. I’m not sure if this is the fourth or fifth year. But yes, we do every year, we’ve had more respondents. This year, by the way, it was the highest ever with 219 respondents. We had more, but before we publish all the results, we go through the sheet. Maybe there are some duplicates. Maybe some of them are not correctly filled in, et cetera.
But yeah, we’ve been doing it for around four years, and we’ve also fine-tuned from where we gather the data. For example, the first year, we’re only sending our newsletter basically, but this year we’ve done a lot. We’ve promoted the survey through third parties. We’ve gathered responses from WordCamp Europe, in person, through a number of other conferences, et cetera.
So while there is still a percentage that most probably are our users or our clients, still the biggest percentages is spread out to a wide range of different type of WordPress users, ranging from people who work for agencies, developers, designers, but also people who work with WordPress in bigger enterprises or businesses.
[00:07:15] Nathan Wrigley: Okay, so yeah, caveat emptor. With that in mind, the limitations, or otherwise, of the numbers that you’ve got represents what you’ve got in this survey.
And essentially, what it boils down to is a, it was kind of a bunch of questions which then led to a bunch of information being spat out the other side. And I’ve summarized it into about 10 bullet points. It may very well be that I’ve missed a few bits and pieces, but be interesting to go through, and you can lend your experience as to whether or not there’s been any change, whether things have got worse, whether things seemingly have got better.
We’ll begin, if it’s okay with you, with the top item, which I suppose, came out, which was a concern around WordPress’s security, or the things that can happen around WordPress and security. And what came out of it was that 7.85 out of 10, so 78 and a half percent, I suppose you could describe it as. They were developers who were expressing basically that they were concerned.
Now, I don’t know if you have more telemetry, like what concerned means, but off the face of it, that seems like quite a high number. If the platform that you’re using to build websites, you are in the sort of mid-70s concerned, is there anything you wanted to add to that or is that just the sort of top level statistic?
[00:08:28] Robert Abela: No. That was like a top-level statistic, a question we ask, like if people are concerned or they have worries about their WordPress, the security of their website.
What’s funny is the last few years, the level of concern has been the same. However, also we’ve noticed that people who have some sort of recovery plan, et cetera, also remains the same. So the level of concern has remained the same. So the majority of people know that something can happen to their WordPress website, especially now with AI, et cetera. It’s even more, things are moving much faster.
However, it seems like people are not taking the next step, as in like taking action to make sure nothing happens. What I’ve noticed as well, once we break down those who have concerns and what job they have, if they’re developers, or with their security people, et cetera. There’s this correlation, like, the more informed someone is, the more is involved in the tech aspect of the website, the more understanding they have on how things work, the less concerned they are.
So maybe it could also be education or awareness because of course, if you don’t know about how something works, then of course you are much more concerned. How you’re going to protect it? However, if you are, let’s say, a developer and has an understanding of sessions, cookies, the usual things, like passwords, maybe you’re a bit less concerned because you feel you are a bit more in control of how you can protect your website and what you can do.
[00:09:39] Nathan Wrigley: It seems like on the face of it, I should say, it seems like 78%. It seems like quite a lot.
[00:09:44] Robert Abela: Yes.
[00:09:45] Nathan Wrigley: If I had any kind of intuition, let’s say I was to go out into my car and drive around the street, if I thought that 78% of the time there was going to be some potential accident. Or I was worrying of the time about the possibility of an accident, I don’t think I’d be getting in the car. So it’s kinda curious. But, let’s move on.
So the next data point that dropped out was 67.7%, so let’s call it 68% of respondents. Now this is fairly shocking, and maybe this number will actually start driving up in the years to come, and we can get into that later.
68% of respondents had experienced at least one known security incident, with many multiple incidents. Now, that really is shocking to me. Closing in on 70% of people have had some kind of incident. I don’t know what, or maybe you do, what the magnitude of that is, but did that surprise you? Did that seem like a really large number?
[00:10:38] Robert Abela: 67.7 of all respondents, correct, they reported one security incident. I’m not surprised because almost everyone I speak to at WordCamps, even non-WordCamps, other events, someone down the line has had some security issue. Not just with WordPress, but especially with WordPress. And the funny thing, it’s not even funny, but 13.2% of those are repeat targets, which means they have experienced more than five security incidents.
Now, why does it happen? There are a number of reasons. Outdated software, lack of user awareness. In fact, what’s really more concerning is, I have some numbers here actually I can tell you. Yes, we’re still looking at some other statistics. Only 27.9% reported like they have some sort of training for their users. And only 37% use logs. At least 2FA’s a bit higher, it’s around the 40% something. I don’t have the exact number right now.
So yeah, so I’m not surprised because there is still a lot that can be done from website owners, from agencies, from everyone, to make sure we take down that number, and not everyone. Or so not the majority of people experience some sort of security incident on their website.
[00:11:41] Nathan Wrigley: Yeah, it’s curious. It’s not really a conversation. When I’m at events or chatting to fellow WordPressers, security is not the default conversation that I have, because I’m not a security person. So I end up chatting about, I don’t know, custom post types and how to do various things that I’m doing. Maybe podcasting in the WordPress space or something along those lines.
You, I guess, are having these conversations, and it’s very much in the territory. It’s in your wheelhouse. And so maybe it’s not a surprise to you that 67-plus percent of people have had something in the last year. But, on the face of it, that just seemed like so many. If I see 1,000 people at a WordCamp and I think, “Well, 670 of those have had a problem during the course of this year,” gosh that really does seem like a systemic problem.
And I know that outside of the WordPress community, WordPress gets a bit of a hard rap, on the security front. It’s insecure and what have you, and, all of the caveats. We know that really isn’t typically the case for WordPress Core. Tends to be the addition of code and plugins and themes that adds that on top. But I’m still surprised, feels almost like if the mainstream press got hold of your survey and just pull out that one statistic and bandy it around, it doesn’t feel great, if you know what I mean.
[00:12:53] Robert Abela: Yes. I think WordPress gets a lot of bad rep also because it’s very popular. As in like pre-WordPress, I’ve used web servers before as in like custom PHP websites, .NET, IIS, Apache, et cetera. Websites used to get hacked as well in the thousands. The thing is that you couldn’t point your finger to one type of website, you know because they were all custom. So these problems have been happening since we started having websites, quite frankly.
With WordPress, unfortunately it happens and we have a bad rep because I think there are two things. Look, first of all, it’s very popular, so it’s always there. If WordPress power is around 42, 43% of the, or maybe it went a bit down, but anyway, let’s say 40%.
[00:13:30] Nathan Wrigley: Roughly, yeah.
[00:13:32] Robert Abela: Yeah, The chances, for every 10 websites, four of them are going to be WordPress. That’s a common denominator. So of course, WordPress is going to get a lot of attention.
I also think, again, goes hand in hand with how many people have security concerns. WordPress has made it very easy to launch your own website, which is a good thing. However, of course, those same people who launch their own website, maybe they don’t have the technical understanding and experience what it takes. Because setting up a website’s one thing, but keeping, managing a website for a year, two, three, and growing it, adding new functionality is another thing. So most people might not have the experience that they have, so of course, it’s much easier to find security issues with these type of websites.
[00:14:10] Nathan Wrigley: Okay, we’ll move on anyway. So we’ll talk about the concerns. So you’ve obviously polled your recipients of the survey about the kind of things that they were worried about. So what are the outcomes that they fear the most, if you like?
And website availability, so the taking down of a website came in at number one, with 55.8. And then in no particular order, but these are the two that I picked out. The fear of being defaced, so the website in some way being amended, or there being some reputational damage because of what the amendment was. I don’t know, maybe there was some imagery, or some slightly political content that ended up on your website.
That was just slightly south of the availability, so that was 54.2%. And then dropping a full 10%, so 46.4%, was the worry about data theft or loss. Frankly, I’m not surprised by that. I guess any developer’s nightmare is their website actually disappearing off the internet. That’s number one, so that doesn’t surprise me.
I remember in the day, 15 years ago, defacement was the thing. Honestly, I can’t say that I’ve been browsing the internet recently and seen something that’s been defaced. It seems like the hackers have all moved on. Maybe there’s things buried in the source code that I don’t know about.
Yeah, it doesn’t surprise me that the availability is the main thing. But I am surprised that data loss comes in third, if you like. I personally would have had that as number one, especially, if you’ve got a, I don’t know, an LMS, or you’re connecting with a CRM, or you’ve got form data which potentially is capturing something personal that the GDPR would worry about. So there’s no question, just if you want to comment on those particular things, go for it.
[00:15:42] Robert Abela: No, definitely. Those are the numbers based on all the respondents. But if you start breaking down the numbers, there’s more nuance to, to these things. So for example, if you look, those who are concerned about website availability, or defacement, are usually those who have content websites. Mostly based on content, news, magazines, et cetera. Those who are more concerned about financial loss or data theft are more the e-commerce websites.
[00:16:08] Nathan Wrigley: Oh that makes sense. Yeah.
[00:16:09] Robert Abela: The membership websites, et cetera. In fact, the membership websites are as well more concerned, for example, about compliance because of privacy. So those numbers, like fifty-five point eight percent, those are from the all respondents. But as soon as you break all that down, it differs a bit on the type of website you have.
And it’s expected because if you have an e-commerce website, of course you are dealing with billing details, payments, and all this stuff. If you have a membership website, maybe you are also dealing with payment details, but you are also dealing with much more data. Maybe you have some sort of internal chat. People are sharing their addresses on it, their personal information. So that you are more concerned about GDPR or any sort of compliance, et cetera.
But if your main selling point is if you have a content website, a news website, and your main selling point is your website being available, then of course that is your biggest worry.
[00:16:53] Nathan Wrigley: That’s an interesting split of the data there. That makes perfect sense, of course, now that you say it in that way it really is obvious.
So that was you polling your respondants respondents there, and you were trying to figure out what their worries were and what they were into and all of that kind of stuff.
And then we sort of to move to a different realm where despite all of that being said, so, you know, got a lot of people worried. We’ve outlined some of the different worries that they have, depending on the type of website that they’ve got.
From all of that, if you’d have ended the survey there, I would have assumed at that point that everybody had something in the back pocket to pull out, an SOP or something like that, to pull out in the event of an actual problem. If data theft is apparent, we do this. If the website goes down, we do this. But your survey reveals entirely the opposite.
So the high numbers on the one side, the fear numbers, are not mirrored by the what we’re going to do about it numbers, because you go straight into the high 20s, so 27.9% had a breach recovery plan. So how to get back from a problem with your website being, let’s say, hacked, let’s use that word. And 26% provided some sort of training for their team, some sort of security team training, that kind of thing.
Again, does that surprise you? You’re in this space. Maybe that’s really typical, but given the high levels of concern, there seems to be a real disconnect with what we’re going to do about it. That’s curious.
[00:18:18] Robert Abela: I’m not surprised, in the sense, it’s very common. The majority of people, especially nowadays, there’s much more knowledge that, yes, websites can be hacked, this can happen. However, that doesn’t translate. People don’t have the, I don’t know if it’s the resources, the means, the time to actually take action on it, to prepare some things. So, I’m not surprised.
Again, similar to what we discussed before, there’s a bit more nuance to these type of numbers because you said only 27.9% has a breach recovery plan. Actually, that’s based on all the respondents, but typically the number is much less, because when you look at it, from the respondents, from all those who have a security breach, from those 27.2%, 70.2% which have control in place are corporate or brand websites, which means they have their own in-house team. Only those, 70% of those have their own, have their activity logs, have their firewalls in place, have a recovery plan in place, et cetera.
So the number of, let’s say, the non-branded, the smaller websites, yeah, they have absolutely nothing. They have no sort of recovery plan or anything like that. In fact, the numbers are much smaller. Only 23% of those websites typically have some sort of recovery plan.
[00:19:23] Nathan Wrigley: Okay.
[00:19:24] Robert Abela: I’m not surprised because usually, especially if you’re an enterprise, or a bigger business, you are bound by more compliance. Maybe you have more security people on board who are much more aware what can happen of what they need to do. But yeah, the average website doesn’t have these things.
[00:19:38] Nathan Wrigley: Yeah. I wonder if your data here might be skewed by the type of correspondent that you got. So for example, who knows how many blue-chip companies, have submitted to your information gathering here. Perhaps not many, but maybe you got lots of WordPress community members, and so the data might be skewed in that direction. But that’s an interesting point. So dependent upon the nature of the website and the type of team they have behind it.
But it is still, regardless of all of that, it is still quite low. And I was using my analogy earlier about insurance, and I think that applies here. Insurance is the most uninteresting thing to purchase because you spend this money and, let’s say for example, you got home insurance. I would imagine most people typically go through a year and they never make use of it. Sorry to anybody listening who has obviously had to make use of that. But the moment you need it is the moment that you’re glad of every single penny that you’ve sunk into that, and I guess that applies here. If we can persuade people to get that data breach recovery plan, whatever it may be, have that in your back pocket, that would be a useful thing to have.
[00:20:38] Robert Abela: Yeah. As I’ve said in the beginning, I’ve been working in IT security companies, security software companies for 25 years. All of them, the most common sales opening, like sales reason, like people coming to us like, “Hey, this happened, so now I need this.” They’re always after they’ve been hacked, after they’ve been a leakage, after there’s been something wrong.
Very few proactively come and as I said, like the bigger enterprise companies, because they have certain regulations and stuff and certain budgets that they invest in these things. But the average website, yes, first they have to experience something, and then. I think it’s, in all fairness, I think it’s common human nature. It’s not just about IT. We tend to be all humans. We tend to be like, “Oh, we’ll see later,” and then if it happens, “Ooh, I should have…” it’s always like that.
[00:21:17] Nathan Wrigley: Well, there’s also that calculus of how much time does it take to recover. So for example, if you’ve got a brochure site, and you’ve got backups going back for many many months you can restore to a point that you’re fairly sure that everything was actually fine, and the breach has been mitigated by going backwards in time. But it’s just all the wasted time. It’s the wasted time going through the backups and seeing, okay, is this backup, does it have the malware in as well? Okay, that one does. What about this one? What about this one?
And there’s no knowing how long that’s going to be, and the minute you step, as you said, into e-commerce and you’ve got transactions happening every couple of minutes, and then you’ve got receipts and you’ve got to fulfill those orders, and somehow, oh boy, yeah.
[00:21:59] Robert Abela: Yes. Then it’s a different ballgame. Yeah.
[00:22:02] Nathan Wrigley: Different ballgame isn’t it? Yeah.
Okay, so the next point that we’re going to move on to is actually one that you probably just made. And it’s that the detection in most cases, well actually not most cases, in many cases. So 42.6% of your respondents said that their detection is mostly retroactive. So that is to say the thing has already gone wrong. Somebody in the 42.6% of the case is because they see something on the website. They’ve noticed that something isn’t quite right, something looks out of order.
38.4% because they were actually inspecting the logs. That tells me that whoever’s inspecting the logs is doing diligent work. That’s kind of interesting. So don’t know if you want to comment on that, but basically a lot of people are figuring this stuff out after the thing has happened, as you described, not before the thing has happened.
[00:22:51] Robert Abela: Yes. So there are four criteria. So 42.6%, as you said, is common website behavior, either detected by their team or by clients. 38.4 via logs. Now, the logs is a bit, it can be reactive and proactive, because with the logs, you can actually, in fact, we have some notes on this, but I don’t have the exact numbers right now. Because some of them were actually by someone analyzing the logs, but some of them were actually because someone has configured notifications based on the logs, like a sort of intrusion detection system.
And so if, I don’t know, if X login happens after X time, whatever, please send me an email or an SMS, and that, it’s still reactive in a way, but at least they could act right away as soon as it’s happening. Yeah.
[00:23:31] Nathan Wrigley: Yeah kind of proactive reactive, isn’t it? That’s a really interesting subcatagory.
[00:23:33] Robert Abela: Exactly, yeah.
[00:23:34] Nathan Wrigley: Yeah.
[00:23:34] Robert Abela: So yeah, but yeah, it’s still reactive because then you have 35.6% they knew through their web host, and 30% they knew through some sort of malware scanner alerts on their website, et cetera.
[00:23:45] Nathan Wrigley: Okay. Again, just kind of interesting data coming out.
So the next one, incidents most commonly resulted in downtime for the website. So that’s pushing up to 70%, 68.4% of whatever happened, resulted in some downtime. And then I don’t have the numbers for the following data, but I guess it decreases from here.
The next thing was reputational damage. That was a result of some sort of incident. And then search engine ranking is affected. That’s an interesting byproduct.
This one’s brutal. Client trust disappearing. That’s really interesting. And then in some cases, lost revenue. I imagine the lost revenue is being described as in some cases, because, as we described earlier, if you’re dealing with revenue, you’ve probably got more bulletproof security measures in place.
But the ones that sort of jump out to me there aren’t the downtime, because I would’ve assumed that. It’s really the curious byproducts of things like the reputational damage, the search engine damage. You can’t really get your hands on those, can you? There’s no real way of knowing what that’s going to look like or feel like, or how that’s going to affect your business this year or next year.
Just to know that, you wake up one morning to discover that you were in first place on Google after six years of hard SEO work, only to discover that you’re now in fourth and descending fast, that’s pretty brutal.
[00:25:01] Robert Abela: Yes. And in fact, if you break down those numbers a bit more, like 45.9%, there’s loss of search engine ranking, and that happens usually when search engines detect you have issues. I don’t know if you remember, Google used to have that page sometimes.
So that happens. When that happens, when the search engine themselves realise there’s an issue, you lose a lot of rank. The penalty you get there is very heavy. In fact, only 14.5 of those who have had some issues with the website has lost ranking because they have discovered their issues before the search engine did.
So again, that’s why you should be a bit more proactive because if your search engine finds out before you, the penalty, as you said, and you cannot really quantify it because God knows how long you will remain. As you said, if you were position one for six years in a row, now one fine day you’re on the second page, God knows how much work you need to go back up, and you cannot even calculate what the revenue loss is.
But when it comes to revenue loss, again, it’s the same. There are some websites, I’ve seen some websites where like they generate $70,000 per hour. So for every hour down, that’s $70,000 gone.
So yeah, there are lots, and of course, the reputation, on top of the reputation, there’s also compliance and legal consequences, especially in the US. Things are becoming much stricter now. If you had some issue, some customer data has been leaked, you have problems with the law, fines, and other similar stuff. So, the financial damage to all of this, of your website getting hacked, is very high.
Not just the reputation, losing customers, you might end up in court. You might lose your search engine ranking, and that is why most probably it’s a good idea to become a bit more proactive rather than reactive. Or it’s almost impossible to, there is no 100% secure solution, and that is why I think it’s very important to have good hardening, but also good monitoring, the whole process, the whole 360 degrees, the whole cycle.
[00:26:44] Nathan Wrigley: It’s such a curious industry that you’re in because, how to describe this? It would seem, or at least, it would be possible to perceive that this security survey is perfectly aligned with your business goals in a way. There’s loads of problems out there on the internet. There’s multitudes of ways that things can go wrong, and for every one of them, there’s, a WordPress solution out there.
But I know Robert. We’ve met many times before. I get the intuition that’s really not why you’re doing this, although somebody listening to this might have that sort of slightly, I don’t know, cynical approach that, Robert’s just saying this so that he can launch his Melapress products at you. Just put our minds to rest on that score. Why do you actually carry out this survey?
[00:27:25] Robert Abela: Good question. Actually, our plugins only address part of the security. There’s much more when it comes to firewalls, et cetera, that I still say hardening you still need. We don’t even cover it.
No, we do it, honestly, it started around four or five years ago, for me, it was just curiosity. It sounded like an interesting to do. Hey, let’s do a survey, just experimenting, et cetera. And we had very good response, and now we’re just, doing it honestly.
Like I really believe that by knowing, this is not just about WordPress security, about everything else. By knowing where other people are doing it wrong, you will learn from it. By knowing, okay, clearly I can see, for example, as we were saying, like seventy percent, seventy point two percent of enterprise and marked businesses usually have logs, usually have firewalls, et cetera. Maybe we should aspire more towards them and be more like the average website should have a bit more like things like that, and maybe they’re doing something right.
So yes, there is a lot to learn from surveys in general, not just this, any type of survey. There is usually a lot to learn. And that’s why we’re doing it as well, because from the first time we’ve done it, which started really as a curiosity project, we got so much good feedback. And actually the second year people were asking us if we are going to do it. Because yeah, people learn from these things.
I mean, of course there’s the benefit of it, hopefully it will promote as well a bit our plugins. But anyway, it’s going to promote all other type of security solutions. We are not, in fact, the survey is not tailored just for our plugin. It talks about everything. As I said, the whole security cycle. You have the hardening, you have the monitoring, updating, et cetera, and we only do one part of it, the monitoring aspect, basically.
[00:28:50] Nathan Wrigley: Before we move on to our sort of final bit, which I want to concentrate on AI, I’m just going to wrap up the security bit just by summarizing what comes towards the end. And it’s less about numbers, and it’s more about just conclusions that may have been drawn. But most of it, I think, would be fairly obvious from what we said. So I’ll just summarize it a little bit.
The first one is that e-commerce and membership sites tend to have greater security concerns and stronger practices. That kind of makes sense. I guess it reflects the nature of the business they’re in, and the kind of data that they’re holding, and the legal compliance that they may need to be concerend with.
In-house teams are more likely to have recovery plans. Again, I presume that’s fairly obvious. The boss, the head of the pyramid can sit down and say, “Okay, it’s your job now to crack on and do that. You’ve got a week to figure out all this sort of stuff,” and what have you. Whereas a freelancer sitting in their own office, there’s always regular work to be built, sites to be built and other things to do. So I can well imagine why that’s the case.
And sites, again, fairly obvious, sites with repeated security incidents tended to have stronger controls in place. Today, presumably, it’s a case of once bitten and all of that. Once you’ve actually had this nasty stuff happen to you, you’re pretty likely to make sure that does not happen again.
In summary, I suppose the reports really, the recommendations are focus on prevention, detection, and recovery rather than simply adding in more security tools, would be the way that I would describe it.
Okay, let’s move on then just before we finish. It is, as we’re recording this, it’s September 2026. In the more recent past, I want to say, I don’t know, the last two months, something like that, the WordPress security news bulletins have been on red alert really. We’ve had some charts being put out on social media which show the amount of vulnerabilities discovered, and also the amount of AI-based plugins that have gone into the repository. The supply chain attacks that have suddenly become a thing. A lot of it really because people can corral AI to do mischievous stuff and what have you.
I don’t really have a question, but I just wondered if you had a comment on where we are in September 2026, because it does feel as if there’s quite a lot of, there’s a lot of scope to be very doomer at the moment. It almost feels like the AI is winning the arms race, but maybe that’s not what you’re thinking from your end.
[00:31:04] Robert Abela: No, it looks a bit negative. I wouldn’t say AI is winning the race. Actually, people with malicious intent using AI are winning because AI is neutral in a way, like it depends on what people ask the AI to do.
[00:31:15] Nathan Wrigley: Yes.
[00:31:16] Robert Abela: But it is worrying, yes. The graph you are mentioning, I saw a graph shared by John Blackbourn, yeah, about the number of issues reported in the HackerOne WordPress vulnerability program, which is insane.
[00:31:28] Nathan Wrigley: Yes.
[00:31:29] Robert Abela: And they received more reports in the last week than they ever did in a whole number of months. So yes, it is worrying. You can look at it both ways. The same way attackers can use AI to find issues. We are doing it ourselves as well, quite frankly, because whenever there’s a new model out there from all of these vendors, most probably attackers are going to use them to scan our code, et cetera. So we’re doing it as well.
We always used to do the manual security analysis, et cetera, but now that we have AI, with every release, we just hammer the update and try to find as many issues as we can.
The reality is also that some, if not many of these vulnerabilities are not actually so easy to exploit. Like it’s really, the stars really have to align and it’s really, but still, it’s better safe than sorry. Because even though today it might be difficult to exploit a particular issue, in six months’ time, we might have technology that might make it very easy to exploit this type of issue.
It looks negative, but the same tools that attackers have, malicious users have, we have them as well. So it’s up to us to use them and be ahead of the curve, and use them proactively ourselves and before every update, during the whole development cycle. We should use them more often to make sure at least that we cover what other people can find before us.
[00:32:35] Nathan Wrigley: Yeah. I suppose the bit that I find curious is the optics of it. So, there was always this universe in which people would be able to throw dirt at WordPress because you know WordPress isn’t secure, and we talked about that earlier. It’s usually plugins and very rarely Core. Plugins, themes, additional code, what have you.
However, given that it would appear that people can stack 14 overlapping problems and create this one vulnerability from things that probably humans would never have conceived in the past. That then just lends into this narrative of, well there’s this deluge, this tidal wave of things that are coming at WordPress.
So I woke up this morning to discover in my feed BleepingComputer. I don’t know if you’ve seen this one yet today, but BleepingComputer have got an article with a CSV attached to it about yet another WordPress thing. And it just feels like that sort of day in, day out, there’s just another and another, and it’s that narrative that, that concerns me. It’s just that it gets away from us, that there’s one this day, there’s one this day, one this day, one this day.
And having to explain, “Look, calm down. That one was nothing. Okay, calm down. That one was also nothing. Okay, yeah, that one was something, but that one was nothing, that…” It’s just that constant fighting the narrative in an era where every day something seems to be out in the press, a problem that WordPress. Do you capture what I’m saying there?
[00:33:57] Robert Abela: Yes, no, and no wonder we get negative rep in the rest of the IT industry because, yes, we do get these news, and the numbers are very big. If you find a vulnerability in a plugin that has half a million installations, all of a sudden you see the news, “Oh, half a million WordPress websites are vulnerable to X.”
Unfortunately, yes. The thing is, WordPress in general, it’s very secure like. There are so many I’ve seen in my life, I don’t know how many custom web applications I have seen that are horrible in terms of security, like really horrible. It’s just because, of course, no one is seeing these because this might be a website in millions of websites, so no one is targeting. But WordPress, because it’s a popular platform, is going to be targeted.
But yeah, because the numbers are big, yeah, unfortunately, we do have a bad rep. And yeah, the news like to sensationalize things as well. So yeah, the rep is not good, no. But the reality is that it’s going to happen. It’s going to happen more often, most probably. It happened to us. All the vendors I’ve spoken to at WordCamp US and WordCamp Europe, they’re all the same. If you look at our plugins as well, maybe we used to get, I don’t know, maybe on average a vulnerability or two reported a year.
As soon as this whole AI started thing, all of a sudden within a month or two, you get like four, five, six reports like, “Whoa, what happened?” In just one week. It’s just reality. It’s up to us, as I say, we have to be more proactive. Of course, it’s easier said than done, but we have to be more proactive and try to use the same tools that attackers are using to make sure at least we detect them, yeah.
[00:35:13] Nathan Wrigley: Yeah, the bit that genuinely I find curious is what will be the calculus in terms of time that people can spend on this stuff. So as an example, if let’s say that by January 2027, many of us are having to spend a good proportion of every day, and by a good proportion, I don’t know, let’s say 30 minutes or something, browsing through the news to see if anything has cropped up. Or indeed to read the things that we know has cropped up because the fire hose of security news has gone through the roof.
This seems like it could happen, that we’ll all have to be mindful of it. And it’s just that sort of attritional wear and tear that, “Okay, really? Do I have to do this each and every day?” That will be interesting.
I suppose the flip side of that, curiously, is that it, how to describe this? It doesn’t do your business any harm because the more that people are concerned about their WordPress websites, the more security news there is, the more that they will be drawn to companies like yours. So it’s a very curious tightrope walk that you’re going to have to perform, I think as well.
[00:36:10] Robert Abela: Yes. Yes, it’s the reality. If I can do a shameless plug, at WordCamp US, I spoke about, WordPress user sessions and hijacking, and one of my lines was that all the things I had mentioned, but the talk is available on YouTube on the WordPress channel. All the things that I have mentioned, so many missed it, because if you look at user session hijacking, the bottom of it is all derives from user mistakes. A user making a mistake, that’s all it is.
And the reality is it all sounds dramatic. It all sounds like it’s the end of the world and apocalyptic. However, the reality is that, yes, nowadays, if you use a website, even as a user, you need to be aware of some basic things.
So yes, there are these news, and hopefully more and more people will become aware and more and more people need to become aware that yes, these are the dangers, these are like the risks of logging into a website nowadays. Of maintaining a website nowadays. It is. It’s like a double-edged sword. Like the news are making sometimes a bad rep for WordPress, but they’re also reaching more people that they need to wake up and say, “Oh, these are the risks, so we need to take action.”
[00:37:07] Nathan Wrigley: Yeah, it will be interesting in the face of AI vulnerability. It’d be interesting to see what the, let’s say hosting companies, let’s paint a target there. What they do to manage their stack, because obviously it’s going to be very important for them to make sure that the clients that they have. And how they position themselves in the news, and how they can portray the security solutions they’ve got. But as well as companies like you, you know, plugins and other firewall companies and things like that. Be interesting to see through 2027 how they manage that.
Okay. In which case we will wrap it up there. Just another quick reminder, go to the WP Tavern.com website, search for the episode with Robert Abela. You will be able to find the 2026 Melapress WordPress Security Survey over there. Download it, have a little bit of a look. And Robert, are you available anywhere online? Do you, other than Melapress’ do you actually make yourself available? And if so, where can we find you?
[00:37:58] Robert Abela: Yes, I’m active on LinkedIn, Robert Abela. I’m active on X.com, and I finally also have my own website. It’s more on personal things quite frankly, but yeah, it’s robertabela.me.
[00:38:08] Nathan Wrigley: In which case I will bury those in the bottom of the show notes as well.
[00:38:12] Robert Abela: Thanks.
[00:38:12] Nathan Wrigley: So that you can find those. Robert Abela, thank you for chatting to me today. I really appreciate it.
[00:38:16] Robert Abela: Thanks likewise.
On the podcast today we have Robert Abela.
Robert has been working in IT security for 25 years, ranging from antivirus software to web security scanners, and for the past decade has been running Melapress, a company focused on WordPress security plugins, particularly around user visibility, authentication, activity logs, and 2FA.
Robert is here to talk about the 2026 WordPress Security Survey, this is an annual project, now in its fourth or fifth year, gathering data from a wide range of WordPress professionals across agencies, enterprise teams, freelancers, and product owners. The conversation today is focused on the biggest security challenges and trends facing WordPress users in 2026.
We start off with some sobering stats, over 67% of survey respondents reported experiencing at least one security incident in the past year, and concerns about WordPress security remain high, especially among less technical users. We chat about the disconnect between awareness of security threats and actually taking steps to mitigate them, such as breach recovery plans and team training.
The discussion also explored the different types of risks that worry site owners, site downtime, defacement, reputational damage, data loss, and even legal compliance issues, how these shake out depends on the type of site, whether it’s e-commerce, membership, a news outlet, or a simple brochure site.
We also talk about the tendency for even experienced WordPress users to take a reactive approach, only addressing vulnerabilities after something has gone wrong.
Towards the end of the episode, we discuss the rising impact of AI on security, the explosion of AI-facilitated vulnerabilities, and the shifting landscape of risk and response. There’s a healthy dose of reality, some optimism about the tools and best practices available, and plenty of good advice, especially for smaller teams and freelancers who may not have access to enterprise-level resources.
If you care about keeping your WordPress sites secure, or want to understand where the community’s biggest concerns and opportunities are in 2026, this episode is for you.
Useful links
WordPress Security Statistics 2026: Melapress Survey Results
Matt: RIP Eric Binnion
For the next 30 days, a few billion of you will get an extra header in honor of Eric Binnion. The code in Nginx to do this is poetic:
add_header X-Remembering "Eric Binnion <https://friendsofericbinnion.wordpress.com/>" always;
Our design team will make that less AI and more humane in the coming days.
Automattic.com will have a mourning band for 30 days.

Eric was the 21st recipient of the Distinguished Janitor Award, Automattic’s highest honor, and in our hangs the last few months we’ve been talking about how to redefine and evolve it, which will happen internally at Automattic. One of the ideas was for the award to come with a physical memento, an etched tungsten cube. I don’t have many words so I’ll share something I wrote to Eric a few months ago when I gave him my cube when he was going through chemo.
Two Totems To Take With You
The first is a tungsten cube I keep on my desk. Its weight will surprise you, but tungsten is singular in having the highest melting point of any metal. That represents one of the things I admire most about you.
Tungsten has an atomic number of 74, its symbol is W, and it’s also known as wolfram.
My next post I’ve had in drafts for a while so please try to imagine me happy and promotional when reading it, but otherwise, I’m wrecked. Just going to soldier through because that’s what Eric always did.

Other Automattician posts:
- Jesse Friedman: The Loss of a Giant — Part One of Two.
- Matías Ventura: Remembering Eric, with a Walt Whitman poem.
- Beau Lebens: Remembering Eric, “I was lucky enough to be his first team lead….”
- Rémi Corson: Bon Voyage, Eric, “We got tattoos together.”
- Job Thomas: Remembering Eric.
- Big Legacy of Eric Binnion tribute site.
October 13, 2026
OpenStation Blog: I Deleted 168,000 Lines of Comments. My AI Agent Didn’t Notice
Almost a third of our source code was comments. I deleted all of them and asked an AI agent to build the same features on both versions of the codebase, three times each. The code it wrote was just as good with or without comments.
If you use agents on a real codebase and wonder whether comments help them, slow them down, or don’t matter, here’s what I found.
Why I tried this
In this video (around 23:07), Lauren mentions that they don’t let their agents write comments in the code. Our codebase, is the opposite: it’s full of comments, and most of them were written by agents.
So I wondered: are all those comments helping the agent, or are they just extra text it has to read?
The experiment in one paragraph
I made a copy of the codebase with every comment removed, about 168,000 lines in total. Then I gave the same task to the same agent on both copies, three times on each, and checked the results the same way. I did this for two tasks, a small one and a bigger one.
The results
Every run passed every check: lint, type checks and the existing tests, plus, on the bigger task, a hidden test the agent never saw. A separate AI judge scored each result without knowing which copy it came from (more on that below).
Small task: tile all open windows (score out of 19)
| Branch | Score | Tokens | Cost |
|---|---|---|---|
| With comments | 18.3 | 2.18M | $1.42 |
| Without | 19.0 | 1.71M | $1.04 |
Bigger task: keep a window on top (score out of 23)
| Branch | Score | Tokens | Cost |
|---|---|---|---|
| With comments | 21.7 | 9.06M | $3.84 |
| Without | 22.0 | 9.12M | $3.95 |
The numbers are averages of three runs. The score differences are within noise, and so is the cost on the bigger task. On the small task, the agent used about 22% fewer tokens without comments, which makes sense: there was simply less to read.
The bigger task had a trap. The pinned state has to survive a page reload, and the PHP function that saves the window session drops any key it doesn’t know. Miss it and the feature looks fine until you reload. That’s exactly the kind of thing you’d expect a comment to help with. All six runs found it, with and without comments.
Why one run is not enough
My first plan was to run each branch once. I’m glad I didn’t.
On the bigger task, the three runs with comments used 8.21M, 8.79M and 10.17M tokens. The three runs without comments used 7.01M, 9.70M and 10.64M.
If I had picked one run from each branch, I could have written two opposite blog posts. Comparing 10.64M with 8.21M, removing comments makes the agent 30% more expensive. Comparing 7.01M with 10.17M, it makes the agent 31% cheaper. Same task, same code, same day.
Agents are not deterministic. If you’re measuring one, run it more than once.
How I ran it
- The agent: Claude Code with Opus 5.5 at high effort. Same model and settings for every run.
- The two codebases: our main branch, and a copy with the comments removed. I compiled both and checked that the resulting code is identical. The only comments left are the ones the tools need to work, such as lint directives and plugin headers, about 800 lines.
- The tasks: two real features, with the same prompt on both branches.
- The checks: the project’s own lint, type checks and tests. On the bigger task, also a hidden test I added after the agent finished, so it couldn’t write code just to pass it.
- The judge: a separate Claude session read each change and scored it against a checklist written before the runs: does it work, does it follow the project’s conventions, does it have tests, and so on. The changes were labelled with random names, so the judge didn’t know which branch each one came from.
- The runs: three per branch per task, alternating branches so that time of day affected both equally.
My conclusion
For the agent, code comments don’t make a difference to the quality of the code it writes. They don’t help, and they don’t hurt.
So keep a comment or delete it based on what it does for the people reading the code, not for the agent.
This doesn’t prove comments have zero effect. I tested one model, two tasks and three runs per branch, which is enough to rule out a big effect, not a small one.
Next: comments made no difference, but removing our docs/ folder and AGENTS.md did. That’s the next post.
Appendix: data and links
- The codebase with comments
- The codebase without comments
- Exactly what was removed (GitHub may only show part of it)
- Two of the small-task runs as pull requests: with comments, PR 974 and without comments, PR 975
- Full results, all runs: results page
- If you want to see the experiment script and the rubrics, they are all here
- Lines of code, measured with
scc:
| With | Without | |
|---|---|---|
| Whole repository | 765,491 | 597,332 |
| Plugin source code | 408,527 | 280,421 |
Matt: Neal Stephenson Live!
Speaking of sci-fi authors, Automattic is hosting Neal Stephenson for a livestream about his new book soon, please tune in!
Neal was a big influence on WordPress! I got hip to him from Tantek. In the source code of billions of pages you’ll see this:
<link rel="profile" href="https://gmpg.org/xfn/11">GMPG is the Global Media Protocols Group, “an experiment in Metamemetics.” Inspired, of course, by the Global Multimedia Protocol Group that owned the virtual real estate in Snow Crash’s metaverse.
Eric, Tantek, and I were reacting to the idea that there should be a separate heavily-marked-up RDF or XML web, and that HTML couldn’t be extended or enriched with metadata in a way that was beautiful to both humans and machines. It was really an aesthetic war. (It later got more built out in Microformats.)
We should revisit some of those principles because the web could use more distribution right now.
Open Channels FM: Balancing AI Efficiency Costs and Value in Markdown Data and Open Source Security
In today's news, markdown streamlines AI input, AI-generated security reports increase workloads, and autonomous agent costs affect project efficiency
Open Channels FM: Open Channels FM Heading to the Web Summit 2026 in Lisboa
Next month in November, I’ll (Bob) be attending the Web Summit in Lisbon, Portugal. I have been to conferences in the past that have had attendance up to 15,000, but never one that has over 70,000 attendees. That’s a lot of people. A few months ago I applied for media creditation, unsure of their parameters […]
Matt: Board Agent
Automattic is always 5–15 years ahead of other companies, but things happen faster now. I predict other companies will start scrambling to add great writers to their boards, because, well, look at the headlines in AI. United’s board already has Walter Isaacson. Authors are awesome, akin to founders in the startup/tech ecosystem.
Public offer to all the great sci-fi/etc writers out there who I’m a huge fan of (Ken Liu, Neal Stephenson, Ted Chiang, Andy Weir, Ramez Naam, Kim Stanley Robinson…) but not as close to as Hugh (I was part of him meeting his wife, officiated one of their weddings), I offer my services as your Board Agent to negotiate compensation and contracts for you! 1% fee, donated to the WordPress Foundation or Locus Magazine. I’ve become a bit of an expert in board protections, dynamics, compensation, and such.
Aside: If you haven’t seen the Robert Caro / Robert Gottlieb documentary Turn Every Page, run, don’t walk to your nearest streaming service!
October 12, 2026
OpenStation Blog: What WordPress would have looked like in 1995
I’ve been wondering how far a theme can take OpenStation. Not just a wallpaper and a different color, but everything: windows, dock, menus, fonts, icons, layouts, etc. So I tried to make wp-admin look like two operating systems from a long time ago.

Retro 95 reimagines wp-admin as Windows 95. It even comes with a Start menu! And the classic clock sitting in the bottom-right corner is also there. You can try it live.

Retro 84 is the counterpart for Apple fans. It turns wp-admin into the first graphical OS that many people ever saw: the original Macintosh’s System 1. The beloved monochrome display, the classic pixelated font, and more! Check out the live demo.

And here’s a fun fact: every icon is pixel art typed into a text file, one character per pixel. The fonts were also made the same way, letter by letter.

Underneath, it’s the same wp-admin as always, just a few decades older.
If you want to build your own theme, the docs list everything a theme can change. Maybe it’s time for a proper Windows Vista comeback.
Open Channels FM: Building Stability Through Diversification in Tech Careers
In a fast-evolving tech industry, professionals are embracing diversification for stability and growth. This strategy fosters financial security, creativity, and adaptability, preparing individuals for unforeseen changes.
October 09, 2026
Open Channels FM: OCN Week in Review #5: Scale, Adaptation, Verification and Infrastructure
This week on Open Channels News, discover how AI is changing hardware, security reports, and gaming, plus the latest WordPress and enterprise data updates. Explore our concise wrap-up of major open source and tech stories, along with the recurring themes shaping the industry’s future.
October 08, 2026
Open Channels FM: Why Learning from Younger Colleagues Keeps You Fresh in Tech
To thrive in the evolving tech industry, professionals should engage with younger colleagues, embracing their fresh perspectives to foster adaptability, resilience, and ongoing personal and professional growth.
WordPress Planet
This is an aggregation of blogs talking about WordPress from around the world. If you think your blog should be part of this site, send an email to Matt.
Official Blog
For official WordPress development news, check out the WordPress Core Blog.
Subscriptions
- Aaron D. Campbell (feed)
- Aaron Jorbin (feed)
- Adam Zielinski (feed)
- Akismet (feed)
- Andrew (feed)
- Andrew Nacin (feed)
- André Maneiro (feed)
- Andy Skelton (feed)
- Bernie Reiter (feed)
- BuddyPress (feed)
- Carlos Bravo (feed)
- Carolina Nymark (feed)
- Darren Ethier (feed)
- Dave Smith (feed)
- David Baumwald (feed)
- Dennis Snell (feed)
- Donncha (feed)
- Dougal Campbell (feed)
- Felix Arntz (feed)
- Gary (feed)
- Gravatar (feed)
- Greg Ziółkowski (feed)
- Gutenberg Times (feed)
- HeroPress (feed)
- JJJ (feed)
- Jake Spurlock (feed)
- Jean-Baptiste Audras (feed)
- Joe Dolson (feed)
- Joe McGill (feed)
- Jon Surrell (feed)
- Jonathan Desrosiers (feed)
- Joseph (feed)
- Kelly Choyce-Dwan (feed)
- Lorelle on WP (feed)
- Marin Atanasov (feed)
- Mark Jaquith (feed)
- Matt (feed)
- Miguel Fonseca (feed)
- Mike Little (feed)
- Open Channels FM (feed)
- OpenStation Blog (feed)
- Pascal Birchler (feed)
- Peter Westwood (feed)
- Peter Wilson (feed)
- Ping-O-Matic (feed)
- Post Status (feed)
- Riad Benguella (feed)
- Tammie Lister (feed)
- WP Mobile Apps (feed)
- WPTavern (feed)
- Weston Ruter (feed)
- WordCamp Central (feed)
- WordPress Foundation (feed)
- WordPress.org blog (feed)
- WordPress.tv Blog (feed)
- bbPress (feed)
- mdawaffe (feed)
Last updated:
October 21, 2026 10:00 PM
All times are UTC.